diff --git a/docs/source/en/_toctree.yml b/docs/source/en/_toctree.yml
index adb0f0bf991b..e1a4a9247894 100644
--- a/docs/source/en/_toctree.yml
+++ b/docs/source/en/_toctree.yml
@@ -685,8 +685,6 @@
title: Sana
- local: api/pipelines/sana_sprint
title: Sana Sprint
- - local: api/pipelines/shap_e
- title: Shap-E
- local: api/pipelines/stable_cascade
title: Stable Cascade
- sections:
diff --git a/docs/source/en/api/pipelines/shap_e.md b/docs/source/en/api/pipelines/shap_e.md
deleted file mode 100644
index c683a53da7ba..000000000000
--- a/docs/source/en/api/pipelines/shap_e.md
+++ /dev/null
@@ -1,201 +0,0 @@
-
-
-# Shap-E
-
-The Shap-E model was proposed in [Shap-E: Generating Conditional 3D Implicit Functions](https://huggingface.co/papers/2305.02463) by Alex Nichol and Heewoo Jun from [OpenAI](https://github.com/openai).
-
-The abstract from the paper is:
-
-*We present Shap-E, a conditional generative model for 3D assets. Unlike recent work on 3D generative models which produce a single output representation, Shap-E directly generates the parameters of implicit functions that can be rendered as both textured meshes and neural radiance fields. We train Shap-E in two stages: first, we train an encoder that deterministically maps 3D assets into the parameters of an implicit function; second, we train a conditional diffusion model on outputs of the encoder. When trained on a large dataset of paired 3D and text data, our resulting models are capable of generating complex and diverse 3D assets in a matter of seconds. When compared to Point-E, an explicit generative model over point clouds, Shap-E converges faster and reaches comparable or better sample quality despite modeling a higher-dimensional, multi-representation output space.*
-
-The original codebase can be found at [openai/shap-e](https://github.com/openai/shap-e).
-
-> [!TIP]
-> See the [reuse components across pipelines](../../using-diffusers/loading#reusing-models-in-multiple-pipelines) section to learn how to efficiently load the same components into multiple pipelines.
-
-Make sure you have the following libraries installed.
-
-```py
-# uncomment to install the necessary libraries in Colab
-#!pip install -q diffusers transformers accelerate trimesh
-```
-
-## Text-to-3D
-
-To generate a gif of a 3D object, pass a text prompt to the [`ShapEPipeline`]. The pipeline generates a list of image frames which are used to create the 3D object.
-
-```py
-import torch
-from diffusers import ShapEPipeline
-
-device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
-
-pipe = ShapEPipeline.from_pretrained("openai/shap-e", dtype=torch.float16, variant="fp16")
-pipe = pipe.to(device)
-
-guidance_scale = 15.0
-prompt = ["A firecracker", "A birthday cupcake"]
-
-images = pipe(
- prompt,
- guidance_scale=guidance_scale,
- num_inference_steps=64,
- frame_size=256,
-).images
-```
-
-Now use the [`~utils.export_to_gif`] function to convert the list of image frames to a gif of the 3D object.
-
-```py
-from diffusers.utils import export_to_gif
-
-export_to_gif(images[0], "firecracker_3d.gif")
-export_to_gif(images[1], "cake_3d.gif")
-```
-
-
-
-
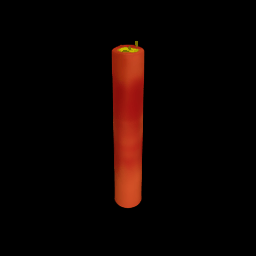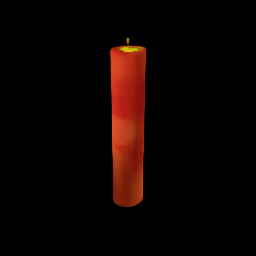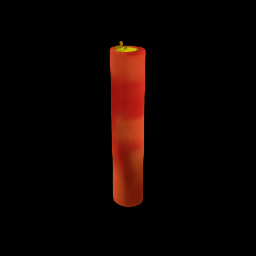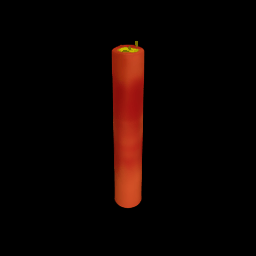
-
prompt = "A firecracker"
-
-
-
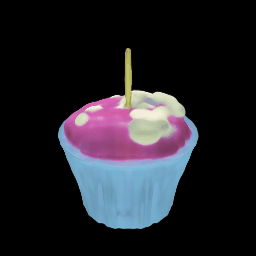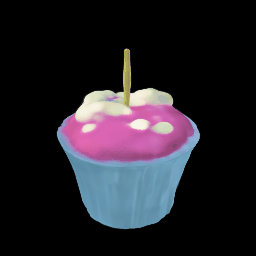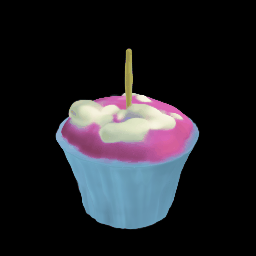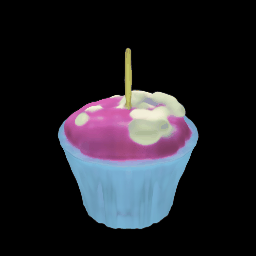
-
prompt = "A birthday cupcake"
-
-
-
-## Image-to-3D
-
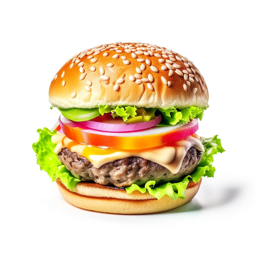
-To generate a 3D object from another image, use the [`ShapEImg2ImgPipeline`]. You can use an existing image or generate an entirely new one. Let's use the [Kandinsky 2.1](./kandinsky) model to generate a new image.
-
-```py
-from diffusers import DiffusionPipeline
-import torch
-
-prior_pipeline = DiffusionPipeline.from_pretrained("kandinsky-community/kandinsky-2-1-prior", dtype=torch.float16, use_safetensors=True).to("cuda") # or "mps", "xpu", "cpu"
-pipeline = DiffusionPipeline.from_pretrained("kandinsky-community/kandinsky-2-1", dtype=torch.float16, use_safetensors=True).to("cuda")
-
-prompt = "A cheeseburger, white background"
-
-image_embeds, negative_image_embeds = prior_pipeline(prompt, guidance_scale=1.0).to_tuple()
-image = pipeline(
- prompt,
- image_embeds=image_embeds,
- negative_image_embeds=negative_image_embeds,
-).images[0]
-
-image.save("burger.png")
-```
-
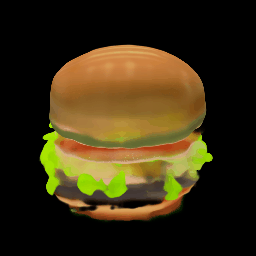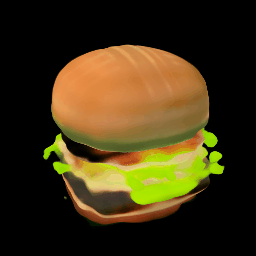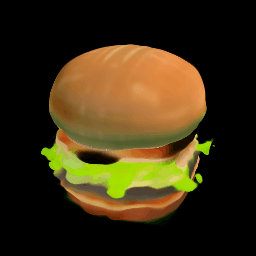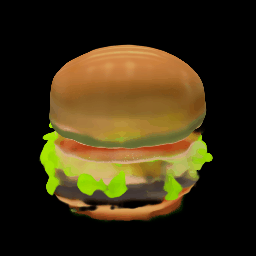
-Pass the cheeseburger to the [`ShapEImg2ImgPipeline`] to generate a 3D representation of it.
-
-```py
-from PIL import Image
-from diffusers import ShapEImg2ImgPipeline
-from diffusers.utils import export_to_gif
-
-pipe = ShapEImg2ImgPipeline.from_pretrained("openai/shap-e-img2img", dtype=torch.float16, variant="fp16").to("cuda") # or "mps", "xpu", "cpu"
-
-guidance_scale = 3.0
-image = Image.open("burger.png").resize((256, 256))
-
-images = pipe(
- image,
- guidance_scale=guidance_scale,
- num_inference_steps=64,
- frame_size=256,
-).images
-
-gif_path = export_to_gif(images[0], "burger_3d.gif")
-```
-
-
-
-

-
cheeseburger
-
-
-

-
3D cheeseburger
-
-
-
-## Generate mesh
-
-Shap-E is a flexible model that can also generate textured mesh outputs to be rendered for downstream applications. In this example, you'll convert the output into a `glb` file because the 🤗 Datasets library supports mesh visualization of `glb` files which can be rendered by the [Dataset viewer](https://huggingface.co/docs/hub/datasets-viewer#dataset-preview).
-
-You can generate mesh outputs for both the [`ShapEPipeline`] and [`ShapEImg2ImgPipeline`] by specifying the `output_type` parameter as `"mesh"`:
-
-```py
-import torch
-from diffusers import ShapEPipeline
-
-device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
-
-pipe = ShapEPipeline.from_pretrained("openai/shap-e", dtype=torch.float16, variant="fp16")
-pipe = pipe.to(device)
-
-guidance_scale = 15.0
-prompt = "A birthday cupcake"
-
-images = pipe(prompt, guidance_scale=guidance_scale, num_inference_steps=64, frame_size=256, output_type="mesh").images
-```
-
-Use the [`~utils.export_to_ply`] function to save the mesh output as a `ply` file:
-
-> [!TIP]
-> You can optionally save the mesh output as an `obj` file with the [`~utils.export_to_obj`] function. The ability to save the mesh output in a variety of formats makes it more flexible for downstream usage!
-
-```py
-from diffusers.utils import export_to_ply
-
-ply_path = export_to_ply(images[0], "3d_cake.ply")
-print(f"Saved to folder: {ply_path}")
-```
-
-Then you can convert the `ply` file to a `glb` file with the trimesh library:
-
-```py
-import trimesh
-
-mesh = trimesh.load("3d_cake.ply")
-mesh_export = mesh.export("3d_cake.glb", file_type="glb")
-```
-
-By default, the mesh output is focused from the bottom viewpoint but you can change the default viewpoint by applying a rotation transform:
-
-```py
-import trimesh
-import numpy as np
-
-mesh = trimesh.load("3d_cake.ply")
-rot = trimesh.transformations.rotation_matrix(-np.pi / 2, [1, 0, 0])
-mesh = mesh.apply_transform(rot)
-mesh_export = mesh.export("3d_cake.glb", file_type="glb")
-```
-
-Upload the mesh file to your dataset repository to visualize it with the Dataset viewer!
-
-
-

-
-
-## ShapEPipeline
-[[autodoc]] ShapEPipeline
- - all
- - __call__
-
-## ShapEImg2ImgPipeline
-[[autodoc]] ShapEImg2ImgPipeline
- - all
- - __call__
-
-## ShapEPipelineOutput
-[[autodoc]] pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput
diff --git a/examples/research_projects/promptdiffusion/convert_original_promptdiffusion_to_diffusers.py b/examples/research_projects/promptdiffusion/convert_original_promptdiffusion_to_diffusers.py
index 31105b6a5890..0f217a37a07c 100644
--- a/examples/research_projects/promptdiffusion/convert_original_promptdiffusion_to_diffusers.py
+++ b/examples/research_projects/promptdiffusion/convert_original_promptdiffusion_to_diffusers.py
@@ -36,6 +36,7 @@
CLIPVisionModelWithProjection,
)
+from diffusers import StableUnCLIPImageNormalizer
from diffusers.models import (
AutoencoderKL,
ControlNetModel,
@@ -46,7 +47,6 @@
from diffusers.pipelines.paint_by_example import PaintByExampleImageEncoder
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
from diffusers.pipelines.stable_diffusion.safety_checker import StableDiffusionSafetyChecker
-from diffusers.pipelines.stable_diffusion.stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
from diffusers.schedulers import (
DDIMScheduler,
DDPMScheduler,
diff --git a/scripts/convert_echo_to_diffusers.py b/scripts/convert_echo_to_diffusers.py
index 8d13fff8b21f..5f42051da26f 100644
--- a/scripts/convert_echo_to_diffusers.py
+++ b/scripts/convert_echo_to_diffusers.py
@@ -71,11 +71,11 @@ def write_modular_index(output_path: Path, base_model: str, repo_id: str | None)
"_blocks_class_name": "EchoBlocks",
"text_encoder": component_entry("transformers", "Gemma3ForConditionalGeneration", base_model, None),
"tokenizer": component_entry("transformers", "GemmaTokenizerFast", base_model, None),
- "connectors": component_entry("ltx2", "LTX2TextConnectors", echo_repo, "connectors"),
+ "connectors": component_entry("diffusers", "LTX2TextConnectors", echo_repo, "connectors"),
"vae": component_entry("diffusers", "AutoencoderKLLTX2Video", echo_repo, "vae"),
"audio_vae": component_entry("diffusers", "AutoencoderKLLTX2Audio", echo_repo, "audio_vae"),
"transformer": component_entry("diffusers", "LTX2VideoTransformer3DModel", echo_repo, "transformer"),
- "vocoder": component_entry("ltx2", "LTX2VocoderWithBWE", echo_repo, "vocoder"),
+ "vocoder": component_entry("diffusers", "LTX2VocoderWithBWE", echo_repo, "vocoder"),
}
(output_path / "modular_model_index.json").write_text(json.dumps(index, indent=2) + "\n", encoding="utf-8")
diff --git a/scripts/convert_shap_e_to_diffusers.py b/scripts/convert_shap_e_to_diffusers.py
index ac6543667af9..0622e1282668 100644
--- a/scripts/convert_shap_e_to_diffusers.py
+++ b/scripts/convert_shap_e_to_diffusers.py
@@ -5,7 +5,7 @@
from accelerate import load_checkpoint_and_dispatch
from diffusers.models.transformers.prior_transformer import PriorTransformer
-from diffusers.pipelines.shap_e import ShapERenderer
+from diffusers.pipelines.deprecated.shap_e import ShapERenderer
"""
diff --git a/src/diffusers/__init__.py b/src/diffusers/__init__.py
index 048f37f4061f..1435abc234cf 100644
--- a/src/diffusers/__init__.py
+++ b/src/diffusers/__init__.py
@@ -227,6 +227,8 @@
]
_import_structure["models"].extend(
[
+ "AceStepAudioTokenDetokenizer",
+ "AceStepAudioTokenizer",
"AceStepConditionEncoder",
"AceStepTransformer1DModel",
"AllegroTransformer3DModel",
@@ -236,6 +238,7 @@
"AsymmetricAutoencoderKL",
"AttentionBackendName",
"AudioLDM2ProjectionModel",
+ "AudioLDM2UNet2DConditionModel",
"AuraFlowTransformer2DModel",
"AutoencoderDC",
"AutoencoderKL",
@@ -329,6 +332,8 @@
"LTX2TextConnectors",
"LTX2VideoDiffusionDecoderModel",
"LTX2VideoTransformer3DModel",
+ "LTX2Vocoder",
+ "LTX2VocoderWithBWE",
"LTXLatentUpsamplerModel",
"LTXVideoTransformer3DModel",
"Lumina2Transformer2DModel",
@@ -378,6 +383,7 @@
"StableAudioDiTModel",
"StableAudioProjectionModel",
"StableCascadeUNet",
+ "StableUnCLIPImageNormalizer",
"T2IAdapter",
"T5FilmDecoder",
"TensorParallelConfig",
@@ -643,8 +649,6 @@
)
_import_structure["pipelines"].extend(
[
- "AceStepAudioTokenDetokenizer",
- "AceStepAudioTokenizer",
"AceStepPipeline",
"AllegroPipeline",
"AltDiffusionImg2ImgPipeline",
@@ -662,7 +666,6 @@
"AnyFlowFARPipeline",
"AnyFlowPipeline",
"AudioLDM2Pipeline",
- "AudioLDM2UNet2DConditionModel",
"AudioLDMPipeline",
"AuraFlowPipeline",
"BlipDiffusionControlNetPipeline",
@@ -1142,6 +1145,8 @@
VaeImageProcessorLDM3D,
)
from .models import (
+ AceStepAudioTokenDetokenizer,
+ AceStepAudioTokenizer,
AceStepConditionEncoder,
AceStepTransformer1DModel,
AllegroTransformer3DModel,
@@ -1151,6 +1156,7 @@
AsymmetricAutoencoderKL,
AttentionBackendName,
AudioLDM2ProjectionModel,
+ AudioLDM2UNet2DConditionModel,
AuraFlowTransformer2DModel,
AutoencoderDC,
AutoencoderKL,
@@ -1244,6 +1250,8 @@
LTX2TextConnectors,
LTX2VideoDiffusionDecoderModel,
LTX2VideoTransformer3DModel,
+ LTX2Vocoder,
+ LTX2VocoderWithBWE,
LTXLatentUpsamplerModel,
LTXVideoTransformer3DModel,
Lumina2Transformer2DModel,
@@ -1292,6 +1300,7 @@
StableAudio3DurationEmbedder,
StableAudioDiTModel,
StableAudioProjectionModel,
+ StableUnCLIPImageNormalizer,
T2IAdapter,
T5FilmDecoder,
TensorParallelConfig,
@@ -1534,8 +1543,6 @@
ZImageModularPipeline,
)
from .pipelines import (
- AceStepAudioTokenDetokenizer,
- AceStepAudioTokenizer,
AceStepPipeline,
AllegroPipeline,
AltDiffusionImg2ImgPipeline,
@@ -1553,7 +1560,6 @@
AnyFlowFARPipeline,
AnyFlowPipeline,
AudioLDM2Pipeline,
- AudioLDM2UNet2DConditionModel,
AudioLDMPipeline,
AuraFlowPipeline,
BriaFibo2Pipeline,
diff --git a/src/diffusers/models/__init__.py b/src/diffusers/models/__init__.py
index 28075d72de80..409933b0304d 100755
--- a/src/diffusers/models/__init__.py
+++ b/src/diffusers/models/__init__.py
@@ -28,6 +28,10 @@
_import_structure["adapter"] = ["MultiAdapter", "T2IAdapter"]
_import_structure["attention_dispatch"] = ["AttentionBackendName", "attention_backend"]
_import_structure["auto_model"] = ["AutoModel"]
+ _import_structure["autoencoders.audio_tokenizer_ace_step"] = [
+ "AceStepAudioTokenDetokenizer",
+ "AceStepAudioTokenizer",
+ ]
_import_structure["autoencoders.autoencoder_asym_kl"] = ["AsymmetricAutoencoderKL"]
_import_structure["autoencoders.autoencoder_cosmos3_audio"] = ["Cosmos3AVAEAudioTokenizer"]
_import_structure["autoencoders.autoencoder_dc"] = ["AutoencoderDC"]
@@ -69,6 +73,7 @@
_import_structure["autoencoders.ltx2_diffusion_decoder"] = ["LTX2VideoDiffusionDecoderModel"]
_import_structure["autoencoders.minimax_music3_vocoder"] = ["MiniMaxMusic3Vocoder"]
_import_structure["autoencoders.mmaudio_vocoder"] = ["MMAudioVocoder"]
+ _import_structure["autoencoders.vocoder_ltx2"] = ["LTX2Vocoder", "LTX2VocoderWithBWE"]
_import_structure["autoencoders.vq_model"] = ["VQModel"]
_import_structure["cache_utils"] = ["CacheMixin"]
_import_structure["condition_embedders.condition_embedder_ace_step"] = ["AceStepConditionEncoder"]
@@ -81,6 +86,7 @@
_import_structure["condition_embedders.condition_embedder_p_h3_image"] = ["PH3ImageTextConnector"]
_import_structure["condition_embedders.condition_embedder_stable_audio"] = ["StableAudioProjectionModel"]
_import_structure["condition_embedders.condition_embedder_stable_audio_3"] = ["StableAudio3DurationEmbedder"]
+ _import_structure["condition_embedders.condition_embedder_stable_unclip"] = ["StableUnCLIPImageNormalizer"]
_import_structure["controlnets.controlnet"] = ["ControlNetModel"]
_import_structure["controlnets.controlnet_cosmos"] = ["CosmosControlNetModel"]
_import_structure["controlnets.controlnet_flux"] = ["FluxControlNetModel", "FluxMultiControlNetModel"]
@@ -187,6 +193,7 @@
_import_structure["unets.unet_1d"] = ["UNet1DModel"]
_import_structure["unets.unet_2d"] = ["UNet2DModel"]
_import_structure["unets.unet_2d_condition"] = ["UNet2DConditionModel"]
+ _import_structure["unets.unet_2d_condition_audioldm2"] = ["AudioLDM2UNet2DConditionModel"]
_import_structure["unets.unet_3d_condition"] = ["UNet3DConditionModel"]
_import_structure["unets.unet_dreamlite"] = ["DreamLiteUNetModel"]
_import_structure["unets.unet_i2vgen_xl"] = ["I2VGenXLUNet"]
@@ -204,6 +211,8 @@
from .attention_dispatch import AttentionBackendName, attention_backend
from .auto_model import AutoModel
from .autoencoders import (
+ AceStepAudioTokenDetokenizer,
+ AceStepAudioTokenizer,
AsymmetricAutoencoderKL,
AutoencoderDC,
AutoencoderKL,
@@ -241,6 +250,8 @@
Kandinsky6SRVAE,
LongCatAudioDiTVae,
LTX2VideoDiffusionDecoderModel,
+ LTX2Vocoder,
+ LTX2VocoderWithBWE,
MiniMaxMusic3Vocoder,
MMAudioVAE,
MMAudioVocoder,
@@ -259,6 +270,7 @@
ReduxImageEncoder,
StableAudio3DurationEmbedder,
StableAudioProjectionModel,
+ StableUnCLIPImageNormalizer,
)
from .controlnets import (
ControlNetModel,
@@ -365,6 +377,7 @@
ZImageTransformer2DModel,
)
from .unets import (
+ AudioLDM2UNet2DConditionModel,
DreamLiteUNetModel,
I2VGenXLUNet,
Kandinsky3UNet,
diff --git a/src/diffusers/models/autoencoders/__init__.py b/src/diffusers/models/autoencoders/__init__.py
index 84e2fdf1c0b9..08e808d06363 100644
--- a/src/diffusers/models/autoencoders/__init__.py
+++ b/src/diffusers/models/autoencoders/__init__.py
@@ -1,3 +1,4 @@
+from .audio_tokenizer_ace_step import AceStepAudioTokenDetokenizer, AceStepAudioTokenizer
from .autoencoder_asym_kl import AsymmetricAutoencoderKL
from .autoencoder_cosmos3_audio import Cosmos3AVAEAudioTokenizer
from .autoencoder_dc import AutoencoderDC
@@ -39,4 +40,5 @@
from .ltx2_diffusion_decoder import LTX2VideoDiffusionDecoderModel
from .minimax_music3_vocoder import MiniMaxMusic3Vocoder
from .mmaudio_vocoder import MMAudioVocoder
+from .vocoder_ltx2 import LTX2Vocoder, LTX2VocoderWithBWE
from .vq_model import VQModel
diff --git a/src/diffusers/models/autoencoders/audio_tokenizer_ace_step.py b/src/diffusers/models/autoencoders/audio_tokenizer_ace_step.py
new file mode 100644
index 000000000000..d68a70680cb1
--- /dev/null
+++ b/src/diffusers/models/autoencoders/audio_tokenizer_ace_step.py
@@ -0,0 +1,431 @@
+# Copyright 2025 The ACE-Step Team and The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Audio tokenizer / detokenizer for ACE-Step 1.5, used by cover conditioning."""
+
+from typing import Optional, Tuple
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...configuration_utils import ConfigMixin, register_to_config
+from ...utils import logging
+from ..condition_embedders.condition_embedder_ace_step import AceStepEncoderLayer
+from ..modeling_utils import ModelMixin
+from ..normalization import RMSNorm
+from ..transformers.ace_step_transformer import (
+ _ace_step_rotary_freqs,
+ _create_4d_mask,
+ _is_flash_attention_backend,
+)
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+# --------------------------------------------------------------------------- #
+# audio tokenizer / detokenizer #
+# --------------------------------------------------------------------------- #
+
+
+class _AceStepResidualFSQ(nn.Module):
+ """Minimal ResidualFSQ compatible with ACE-Step's saved tokenizer weights."""
+
+ def __init__(
+ self,
+ dim: int = 2048,
+ levels: Optional[list] = None,
+ num_quantizers: int = 1,
+ ):
+ super().__init__()
+
+ if levels is None:
+ levels = [8, 8, 8, 5, 5, 5]
+
+ self.levels = levels
+ self.num_quantizers = num_quantizers
+ self.codebook_dim = len(levels)
+
+ self.project_in = nn.Linear(dim, self.codebook_dim)
+ self.project_out = nn.Linear(self.codebook_dim, dim)
+
+ levels_tensor = torch.tensor(levels, dtype=torch.long)
+ basis = torch.cumprod(torch.tensor([1] + levels[:-1], dtype=torch.long), dim=0)
+ scales = torch.stack([levels_tensor.float() ** -i for i in range(num_quantizers)])
+ self.register_buffer("_levels", levels_tensor, persistent=False)
+ self.register_buffer("_basis", basis, persistent=False)
+ self.register_buffer("scales", scales, persistent=False)
+
+ @property
+ def codebook_size(self) -> int:
+ return int(torch.prod(self._levels).item())
+
+ def _indices_to_codes(self, indices: torch.Tensor) -> torch.Tensor:
+ levels = self._levels.to(device=indices.device)
+ basis = self._basis.to(device=indices.device)
+ level_indices = (indices.long().unsqueeze(-1) // basis) % levels
+ scale = 2.0 / (levels.to(dtype=torch.float32) - 1.0)
+ return level_indices.to(dtype=torch.float32) * scale - 1.0
+
+ def _codes_to_indices(self, codes: torch.Tensor) -> torch.Tensor:
+ levels = self._levels.to(device=codes.device, dtype=codes.dtype)
+ basis = self._basis.to(device=codes.device, dtype=codes.dtype)
+ level_indices = (codes + 1.0) / (2.0 / (levels - 1.0))
+ return (level_indices * basis).sum(dim=-1).round().to(torch.long)
+
+ def _quantize(self, x: torch.Tensor) -> torch.Tensor:
+ levels = self._levels.to(device=x.device, dtype=x.dtype)
+ levels_minus_one = levels - 1.0
+ step = 2.0 / levels_minus_one
+ bracket = levels_minus_one * (x.clamp(-1.0, 1.0) + 1.0) / 2.0 + 0.5
+ return step * torch.floor(bracket) - 1.0
+
+ def get_codes_from_indices(self, indices: torch.Tensor) -> torch.Tensor:
+ if indices.ndim == 2:
+ indices = indices.unsqueeze(-1)
+ if indices.shape[-1] != self.num_quantizers:
+ raise ValueError(
+ f"Expected audio code indices with last dimension {self.num_quantizers}, got {indices.shape[-1]}."
+ )
+
+ codes = []
+ for quantizer_idx in range(self.num_quantizers):
+ code = self._indices_to_codes(indices[..., quantizer_idx])
+ scale = self.scales[quantizer_idx].to(device=code.device, dtype=code.dtype)
+ codes.append(code * scale)
+ return torch.stack(codes, dim=0)
+
+ def get_output_from_indices(self, indices: torch.Tensor) -> torch.Tensor:
+ codes = self.get_codes_from_indices(indices).sum(dim=0)
+ weight = self.project_out.weight.float()
+ bias = self.project_out.bias.float() if self.project_out.bias is not None else None
+ output = F.linear(codes.float(), weight, bias)
+ return output.to(dtype=self.project_out.weight.dtype)
+
+ def forward(self, hidden_states: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor]:
+ input_dtype = hidden_states.dtype
+ weight = self.project_in.weight.float()
+ bias = self.project_in.bias.float() if self.project_in.bias is not None else None
+ hidden_states = F.linear(hidden_states.float(), weight, bias)
+
+ levels = self._levels.to(device=hidden_states.device, dtype=hidden_states.dtype)
+ soft_clamp = 1.0 + (1.0 / (levels - 1.0))
+ hidden_states = (hidden_states / soft_clamp).tanh() * soft_clamp
+
+ quantized_out = torch.zeros_like(hidden_states)
+ residual = hidden_states
+ all_indices = []
+ for scale in self.scales.to(device=hidden_states.device, dtype=hidden_states.dtype):
+ quantized = self._quantize(residual / scale) * scale
+ residual = residual - quantized.detach()
+ quantized_out = quantized_out + quantized
+ all_indices.append(self._codes_to_indices(quantized / scale))
+
+ weight = self.project_out.weight.float()
+ bias = self.project_out.bias.float() if self.project_out.bias is not None else None
+ quantized_out = F.linear(quantized_out.float(), weight, bias).to(dtype=input_dtype)
+ all_indices = torch.stack(all_indices, dim=-1)
+ return quantized_out, all_indices
+
+
+class AceStepAttentionPooler(nn.Module):
+ """Attention pooler used by the ACE-Step audio tokenizer."""
+
+ def __init__(
+ self,
+ hidden_size: int = 2048,
+ intermediate_size: int = 6144,
+ num_attention_pooler_hidden_layers: int = 2,
+ num_attention_heads: int = 16,
+ num_key_value_heads: int = 8,
+ head_dim: int = 128,
+ rope_theta: float = 1000000.0,
+ attention_bias: bool = False,
+ attention_dropout: float = 0.0,
+ rms_norm_eps: float = 1e-6,
+ sliding_window: int = 128,
+ layer_types: list = None,
+ ):
+ super().__init__()
+
+ if layer_types is None:
+ layer_types = [
+ "sliding_attention" if bool((i + 1) % 2) else "full_attention"
+ for i in range(num_attention_pooler_hidden_layers)
+ ]
+
+ self.embed_tokens = nn.Linear(hidden_size, hidden_size)
+ self.norm = RMSNorm(hidden_size, eps=rms_norm_eps)
+ self.special_token = nn.Parameter(torch.randn(1, 1, hidden_size) * 0.02)
+ self.head_dim = head_dim
+ self.rope_theta = rope_theta
+ self.sliding_window = sliding_window
+ self.layers = nn.ModuleList(
+ [
+ AceStepEncoderLayer(
+ hidden_size=hidden_size,
+ num_attention_heads=num_attention_heads,
+ num_key_value_heads=num_key_value_heads,
+ head_dim=head_dim,
+ intermediate_size=intermediate_size,
+ attention_bias=attention_bias,
+ attention_dropout=attention_dropout,
+ rms_norm_eps=rms_norm_eps,
+ sliding_window=sliding_window if layer_types[i] == "sliding_attention" else None,
+ )
+ for i in range(num_attention_pooler_hidden_layers)
+ ]
+ )
+ self._layer_types = layer_types
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ batch_size, num_patches, patch_size, _ = hidden_states.shape
+ hidden_states = self.embed_tokens(hidden_states)
+ special_token = self.special_token.to(device=hidden_states.device, dtype=hidden_states.dtype)
+ special_token = special_token.expand(batch_size, num_patches, -1, -1)
+ hidden_states = torch.cat([special_token, hidden_states], dim=2)
+ hidden_states = hidden_states.reshape(batch_size * num_patches, patch_size + 1, -1)
+
+ seq_len = hidden_states.shape[1]
+ dtype = hidden_states.dtype
+ device = hidden_states.device
+ position_embeddings = _ace_step_rotary_freqs(seq_len, self.head_dim, self.rope_theta, device, dtype)
+ sliding_attn_mask = None
+ if not _is_flash_attention_backend(self.layers[0].self_attn.processor):
+ sliding_attn_mask = _create_4d_mask(
+ seq_len=seq_len,
+ dtype=dtype,
+ device=device,
+ attention_mask=None,
+ sliding_window=self.sliding_window,
+ is_sliding_window=True,
+ is_causal=False,
+ )
+
+ for i, layer_module in enumerate(self.layers):
+ mask = sliding_attn_mask if self._layer_types[i] == "sliding_attention" else None
+ hidden_states = layer_module(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=mask,
+ )
+
+ hidden_states = self.norm(hidden_states)
+ hidden_states = hidden_states[:, 0, :]
+ return hidden_states.reshape(batch_size, num_patches, -1)
+
+
+class AceStepAudioTokenDetokenizer(ModelMixin, ConfigMixin):
+ """Expands ACE-Step 5 Hz audio tokens back to 25 Hz acoustic conditioning."""
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ hidden_size: int = 2048,
+ intermediate_size: int = 6144,
+ audio_acoustic_hidden_dim: int = 64,
+ pool_window_size: int = 5,
+ num_attention_pooler_hidden_layers: int = 2,
+ num_attention_heads: int = 16,
+ num_key_value_heads: int = 8,
+ head_dim: int = 128,
+ rope_theta: float = 1000000.0,
+ attention_bias: bool = False,
+ attention_dropout: float = 0.0,
+ rms_norm_eps: float = 1e-6,
+ sliding_window: int = 128,
+ layer_types: list = None,
+ ):
+ super().__init__()
+
+ if layer_types is None:
+ layer_types = [
+ "sliding_attention" if bool((i + 1) % 2) else "full_attention"
+ for i in range(num_attention_pooler_hidden_layers)
+ ]
+
+ self.embed_tokens = nn.Linear(hidden_size, hidden_size)
+ self.norm = RMSNorm(hidden_size, eps=rms_norm_eps)
+ self.special_tokens = nn.Parameter(torch.randn(1, pool_window_size, hidden_size) * 0.02)
+ self.proj_out = nn.Linear(hidden_size, audio_acoustic_hidden_dim)
+ self.head_dim = head_dim
+ self.rope_theta = rope_theta
+ self.sliding_window = sliding_window
+ self.pool_window_size = pool_window_size
+ self.layers = nn.ModuleList(
+ [
+ AceStepEncoderLayer(
+ hidden_size=hidden_size,
+ num_attention_heads=num_attention_heads,
+ num_key_value_heads=num_key_value_heads,
+ head_dim=head_dim,
+ intermediate_size=intermediate_size,
+ attention_bias=attention_bias,
+ attention_dropout=attention_dropout,
+ rms_norm_eps=rms_norm_eps,
+ sliding_window=sliding_window if layer_types[i] == "sliding_attention" else None,
+ )
+ for i in range(num_attention_pooler_hidden_layers)
+ ]
+ )
+ self._layer_types = layer_types
+ self.gradient_checkpointing = False
+
+ def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
+ r"""
+ Args:
+ hidden_states (`torch.Tensor`):
+ Quantized 5 Hz audio token embeddings from [`AceStepAudioTokenizer`], of shape `(batch_size,
+ num_tokens, hidden_size)`.
+
+ Returns:
+ `torch.Tensor`:
+ 25 Hz acoustic conditioning of shape `(batch_size, num_tokens * pool_window_size,
+ audio_acoustic_hidden_dim)`.
+ """
+ batch_size, num_tokens, _ = hidden_states.shape
+ hidden_states = self.embed_tokens(hidden_states)
+ hidden_states = hidden_states.unsqueeze(2).expand(-1, -1, self.pool_window_size, -1)
+ special_tokens = self.special_tokens.to(device=hidden_states.device, dtype=hidden_states.dtype)
+ hidden_states = hidden_states + special_tokens.unsqueeze(0)
+ hidden_states = hidden_states.reshape(batch_size * num_tokens, self.pool_window_size, -1)
+
+ seq_len = hidden_states.shape[1]
+ dtype = hidden_states.dtype
+ device = hidden_states.device
+ position_embeddings = _ace_step_rotary_freqs(seq_len, self.head_dim, self.rope_theta, device, dtype)
+ sliding_attn_mask = None
+ if not _is_flash_attention_backend(self.layers[0].self_attn.processor):
+ sliding_attn_mask = _create_4d_mask(
+ seq_len=seq_len,
+ dtype=dtype,
+ device=device,
+ attention_mask=None,
+ sliding_window=self.sliding_window,
+ is_sliding_window=True,
+ is_causal=False,
+ )
+
+ for i, layer_module in enumerate(self.layers):
+ mask = sliding_attn_mask if self._layer_types[i] == "sliding_attention" else None
+ if torch.is_grad_enabled() and self.gradient_checkpointing:
+ hidden_states = self._gradient_checkpointing_func(
+ layer_module, hidden_states, position_embeddings, mask
+ )
+ else:
+ hidden_states = layer_module(
+ hidden_states=hidden_states,
+ position_embeddings=position_embeddings,
+ attention_mask=mask,
+ )
+
+ hidden_states = self.norm(hidden_states)
+ hidden_states = self.proj_out(hidden_states)
+ return hidden_states.reshape(batch_size, num_tokens * self.pool_window_size, -1)
+
+
+class AceStepAudioTokenizer(ModelMixin, ConfigMixin):
+ """Converts 25 Hz acoustic latents to ACE-Step 5 Hz audio tokens."""
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ hidden_size: int = 2048,
+ intermediate_size: int = 6144,
+ audio_acoustic_hidden_dim: int = 64,
+ pool_window_size: int = 5,
+ fsq_dim: int = 2048,
+ fsq_input_levels: list = None,
+ fsq_input_num_quantizers: int = 1,
+ num_attention_pooler_hidden_layers: int = 2,
+ num_attention_heads: int = 16,
+ num_key_value_heads: int = 8,
+ head_dim: int = 128,
+ rope_theta: float = 1000000.0,
+ attention_bias: bool = False,
+ attention_dropout: float = 0.0,
+ rms_norm_eps: float = 1e-6,
+ sliding_window: int = 128,
+ layer_types: list = None,
+ ):
+ super().__init__()
+
+ if fsq_input_levels is None:
+ fsq_input_levels = [8, 8, 8, 5, 5, 5]
+
+ self.audio_acoustic_proj = nn.Linear(audio_acoustic_hidden_dim, hidden_size)
+ self.attention_pooler = AceStepAttentionPooler(
+ hidden_size=hidden_size,
+ intermediate_size=intermediate_size,
+ num_attention_pooler_hidden_layers=num_attention_pooler_hidden_layers,
+ num_attention_heads=num_attention_heads,
+ num_key_value_heads=num_key_value_heads,
+ head_dim=head_dim,
+ rope_theta=rope_theta,
+ attention_bias=attention_bias,
+ attention_dropout=attention_dropout,
+ rms_norm_eps=rms_norm_eps,
+ sliding_window=sliding_window,
+ layer_types=layer_types,
+ )
+ self.quantizer = _AceStepResidualFSQ(
+ dim=fsq_dim,
+ levels=fsq_input_levels,
+ num_quantizers=fsq_input_num_quantizers,
+ )
+ self.pool_window_size = pool_window_size
+
+ def forward(self, hidden_states: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor]:
+ r"""
+ Args:
+ hidden_states (`torch.Tensor`):
+ Windowed 25 Hz acoustic latents of shape `(batch_size, num_tokens, pool_window_size,
+ audio_acoustic_hidden_dim)`. Use [`~AceStepAudioTokenizer.tokenize`] to pad and window raw latents.
+
+ Returns:
+ `Tuple[torch.Tensor, torch.Tensor]`:
+ The quantized 5 Hz token embeddings of shape `(batch_size, num_tokens, hidden_size)` and their codebook
+ indices of shape `(batch_size, num_tokens, num_quantizers)`.
+ """
+ input_dtype = hidden_states.dtype
+ hidden_states = self.audio_acoustic_proj(hidden_states)
+ hidden_states = self.attention_pooler(hidden_states)
+ quantized, indices = self.quantizer(hidden_states)
+ return quantized.to(dtype=input_dtype), indices
+
+ def tokenize(
+ self,
+ hidden_states: torch.Tensor,
+ silence_latent: Optional[torch.Tensor] = None,
+ ) -> Tuple[torch.Tensor, torch.Tensor]:
+ batch_size, latent_length, acoustic_dim = hidden_states.shape
+ pad_len = (-latent_length) % self.pool_window_size
+ if pad_len:
+ if silence_latent is not None and silence_latent.shape[-1] == acoustic_dim:
+ pad = silence_latent[:, :pad_len, :].to(device=hidden_states.device, dtype=hidden_states.dtype)
+ pad = pad.expand(batch_size, -1, -1)
+ else:
+ pad = torch.zeros(
+ batch_size, pad_len, acoustic_dim, device=hidden_states.device, dtype=hidden_states.dtype
+ )
+ hidden_states = torch.cat([hidden_states, pad], dim=1)
+
+ num_patches = hidden_states.shape[1] // self.pool_window_size
+ hidden_states = hidden_states.reshape(batch_size, num_patches, self.pool_window_size, acoustic_dim)
+ return self(hidden_states)
diff --git a/src/diffusers/models/autoencoders/vocoder_ltx2.py b/src/diffusers/models/autoencoders/vocoder_ltx2.py
new file mode 100644
index 000000000000..83a49a8d2184
--- /dev/null
+++ b/src/diffusers/models/autoencoders/vocoder_ltx2.py
@@ -0,0 +1,621 @@
+# Copyright 2026 Lightricks and The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import math
+
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ...configuration_utils import ConfigMixin, register_to_config
+from ..modeling_utils import ModelMixin
+
+
+def kaiser_sinc_filter1d(cutoff: float, half_width: float, kernel_size: int) -> torch.Tensor:
+ """
+ Creates a Kaiser sinc kernel for low-pass filtering.
+
+ Args:
+ cutoff (`float`):
+ Normalized frequency cutoff (relative to the sampling rate). Must be between 0 and 0.5 (the Nyquist
+ frequency).
+ half_width (`float`):
+ Used to determine the Kaiser window's beta parameter.
+ kernel_size:
+ Size of the Kaiser window (and ultimately the Kaiser sinc kernel).
+
+ Returns:
+ `torch.Tensor` of shape `(kernel_size,)`:
+ The Kaiser sinc kernel.
+ """
+ delta_f = 4 * half_width
+ half_size = kernel_size // 2
+ amplitude = 2.285 * (half_size - 1) * math.pi * delta_f + 7.95
+ if amplitude > 50.0:
+ beta = 0.1102 * (amplitude - 8.7)
+ elif amplitude >= 21.0:
+ beta = 0.5842 * (amplitude - 21) ** 0.4 + 0.07886 * (amplitude - 21.0)
+ else:
+ beta = 0.0
+
+ window = torch.kaiser_window(kernel_size, beta=beta, periodic=False)
+
+ even = kernel_size % 2 == 0
+ time = torch.arange(-half_size, half_size) + 0.5 if even else torch.arange(kernel_size) - half_size
+
+ if cutoff == 0.0:
+ filter = torch.zeros_like(time)
+ else:
+ time = 2 * cutoff * time
+ sinc = torch.where(
+ time == 0,
+ torch.ones_like(time),
+ torch.sin(math.pi * time) / math.pi / time,
+ )
+ filter = 2 * cutoff * window * sinc
+ filter = filter / filter.sum()
+ return filter
+
+
+class DownSample1d(nn.Module):
+ """1D low-pass filter for antialias downsampling."""
+
+ def __init__(
+ self,
+ ratio: int = 2,
+ kernel_size: int | None = None,
+ use_padding: bool = True,
+ padding_mode: str = "replicate",
+ persistent: bool = True,
+ ):
+ super().__init__()
+ self.ratio = ratio
+ self.kernel_size = kernel_size or int(6 * ratio // 2) * 2
+ self.pad_left = self.kernel_size // 2 + (self.kernel_size % 2) - 1
+ self.pad_right = self.kernel_size // 2
+ self.use_padding = use_padding
+ self.padding_mode = padding_mode
+
+ cutoff = 0.5 / ratio
+ half_width = 0.6 / ratio
+ low_pass_filter = kaiser_sinc_filter1d(cutoff, half_width, self.kernel_size)
+ self.register_buffer("filter", low_pass_filter.view(1, 1, self.kernel_size), persistent=persistent)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ # x expected shape: [batch_size, num_channels, hidden_dim]
+ num_channels = x.shape[1]
+ if self.use_padding:
+ x = F.pad(x, (self.pad_left, self.pad_right), mode=self.padding_mode)
+ x_filtered = F.conv1d(x, self.filter.expand(num_channels, -1, -1), stride=self.ratio, groups=num_channels)
+ return x_filtered
+
+
+class UpSample1d(nn.Module):
+ def __init__(
+ self,
+ ratio: int = 2,
+ kernel_size: int | None = None,
+ window_type: str = "kaiser",
+ padding_mode: str = "replicate",
+ persistent: bool = True,
+ ):
+ super().__init__()
+ self.ratio = ratio
+ self.padding_mode = padding_mode
+
+ if window_type == "hann":
+ rolloff = 0.99
+ lowpass_filter_width = 6
+ width = math.ceil(lowpass_filter_width / rolloff)
+ self.kernel_size = 2 * width * ratio + 1
+ self.pad = width
+ self.pad_left = 2 * width * ratio
+ self.pad_right = self.kernel_size - ratio
+
+ time_axis = (torch.arange(self.kernel_size) / ratio - width) * rolloff
+ time_clamped = time_axis.clamp(-lowpass_filter_width, lowpass_filter_width)
+ window = torch.cos(time_clamped * math.pi / lowpass_filter_width / 2) ** 2
+ sinc_filter = (torch.sinc(time_axis) * window * rolloff / ratio).view(1, 1, -1)
+ else:
+ # Kaiser sinc filter is BigVGAN default
+ self.kernel_size = int(6 * ratio // 2) * 2 if kernel_size is None else kernel_size
+ self.pad = self.kernel_size // ratio - 1
+ self.pad_left = self.pad * self.ratio + (self.kernel_size - self.ratio) // 2
+ self.pad_right = self.pad * self.ratio + (self.kernel_size - self.ratio + 1) // 2
+
+ sinc_filter = kaiser_sinc_filter1d(
+ cutoff=0.5 / ratio,
+ half_width=0.6 / ratio,
+ kernel_size=self.kernel_size,
+ )
+
+ self.register_buffer("filter", sinc_filter.view(1, 1, self.kernel_size), persistent=persistent)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ # x expected shape: [batch_size, num_channels, hidden_dim]
+ num_channels = x.shape[1]
+ x = F.pad(x, (self.pad, self.pad), mode=self.padding_mode)
+ low_pass_filter = self.filter.to(dtype=x.dtype, device=x.device).expand(num_channels, -1, -1)
+ x = self.ratio * F.conv_transpose1d(x, low_pass_filter, stride=self.ratio, groups=num_channels)
+ return x[..., self.pad_left : -self.pad_right]
+
+
+class AntiAliasAct1d(nn.Module):
+ """
+ Antialiasing activation for a 1D signal: upsamples, applies an activation (usually snakebeta), and then downsamples
+ to avoid aliasing.
+ """
+
+ def __init__(
+ self,
+ act_fn: str | nn.Module,
+ ratio: int = 2,
+ kernel_size: int = 12,
+ **kwargs,
+ ):
+ super().__init__()
+ self.upsample = UpSample1d(ratio=ratio, kernel_size=kernel_size)
+ if isinstance(act_fn, str):
+ if act_fn == "snakebeta":
+ act_fn = SnakeBeta(**kwargs)
+ elif act_fn == "snake":
+ act_fn = SnakeBeta(**kwargs)
+ else:
+ act_fn = nn.LeakyReLU(**kwargs)
+ self.act = act_fn
+ self.downsample = DownSample1d(ratio=ratio, kernel_size=kernel_size)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ x = self.upsample(x)
+ x = self.act(x)
+ x = self.downsample(x)
+ return x
+
+
+class SnakeBeta(nn.Module):
+ """
+ Implements the Snake and SnakeBeta activations, which help with learning periodic patterns.
+ """
+
+ def __init__(
+ self,
+ channels: int,
+ alpha: float = 1.0,
+ eps: float = 1e-9,
+ trainable_params: bool = True,
+ logscale: bool = True,
+ use_beta: bool = True,
+ ):
+ super().__init__()
+ self.eps = eps
+ self.logscale = logscale
+ self.use_beta = use_beta
+
+ self.alpha = nn.Parameter(torch.zeros(channels) if self.logscale else torch.ones(channels) * alpha)
+ self.alpha.requires_grad = trainable_params
+ if use_beta:
+ self.beta = nn.Parameter(torch.zeros(channels) if self.logscale else torch.ones(channels) * alpha)
+ self.beta.requires_grad = trainable_params
+
+ def forward(self, hidden_states: torch.Tensor, channel_dim: int = 1) -> torch.Tensor:
+ broadcast_shape = [1] * hidden_states.ndim
+ broadcast_shape[channel_dim] = -1
+ alpha = self.alpha.view(broadcast_shape)
+ if self.use_beta:
+ beta = self.beta.view(broadcast_shape)
+
+ if self.logscale:
+ alpha = torch.exp(alpha)
+ if self.use_beta:
+ beta = torch.exp(beta)
+
+ amplitude = beta if self.use_beta else alpha
+ hidden_states = hidden_states + (1.0 / (amplitude + self.eps)) * torch.sin(hidden_states * alpha).pow(2)
+ return hidden_states
+
+
+class ResBlock(nn.Module):
+ def __init__(
+ self,
+ channels: int,
+ kernel_size: int = 3,
+ stride: int = 1,
+ dilations: tuple[int, ...] = (1, 3, 5),
+ act_fn: str = "leaky_relu",
+ leaky_relu_negative_slope: float = 0.1,
+ antialias: bool = False,
+ antialias_ratio: int = 2,
+ antialias_kernel_size: int = 12,
+ padding_mode: str = "same",
+ ):
+ super().__init__()
+ self.dilations = dilations
+
+ self.convs1 = nn.ModuleList(
+ [
+ nn.Conv1d(channels, channels, kernel_size, stride=stride, dilation=dilation, padding=padding_mode)
+ for dilation in dilations
+ ]
+ )
+ self.acts1 = nn.ModuleList()
+ for _ in range(len(self.convs1)):
+ if act_fn == "snakebeta":
+ act = SnakeBeta(channels, use_beta=True)
+ elif act_fn == "snake":
+ act = SnakeBeta(channels, use_beta=False)
+ else:
+ act = nn.LeakyReLU(negative_slope=leaky_relu_negative_slope)
+
+ if antialias:
+ act = AntiAliasAct1d(act, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
+ self.acts1.append(act)
+
+ self.convs2 = nn.ModuleList(
+ [
+ nn.Conv1d(channels, channels, kernel_size, stride=stride, dilation=1, padding=padding_mode)
+ for _ in range(len(dilations))
+ ]
+ )
+ self.acts2 = nn.ModuleList()
+ for _ in range(len(self.convs2)):
+ if act_fn == "snakebeta":
+ act = SnakeBeta(channels, use_beta=True)
+ elif act_fn == "snake":
+ act = SnakeBeta(channels, use_beta=False)
+ else:
+ act_fn = nn.LeakyReLU(negative_slope=leaky_relu_negative_slope)
+
+ if antialias:
+ act = AntiAliasAct1d(act, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
+ self.acts2.append(act)
+
+ def forward(self, x: torch.Tensor) -> torch.Tensor:
+ for act1, conv1, act2, conv2 in zip(self.acts1, self.convs1, self.acts2, self.convs2):
+ xt = act1(x)
+ xt = conv1(xt)
+ xt = act2(xt)
+ xt = conv2(xt)
+ x = x + xt
+ return x
+
+
+class LTX2Vocoder(ModelMixin, ConfigMixin):
+ r"""
+ LTX 2.0 vocoder for converting generated mel spectrograms back to audio waveforms.
+ """
+
+ @register_to_config
+ def __init__(
+ self,
+ in_channels: int = 128,
+ hidden_channels: int = 1024,
+ out_channels: int = 2,
+ upsample_kernel_sizes: list[int] = [16, 15, 8, 4, 4],
+ upsample_factors: list[int] = [6, 5, 2, 2, 2],
+ resnet_kernel_sizes: list[int] = [3, 7, 11],
+ resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
+ act_fn: str = "leaky_relu",
+ leaky_relu_negative_slope: float = 0.1,
+ antialias: bool = False,
+ antialias_ratio: int = 2,
+ antialias_kernel_size: int = 12,
+ final_act_fn: str | None = "tanh", # tanh, clamp, None
+ final_bias: bool = True,
+ output_sampling_rate: int = 24000,
+ ):
+ super().__init__()
+ self.num_upsample_layers = len(upsample_kernel_sizes)
+ self.resnets_per_upsample = len(resnet_kernel_sizes)
+ self.out_channels = out_channels
+ self.total_upsample_factor = math.prod(upsample_factors)
+ self.act_fn = act_fn
+ self.negative_slope = leaky_relu_negative_slope
+ self.final_act_fn = final_act_fn
+
+ if self.num_upsample_layers != len(upsample_factors):
+ raise ValueError(
+ f"`upsample_kernel_sizes` and `upsample_factors` should be lists of the same length but are length"
+ f" {self.num_upsample_layers} and {len(upsample_factors)}, respectively."
+ )
+
+ if self.resnets_per_upsample != len(resnet_dilations):
+ raise ValueError(
+ f"`resnet_kernel_sizes` and `resnet_dilations` should be lists of the same length but are length"
+ f" {len(self.resnets_per_upsample)} and {len(resnet_dilations)}, respectively."
+ )
+
+ supported_act_fns = ["snakebeta", "snake", "leaky_relu"]
+ if self.act_fn not in supported_act_fns:
+ raise ValueError(
+ f"Unsupported activation function: {self.act_fn}. Currently supported values of `act_fn` are "
+ f"{supported_act_fns}."
+ )
+
+ self.conv_in = nn.Conv1d(in_channels, hidden_channels, kernel_size=7, stride=1, padding=3)
+
+ self.upsamplers = nn.ModuleList()
+ self.resnets = nn.ModuleList()
+ input_channels = hidden_channels
+ for i, (stride, kernel_size) in enumerate(zip(upsample_factors, upsample_kernel_sizes)):
+ output_channels = input_channels // 2
+ self.upsamplers.append(
+ nn.ConvTranspose1d(
+ input_channels, # hidden_channels // (2 ** i)
+ output_channels, # hidden_channels // (2 ** (i + 1))
+ kernel_size,
+ stride=stride,
+ padding=(kernel_size - stride) // 2,
+ )
+ )
+
+ for kernel_size, dilations in zip(resnet_kernel_sizes, resnet_dilations):
+ self.resnets.append(
+ ResBlock(
+ channels=output_channels,
+ kernel_size=kernel_size,
+ dilations=dilations,
+ act_fn=act_fn,
+ leaky_relu_negative_slope=leaky_relu_negative_slope,
+ antialias=antialias,
+ antialias_ratio=antialias_ratio,
+ antialias_kernel_size=antialias_kernel_size,
+ )
+ )
+ input_channels = output_channels
+
+ if act_fn == "snakebeta" or act_fn == "snake":
+ # Always use antialiasing
+ act_out = SnakeBeta(channels=output_channels, use_beta=True)
+ self.act_out = AntiAliasAct1d(act_out, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
+ elif act_fn == "leaky_relu":
+ # NOTE: does NOT use self.negative_slope, following the original code
+ self.act_out = nn.LeakyReLU()
+
+ self.conv_out = nn.Conv1d(output_channels, out_channels, 7, stride=1, padding=3, bias=final_bias)
+
+ def forward(self, hidden_states: torch.Tensor, time_last: bool = False) -> torch.Tensor:
+ r"""
+ Forward pass of the vocoder.
+
+ Args:
+ hidden_states (`torch.Tensor`):
+ Input Mel spectrogram tensor of shape `(batch_size, num_channels, time, num_mel_bins)` if `time_last`
+ is `False` (the default) or shape `(batch_size, num_channels, num_mel_bins, time)` if `time_last` is
+ `True`.
+ time_last (`bool`, *optional*, defaults to `False`):
+ Whether the last dimension of the input is the time/frame dimension or the Mel bins dimension.
+
+ Returns:
+ `torch.Tensor`:
+ Audio waveform tensor of shape (batch_size, out_channels, audio_length)
+ """
+
+ # Ensure that the time/frame dimension is last
+ if not time_last:
+ hidden_states = hidden_states.transpose(2, 3)
+ # Combine channels and frequency (mel bins) dimensions
+ hidden_states = hidden_states.flatten(1, 2)
+
+ hidden_states = self.conv_in(hidden_states)
+
+ for i in range(self.num_upsample_layers):
+ if self.act_fn == "leaky_relu":
+ # Other activations are inside each upsampling block
+ hidden_states = F.leaky_relu(hidden_states, negative_slope=self.negative_slope)
+ hidden_states = self.upsamplers[i](hidden_states)
+
+ # Run all resnets in parallel on hidden_states
+ start = i * self.resnets_per_upsample
+ end = (i + 1) * self.resnets_per_upsample
+ resnet_outputs = torch.stack([self.resnets[j](hidden_states) for j in range(start, end)], dim=0)
+
+ hidden_states = torch.mean(resnet_outputs, dim=0)
+
+ hidden_states = self.act_out(hidden_states)
+ hidden_states = self.conv_out(hidden_states)
+ if self.final_act_fn == "tanh":
+ hidden_states = torch.tanh(hidden_states)
+ elif self.final_act_fn == "clamp":
+ hidden_states = torch.clamp(hidden_states, -1, 1)
+
+ return hidden_states
+
+
+class CausalSTFT(nn.Module):
+ """
+ Performs a causal short-time Fourier transform (STFT) using causal Hann windows on a waveform. The DFT bases
+ multiplied by the Hann windows are pre-calculated and stored as buffers. For exact parity with training, the exact
+ buffers should be loaded from the checkpoint in bfloat16.
+ """
+
+ def __init__(self, filter_length: int = 512, hop_length: int = 80, window_length: int = 512):
+ super().__init__()
+ self.hop_length = hop_length
+ self.window_length = window_length
+ n_freqs = filter_length // 2 + 1
+
+ self.register_buffer("forward_basis", torch.zeros(n_freqs * 2, 1, filter_length), persistent=True)
+ self.register_buffer("inverse_basis", torch.zeros(n_freqs * 2, 1, filter_length), persistent=True)
+
+ def forward(self, waveform: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
+ if waveform.ndim == 2:
+ waveform = waveform.unsqueeze(1) # [B, num_channels, num_samples]
+
+ left_pad = max(0, self.window_length - self.hop_length) # causal: left-only
+ waveform = F.pad(waveform, (left_pad, 0))
+
+ spec = F.conv1d(waveform, self.forward_basis, stride=self.hop_length, padding=0)
+ n_freqs = spec.shape[1] // 2
+ real, imag = spec[:, :n_freqs], spec[:, n_freqs:]
+ magnitude = torch.sqrt(real**2 + imag**2)
+ phase = torch.atan2(imag.float(), real.float()).to(dtype=real.dtype)
+ return magnitude, phase
+
+
+class MelSTFT(nn.Module):
+ """
+ Calculates a causal log-mel spectrogram from a waveform. Uses a pre-calculated mel filterbank, which should be
+ loaded from the checkpoint in bfloat16.
+ """
+
+ def __init__(
+ self,
+ filter_length: int = 512,
+ hop_length: int = 80,
+ window_length: int = 512,
+ num_mel_channels: int = 64,
+ ):
+ super().__init__()
+ self.stft_fn = CausalSTFT(filter_length, hop_length, window_length)
+
+ num_freqs = filter_length // 2 + 1
+ self.register_buffer("mel_basis", torch.zeros(num_mel_channels, num_freqs), persistent=True)
+
+ def forward(self, waveform: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]:
+ magnitude, phase = self.stft_fn(waveform)
+ energy = torch.norm(magnitude, dim=1)
+ mel = torch.matmul(self.mel_basis.to(magnitude.dtype), magnitude)
+ log_mel = torch.log(torch.clamp(mel, min=1e-5))
+ return log_mel, magnitude, phase, energy
+
+
+class LTX2VocoderWithBWE(ModelMixin, ConfigMixin):
+ """
+ LTX-2.X vocoder with bandwidth extension (BWE) upsampling. The vocoder and the BWE module run in sequence, with the
+ BWE module upsampling the vocoder output waveform to a higher sampling rate. The BWE module itself has the same
+ architecture as the original vocoder.
+ """
+
+ @register_to_config
+ def __init__(
+ self,
+ in_channels: int = 128,
+ hidden_channels: int = 1536,
+ out_channels: int = 2,
+ upsample_kernel_sizes: list[int] = [11, 4, 4, 4, 4, 4],
+ upsample_factors: list[int] = [5, 2, 2, 2, 2, 2],
+ resnet_kernel_sizes: list[int] = [3, 7, 11],
+ resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
+ act_fn: str = "snakebeta",
+ leaky_relu_negative_slope: float = 0.1,
+ antialias: bool = True,
+ antialias_ratio: int = 2,
+ antialias_kernel_size: int = 12,
+ final_act_fn: str | None = None,
+ final_bias: bool = False,
+ bwe_in_channels: int = 128,
+ bwe_hidden_channels: int = 512,
+ bwe_out_channels: int = 2,
+ bwe_upsample_kernel_sizes: list[int] = [12, 11, 4, 4, 4],
+ bwe_upsample_factors: list[int] = [6, 5, 2, 2, 2],
+ bwe_resnet_kernel_sizes: list[int] = [3, 7, 11],
+ bwe_resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
+ bwe_act_fn: str = "snakebeta",
+ bwe_leaky_relu_negative_slope: float = 0.1,
+ bwe_antialias: bool = True,
+ bwe_antialias_ratio: int = 2,
+ bwe_antialias_kernel_size: int = 12,
+ bwe_final_act_fn: str | None = None,
+ bwe_final_bias: bool = False,
+ filter_length: int = 512,
+ hop_length: int = 80,
+ window_length: int = 512,
+ num_mel_channels: int = 64,
+ input_sampling_rate: int = 16000,
+ output_sampling_rate: int = 48000,
+ ):
+ super().__init__()
+
+ self.vocoder = LTX2Vocoder(
+ in_channels=in_channels,
+ hidden_channels=hidden_channels,
+ out_channels=out_channels,
+ upsample_kernel_sizes=upsample_kernel_sizes,
+ upsample_factors=upsample_factors,
+ resnet_kernel_sizes=resnet_kernel_sizes,
+ resnet_dilations=resnet_dilations,
+ act_fn=act_fn,
+ leaky_relu_negative_slope=leaky_relu_negative_slope,
+ antialias=antialias,
+ antialias_ratio=antialias_ratio,
+ antialias_kernel_size=antialias_kernel_size,
+ final_act_fn=final_act_fn,
+ final_bias=final_bias,
+ output_sampling_rate=input_sampling_rate,
+ )
+ self.bwe_generator = LTX2Vocoder(
+ in_channels=bwe_in_channels,
+ hidden_channels=bwe_hidden_channels,
+ out_channels=bwe_out_channels,
+ upsample_kernel_sizes=bwe_upsample_kernel_sizes,
+ upsample_factors=bwe_upsample_factors,
+ resnet_kernel_sizes=bwe_resnet_kernel_sizes,
+ resnet_dilations=bwe_resnet_dilations,
+ act_fn=bwe_act_fn,
+ leaky_relu_negative_slope=bwe_leaky_relu_negative_slope,
+ antialias=bwe_antialias,
+ antialias_ratio=bwe_antialias_ratio,
+ antialias_kernel_size=bwe_antialias_kernel_size,
+ final_act_fn=bwe_final_act_fn,
+ final_bias=bwe_final_bias,
+ output_sampling_rate=output_sampling_rate,
+ )
+
+ self.mel_stft = MelSTFT(
+ filter_length=filter_length,
+ hop_length=hop_length,
+ window_length=window_length,
+ num_mel_channels=num_mel_channels,
+ )
+
+ self.resampler = UpSample1d(
+ ratio=output_sampling_rate // input_sampling_rate,
+ window_type="hann",
+ persistent=False,
+ )
+
+ def forward(self, mel_spec: torch.Tensor) -> torch.Tensor:
+ r"""
+ Args:
+ mel_spec (`torch.Tensor`):
+ Input Mel spectrogram tensor of shape `(batch_size, num_channels, time, num_mel_bins)`.
+
+ Returns:
+ `torch.Tensor`:
+ Bandwidth-extended audio waveform of shape `(batch_size, out_channels, audio_length)` at
+ `output_sampling_rate`.
+ """
+ # 1. Run stage 1 vocoder to get low sampling rate waveform
+ x = self.vocoder(mel_spec)
+ batch_size, num_channels, num_samples = x.shape
+
+ # Pad to exact multiple of hop_length for exact mel frame count
+ remainder = num_samples % self.config.hop_length
+ if remainder != 0:
+ x = F.pad(x, (0, self.hop_length - remainder))
+
+ # 2. Compute mel spectrogram on vocoder output
+ mel, _, _, _ = self.mel_stft(x.flatten(0, 1))
+ mel = mel.unflatten(0, (-1, num_channels))
+
+ # 3. Run bandwidth extender (BWE) on new mel spectrogram
+ mel_for_bwe = mel.transpose(2, 3) # [B, C, num_mel_bins, num_frames] --> [B, C, num_frames, num_mel_bins]
+ residual = self.bwe_generator(mel_for_bwe)
+
+ # 4. Residual connection with resampler
+ skip = self.resampler(x)
+ waveform = torch.clamp(residual + skip, -1, 1)
+ output_samples = num_samples * self.config.output_sampling_rate // self.config.input_sampling_rate
+ waveform = waveform[..., :output_samples]
+ return waveform
diff --git a/src/diffusers/models/condition_embedders/__init__.py b/src/diffusers/models/condition_embedders/__init__.py
index 9f757c3de2fa..229c2a7ee564 100644
--- a/src/diffusers/models/condition_embedders/__init__.py
+++ b/src/diffusers/models/condition_embedders/__init__.py
@@ -12,3 +12,4 @@
from .condition_embedder_p_h3_image import PH3ImageTextConnector
from .condition_embedder_stable_audio import StableAudioProjectionModel
from .condition_embedder_stable_audio_3 import StableAudio3DurationEmbedder
+ from .condition_embedder_stable_unclip import StableUnCLIPImageNormalizer
diff --git a/src/diffusers/models/condition_embedders/condition_embedder_stable_unclip.py b/src/diffusers/models/condition_embedders/condition_embedder_stable_unclip.py
new file mode 100644
index 000000000000..d376cf990a5e
--- /dev/null
+++ b/src/diffusers/models/condition_embedders/condition_embedder_stable_unclip.py
@@ -0,0 +1,55 @@
+# Copyright 2026 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import torch
+from torch import nn
+
+from ...configuration_utils import ConfigMixin, register_to_config
+from ..modeling_utils import ModelMixin
+
+
+class StableUnCLIPImageNormalizer(ModelMixin, ConfigMixin):
+ """
+ This class is used to hold the mean and standard deviation of the CLIP embedder used in stable unCLIP.
+
+ It is used to normalize the image embeddings before the noise is applied and un-normalize the noised image
+ embeddings.
+ """
+
+ @register_to_config
+ def __init__(
+ self,
+ embedding_dim: int = 768,
+ ):
+ super().__init__()
+
+ self.mean = nn.Parameter(torch.zeros(1, embedding_dim))
+ self.std = nn.Parameter(torch.ones(1, embedding_dim))
+
+ def to(
+ self,
+ torch_device: str | torch.device | None = None,
+ torch_dtype: torch.dtype | None = None,
+ ):
+ self.mean = nn.Parameter(self.mean.to(torch_device).to(torch_dtype))
+ self.std = nn.Parameter(self.std.to(torch_device).to(torch_dtype))
+ return self
+
+ def scale(self, embeds):
+ embeds = (embeds - self.mean) * 1.0 / self.std
+ return embeds
+
+ def unscale(self, embeds):
+ embeds = (embeds * self.std) + self.mean
+ return embeds
diff --git a/src/diffusers/models/unets/__init__.py b/src/diffusers/models/unets/__init__.py
index d3b69d6d5e8c..da77d6a80a20 100644
--- a/src/diffusers/models/unets/__init__.py
+++ b/src/diffusers/models/unets/__init__.py
@@ -5,6 +5,7 @@
from .unet_1d import UNet1DModel
from .unet_2d import UNet2DModel
from .unet_2d_condition import UNet2DConditionModel
+ from .unet_2d_condition_audioldm2 import AudioLDM2UNet2DConditionModel
from .unet_3d_condition import UNet3DConditionModel
from .unet_dreamlite import DreamLiteUNetModel
from .unet_i2vgen_xl import I2VGenXLUNet
diff --git a/src/diffusers/models/unets/unet_2d_condition_audioldm2.py b/src/diffusers/models/unets/unet_2d_condition_audioldm2.py
new file mode 100644
index 000000000000..6b43d5d0d5ef
--- /dev/null
+++ b/src/diffusers/models/unets/unet_2d_condition_audioldm2.py
@@ -0,0 +1,1299 @@
+# Copyright 2026 The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Any
+
+import torch
+import torch.nn as nn
+
+from ...configuration_utils import ConfigMixin, register_to_config
+from ...loaders import UNet2DConditionLoadersMixin
+from ...utils import logging
+from ..activations import get_activation
+from ..attention import AttentionMixin
+from ..attention_processor import (
+ ADDED_KV_ATTENTION_PROCESSORS,
+ CROSS_ATTENTION_PROCESSORS,
+ AttnAddedKVProcessor,
+ AttnProcessor,
+)
+from ..embeddings import TimestepEmbedding, Timesteps
+from ..modeling_utils import ModelMixin
+from ..resnet import Downsample2D, ResnetBlock2D, Upsample2D
+from ..transformers.transformer_2d import Transformer2DModel
+from .unet_2d_blocks import DownBlock2D, UpBlock2D
+from .unet_2d_condition import UNet2DConditionOutput
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+class AudioLDM2UNet2DConditionModel(ModelMixin, AttentionMixin, ConfigMixin, UNet2DConditionLoadersMixin):
+ r"""
+ A conditional 2D UNet model that takes a noisy sample, conditional state, and a timestep and returns a sample
+ shaped output. Compared to the vanilla [`UNet2DConditionModel`], this variant optionally includes an additional
+ self-attention layer in each Transformer block, as well as multiple cross-attention layers. It also allows for up
+ to two cross-attention embeddings, `encoder_hidden_states` and `encoder_hidden_states_1`.
+
+ This model inherits from [`ModelMixin`]. Check the superclass documentation for it's generic methods implemented
+ for all models (such as downloading or saving).
+
+ Parameters:
+ sample_size (`int` or `tuple[int, int]`, *optional*, defaults to `None`):
+ Height and width of input/output sample.
+ in_channels (`int`, *optional*, defaults to 4): Number of channels in the input sample.
+ out_channels (`int`, *optional*, defaults to 4): Number of channels in the output.
+ flip_sin_to_cos (`bool`, *optional*, defaults to `False`):
+ Whether to flip the sin to cos in the time embedding.
+ freq_shift (`int`, *optional*, defaults to 0): The frequency shift to apply to the time embedding.
+ down_block_types (`tuple[str]`, *optional*, defaults to `("CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "DownBlock2D")`):
+ The tuple of downsample blocks to use.
+ mid_block_type (`str`, *optional*, defaults to `"UNetMidBlock2DCrossAttn"`):
+ Block type for middle of UNet, it can only be `UNetMidBlock2DCrossAttn` for AudioLDM2.
+ up_block_types (`tuple[str]`, *optional*, defaults to `("UpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D")`):
+ The tuple of upsample blocks to use.
+ only_cross_attention (`bool` or `tuple[bool]`, *optional*, default to `False`):
+ Whether to include self-attention in the basic transformer blocks, see
+ [`~models.attention.BasicTransformerBlock`].
+ block_out_channels (`tuple[int]`, *optional*, defaults to `(320, 640, 1280, 1280)`):
+ The tuple of output channels for each block.
+ layers_per_block (`int`, *optional*, defaults to 2): The number of layers per block.
+ downsample_padding (`int`, *optional*, defaults to 1): The padding to use for the downsampling convolution.
+ mid_block_scale_factor (`float`, *optional*, defaults to 1.0): The scale factor to use for the mid block.
+ act_fn (`str`, *optional*, defaults to `"silu"`): The activation function to use.
+ norm_num_groups (`int`, *optional*, defaults to 32): The number of groups to use for the normalization.
+ If `None`, normalization and activation layers is skipped in post-processing.
+ norm_eps (`float`, *optional*, defaults to 1e-5): The epsilon to use for the normalization.
+ cross_attention_dim (`int` or `tuple[int]`, *optional*, defaults to 1280):
+ The dimension of the cross attention features.
+ transformer_layers_per_block (`int` or `tuple[int]`, *optional*, defaults to 1):
+ The number of transformer blocks of type [`~models.attention.BasicTransformerBlock`]. Only relevant for
+ [`~models.unet_2d_blocks.CrossAttnDownBlock2D`], [`~models.unet_2d_blocks.CrossAttnUpBlock2D`],
+ [`~models.unet_2d_blocks.UNetMidBlock2DCrossAttn`].
+ attention_head_dim (`int`, *optional*, defaults to 8): The dimension of the attention heads.
+ num_attention_heads (`int`, *optional*):
+ The number of attention heads. If not defined, defaults to `attention_head_dim`
+ resnet_time_scale_shift (`str`, *optional*, defaults to `"default"`): Time scale shift config
+ for ResNet blocks (see [`~models.resnet.ResnetBlock2D`]). Choose from `default` or `scale_shift`.
+ class_embed_type (`str`, *optional*, defaults to `None`):
+ The type of class embedding to use which is ultimately summed with the time embeddings. Choose from `None`,
+ `"timestep"`, `"identity"`, `"projection"`, or `"simple_projection"`.
+ num_class_embeds (`int`, *optional*, defaults to `None`):
+ Input dimension of the learnable embedding matrix to be projected to `time_embed_dim`, when performing
+ class conditioning with `class_embed_type` equal to `None`.
+ time_embedding_type (`str`, *optional*, defaults to `positional`):
+ The type of position embedding to use for timesteps. Choose from `positional` or `fourier`.
+ time_embedding_dim (`int`, *optional*, defaults to `None`):
+ An optional override for the dimension of the projected time embedding.
+ time_embedding_act_fn (`str`, *optional*, defaults to `None`):
+ Optional activation function to use only once on the time embeddings before they are passed to the rest of
+ the UNet. Choose from `silu`, `mish`, `gelu`, and `swish`.
+ timestep_post_act (`str`, *optional*, defaults to `None`):
+ The second activation function to use in timestep embedding. Choose from `silu`, `mish` and `gelu`.
+ time_cond_proj_dim (`int`, *optional*, defaults to `None`):
+ The dimension of `cond_proj` layer in the timestep embedding.
+ conv_in_kernel (`int`, *optional*, default to `3`): The kernel size of `conv_in` layer.
+ conv_out_kernel (`int`, *optional*, default to `3`): The kernel size of `conv_out` layer.
+ projection_class_embeddings_input_dim (`int`, *optional*): The dimension of the `class_labels` input when
+ `class_embed_type="projection"`. Required when `class_embed_type="projection"`.
+ class_embeddings_concat (`bool`, *optional*, defaults to `False`): Whether to concatenate the time
+ embeddings with the class embeddings.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ sample_size: int | None = None,
+ in_channels: int = 4,
+ out_channels: int = 4,
+ flip_sin_to_cos: bool = True,
+ freq_shift: int = 0,
+ down_block_types: tuple[str] = (
+ "CrossAttnDownBlock2D",
+ "DownBlock2D",
+ ),
+ mid_block_type: str = "UNetMidBlock2DCrossAttn",
+ up_block_types: tuple[str] = ("UpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D"),
+ only_cross_attention: bool | tuple[bool] = False,
+ block_out_channels: tuple[int] = (320, 640, 1280, 1280),
+ layers_per_block: int | tuple[int] = 2,
+ downsample_padding: int = 1,
+ mid_block_scale_factor: float = 1,
+ act_fn: str = "silu",
+ norm_num_groups: int | None = 32,
+ norm_eps: float = 1e-5,
+ cross_attention_dim: int | tuple[int] = 1280,
+ transformer_layers_per_block: int | tuple[int] = 1,
+ attention_head_dim: int | tuple[int] = 8,
+ num_attention_heads: int | tuple[int] | None = None,
+ use_linear_projection: bool = False,
+ class_embed_type: str | None = None,
+ num_class_embeds: int | None = None,
+ upcast_attention: bool = False,
+ resnet_time_scale_shift: str = "default",
+ time_embedding_type: str = "positional",
+ time_embedding_dim: int | None = None,
+ time_embedding_act_fn: str | None = None,
+ timestep_post_act: str | None = None,
+ time_cond_proj_dim: int | None = None,
+ conv_in_kernel: int = 3,
+ conv_out_kernel: int = 3,
+ projection_class_embeddings_input_dim: int | None = None,
+ class_embeddings_concat: bool = False,
+ ):
+ super().__init__()
+
+ self.sample_size = sample_size
+
+ if num_attention_heads is not None:
+ raise ValueError(
+ "At the moment it is not possible to define the number of attention heads via `num_attention_heads` because of a naming issue as described in https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131. Passing `num_attention_heads` will only be supported in diffusers v0.19."
+ )
+
+ # If `num_attention_heads` is not defined (which is the case for most models)
+ # it will default to `attention_head_dim`. This looks weird upon first reading it and it is.
+ # The reason for this behavior is to correct for incorrectly named variables that were introduced
+ # when this library was created. The incorrect naming was only discovered much later in https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131
+ # Changing `attention_head_dim` to `num_attention_heads` for 40,000+ configurations is too backwards breaking
+ # which is why we correct for the naming here.
+ num_attention_heads = num_attention_heads or attention_head_dim
+
+ # Check inputs
+ if len(down_block_types) != len(up_block_types):
+ raise ValueError(
+ f"Must provide the same number of `down_block_types` as `up_block_types`. `down_block_types`: {down_block_types}. `up_block_types`: {up_block_types}."
+ )
+
+ if len(block_out_channels) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `block_out_channels` as `down_block_types`. `block_out_channels`: {block_out_channels}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(only_cross_attention, bool) and len(only_cross_attention) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `only_cross_attention` as `down_block_types`. `only_cross_attention`: {only_cross_attention}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(num_attention_heads, int) and len(num_attention_heads) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `num_attention_heads` as `down_block_types`. `num_attention_heads`: {num_attention_heads}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(attention_head_dim, int) and len(attention_head_dim) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `attention_head_dim` as `down_block_types`. `attention_head_dim`: {attention_head_dim}. `down_block_types`: {down_block_types}."
+ )
+
+ if isinstance(cross_attention_dim, list) and len(cross_attention_dim) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `cross_attention_dim` as `down_block_types`. `cross_attention_dim`: {cross_attention_dim}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(layers_per_block, int) and len(layers_per_block) != len(down_block_types):
+ raise ValueError(
+ f"Must provide the same number of `layers_per_block` as `down_block_types`. `layers_per_block`: {layers_per_block}. `down_block_types`: {down_block_types}."
+ )
+
+ # input
+ conv_in_padding = (conv_in_kernel - 1) // 2
+ self.conv_in = nn.Conv2d(
+ in_channels, block_out_channels[0], kernel_size=conv_in_kernel, padding=conv_in_padding
+ )
+
+ # time
+ if time_embedding_type == "positional":
+ time_embed_dim = time_embedding_dim or block_out_channels[0] * 4
+
+ self.time_proj = Timesteps(block_out_channels[0], flip_sin_to_cos, freq_shift)
+ timestep_input_dim = block_out_channels[0]
+ else:
+ raise ValueError(f"{time_embedding_type} does not exist. Please make sure to use `positional`.")
+
+ self.time_embedding = TimestepEmbedding(
+ timestep_input_dim,
+ time_embed_dim,
+ act_fn=act_fn,
+ post_act_fn=timestep_post_act,
+ cond_proj_dim=time_cond_proj_dim,
+ )
+
+ # class embedding
+ if class_embed_type is None and num_class_embeds is not None:
+ self.class_embedding = nn.Embedding(num_class_embeds, time_embed_dim)
+ elif class_embed_type == "timestep":
+ self.class_embedding = TimestepEmbedding(timestep_input_dim, time_embed_dim, act_fn=act_fn)
+ elif class_embed_type == "identity":
+ self.class_embedding = nn.Identity(time_embed_dim, time_embed_dim)
+ elif class_embed_type == "projection":
+ if projection_class_embeddings_input_dim is None:
+ raise ValueError(
+ "`class_embed_type`: 'projection' requires `projection_class_embeddings_input_dim` be set"
+ )
+ # The projection `class_embed_type` is the same as the timestep `class_embed_type` except
+ # 1. the `class_labels` inputs are not first converted to sinusoidal embeddings
+ # 2. it projects from an arbitrary input dimension.
+ #
+ # Note that `TimestepEmbedding` is quite general, being mainly linear layers and activations.
+ # When used for embedding actual timesteps, the timesteps are first converted to sinusoidal embeddings.
+ # As a result, `TimestepEmbedding` can be passed arbitrary vectors.
+ self.class_embedding = TimestepEmbedding(projection_class_embeddings_input_dim, time_embed_dim)
+ elif class_embed_type == "simple_projection":
+ if projection_class_embeddings_input_dim is None:
+ raise ValueError(
+ "`class_embed_type`: 'simple_projection' requires `projection_class_embeddings_input_dim` be set"
+ )
+ self.class_embedding = nn.Linear(projection_class_embeddings_input_dim, time_embed_dim)
+ else:
+ self.class_embedding = None
+
+ if time_embedding_act_fn is None:
+ self.time_embed_act = None
+ else:
+ self.time_embed_act = get_activation(time_embedding_act_fn)
+
+ self.down_blocks = nn.ModuleList([])
+ self.up_blocks = nn.ModuleList([])
+
+ if isinstance(only_cross_attention, bool):
+ only_cross_attention = [only_cross_attention] * len(down_block_types)
+
+ if isinstance(num_attention_heads, int):
+ num_attention_heads = (num_attention_heads,) * len(down_block_types)
+
+ if isinstance(cross_attention_dim, int):
+ cross_attention_dim = (cross_attention_dim,) * len(down_block_types)
+
+ if isinstance(layers_per_block, int):
+ layers_per_block = [layers_per_block] * len(down_block_types)
+
+ if isinstance(transformer_layers_per_block, int):
+ transformer_layers_per_block = [transformer_layers_per_block] * len(down_block_types)
+
+ if class_embeddings_concat:
+ # The time embeddings are concatenated with the class embeddings. The dimension of the
+ # time embeddings passed to the down, middle, and up blocks is twice the dimension of the
+ # regular time embeddings
+ blocks_time_embed_dim = time_embed_dim * 2
+ else:
+ blocks_time_embed_dim = time_embed_dim
+
+ # down
+ output_channel = block_out_channels[0]
+ for i, down_block_type in enumerate(down_block_types):
+ input_channel = output_channel
+ output_channel = block_out_channels[i]
+ is_final_block = i == len(block_out_channels) - 1
+
+ down_block = get_down_block(
+ down_block_type,
+ num_layers=layers_per_block[i],
+ transformer_layers_per_block=transformer_layers_per_block[i],
+ in_channels=input_channel,
+ out_channels=output_channel,
+ temb_channels=blocks_time_embed_dim,
+ add_downsample=not is_final_block,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=cross_attention_dim[i],
+ num_attention_heads=num_attention_heads[i],
+ downsample_padding=downsample_padding,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ self.down_blocks.append(down_block)
+
+ # mid
+ if mid_block_type == "UNetMidBlock2DCrossAttn":
+ self.mid_block = UNetMidBlock2DCrossAttn(
+ transformer_layers_per_block=transformer_layers_per_block[-1],
+ in_channels=block_out_channels[-1],
+ temb_channels=blocks_time_embed_dim,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ output_scale_factor=mid_block_scale_factor,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ cross_attention_dim=cross_attention_dim[-1],
+ num_attention_heads=num_attention_heads[-1],
+ resnet_groups=norm_num_groups,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ )
+ else:
+ raise ValueError(
+ f"unknown mid_block_type : {mid_block_type}. Should be `UNetMidBlock2DCrossAttn` for AudioLDM2."
+ )
+
+ # count how many layers upsample the images
+ self.num_upsamplers = 0
+
+ # up
+ reversed_block_out_channels = list(reversed(block_out_channels))
+ reversed_num_attention_heads = list(reversed(num_attention_heads))
+ reversed_layers_per_block = list(reversed(layers_per_block))
+ reversed_cross_attention_dim = list(reversed(cross_attention_dim))
+ reversed_transformer_layers_per_block = list(reversed(transformer_layers_per_block))
+ only_cross_attention = list(reversed(only_cross_attention))
+
+ output_channel = reversed_block_out_channels[0]
+ for i, up_block_type in enumerate(up_block_types):
+ is_final_block = i == len(block_out_channels) - 1
+
+ prev_output_channel = output_channel
+ output_channel = reversed_block_out_channels[i]
+ input_channel = reversed_block_out_channels[min(i + 1, len(block_out_channels) - 1)]
+
+ # add upsample block for all BUT final layer
+ if not is_final_block:
+ add_upsample = True
+ self.num_upsamplers += 1
+ else:
+ add_upsample = False
+
+ up_block = get_up_block(
+ up_block_type,
+ num_layers=reversed_layers_per_block[i] + 1,
+ transformer_layers_per_block=reversed_transformer_layers_per_block[i],
+ in_channels=input_channel,
+ out_channels=output_channel,
+ prev_output_channel=prev_output_channel,
+ temb_channels=blocks_time_embed_dim,
+ add_upsample=add_upsample,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=reversed_cross_attention_dim[i],
+ num_attention_heads=reversed_num_attention_heads[i],
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ self.up_blocks.append(up_block)
+ prev_output_channel = output_channel
+
+ # out
+ if norm_num_groups is not None:
+ self.conv_norm_out = nn.GroupNorm(
+ num_channels=block_out_channels[0], num_groups=norm_num_groups, eps=norm_eps
+ )
+
+ self.conv_act = get_activation(act_fn)
+
+ else:
+ self.conv_norm_out = None
+ self.conv_act = None
+
+ conv_out_padding = (conv_out_kernel - 1) // 2
+ self.conv_out = nn.Conv2d(
+ block_out_channels[0], out_channels, kernel_size=conv_out_kernel, padding=conv_out_padding
+ )
+
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_default_attn_processor
+ def set_default_attn_processor(self):
+ """
+ Disables custom attention processors and sets the default attention implementation.
+ """
+ if all(proc.__class__ in ADDED_KV_ATTENTION_PROCESSORS for proc in self.attn_processors.values()):
+ processor = AttnAddedKVProcessor()
+ elif all(proc.__class__ in CROSS_ATTENTION_PROCESSORS for proc in self.attn_processors.values()):
+ processor = AttnProcessor()
+ else:
+ raise ValueError(
+ f"Cannot call `set_default_attn_processor` when attention processors are of type {next(iter(self.attn_processors.values()))}"
+ )
+
+ self.set_attn_processor(processor)
+
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_attention_slice
+ def set_attention_slice(self, slice_size):
+ r"""
+ Enable sliced attention computation.
+
+ When this option is enabled, the attention module splits the input tensor in slices to compute attention in
+ several steps. This is useful for saving some memory in exchange for a small decrease in speed.
+
+ Args:
+ slice_size (`str` or `int` or `list(int)`, *optional*, defaults to `"auto"`):
+ When `"auto"`, input to the attention heads is halved, so attention is computed in two steps. If
+ `"max"`, maximum amount of memory is saved by running only one slice at a time. If a number is
+ provided, uses as many slices as `attention_head_dim // slice_size`. In this case, `attention_head_dim`
+ must be a multiple of `slice_size`.
+ """
+ sliceable_head_dims = []
+
+ def fn_recursive_retrieve_sliceable_dims(module: torch.nn.Module):
+ if hasattr(module, "set_attention_slice"):
+ sliceable_head_dims.append(module.sliceable_head_dim)
+
+ for child in module.children():
+ fn_recursive_retrieve_sliceable_dims(child)
+
+ # retrieve number of attention layers
+ for module in self.children():
+ fn_recursive_retrieve_sliceable_dims(module)
+
+ num_sliceable_layers = len(sliceable_head_dims)
+
+ if slice_size == "auto":
+ # half the attention head size is usually a good trade-off between
+ # speed and memory
+ slice_size = [dim // 2 for dim in sliceable_head_dims]
+ elif slice_size == "max":
+ # make smallest slice possible
+ slice_size = num_sliceable_layers * [1]
+
+ slice_size = num_sliceable_layers * [slice_size] if not isinstance(slice_size, list) else slice_size
+
+ if len(slice_size) != len(sliceable_head_dims):
+ raise ValueError(
+ f"You have provided {len(slice_size)}, but {self.config} has {len(sliceable_head_dims)} different"
+ f" attention layers. Make sure to match `len(slice_size)` to be {len(sliceable_head_dims)}."
+ )
+
+ for i in range(len(slice_size)):
+ size = slice_size[i]
+ dim = sliceable_head_dims[i]
+ if size is not None and size > dim:
+ raise ValueError(f"size {size} has to be smaller or equal to {dim}.")
+
+ # Recursively walk through all the children.
+ # Any children which exposes the set_attention_slice method
+ # gets the message
+ def fn_recursive_set_attention_slice(module: torch.nn.Module, slice_size: list[int]):
+ if hasattr(module, "set_attention_slice"):
+ module.set_attention_slice(slice_size.pop())
+
+ for child in module.children():
+ fn_recursive_set_attention_slice(child, slice_size)
+
+ reversed_slice_size = list(reversed(slice_size))
+ for module in self.children():
+ fn_recursive_set_attention_slice(module, reversed_slice_size)
+
+ def forward(
+ self,
+ sample: torch.Tensor,
+ timestep: torch.Tensor | float | int,
+ encoder_hidden_states: torch.Tensor,
+ class_labels: torch.Tensor | None = None,
+ timestep_cond: torch.Tensor | None = None,
+ attention_mask: torch.Tensor | None = None,
+ cross_attention_kwargs: dict[str, Any] | None = None,
+ encoder_attention_mask: torch.Tensor | None = None,
+ return_dict: bool = True,
+ encoder_hidden_states_1: torch.Tensor | None = None,
+ encoder_attention_mask_1: torch.Tensor | None = None,
+ ) -> UNet2DConditionOutput | tuple:
+ r"""
+ The [`AudioLDM2UNet2DConditionModel`] forward method.
+
+ Args:
+ sample (`torch.Tensor`):
+ The noisy input tensor with the following shape `(batch, channel, height, width)`.
+ timestep (`torch.Tensor` or `float` or `int`): The number of timesteps to denoise an input.
+ encoder_hidden_states (`torch.Tensor`):
+ The encoder hidden states with shape `(batch, sequence_length, feature_dim)`.
+ class_labels (`torch.Tensor`, *optional*, defaults to `None`):
+ Optional class labels for conditioning. Their embeddings will be summed with the timestep embeddings.
+ timestep_cond (`torch.Tensor`, *optional*, defaults to `None`):
+ Conditional embeddings for timestep. If provided, the embeddings will be summed with the samples passed
+ through the `self.time_embedding` layer to obtain the timestep embeddings.
+ attention_mask (`torch.Tensor`, *optional*, defaults to `None`):
+ An attention mask of shape `(batch, key_tokens)` is applied to `encoder_hidden_states`. If `1` the mask
+ is kept, otherwise if `0` it is discarded. Mask will be converted into a bias, which adds large
+ negative values to the attention scores corresponding to "discard" tokens.
+ encoder_attention_mask (`torch.Tensor`):
+ A cross-attention mask of shape `(batch, sequence_length)` is applied to `encoder_hidden_states`. If
+ `True` the mask is kept, otherwise if `False` it is discarded. Mask will be converted into a bias,
+ which adds large negative values to the attention scores corresponding to "discard" tokens.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] instead of a plain
+ tuple.
+ cross_attention_kwargs (`dict`, *optional*):
+ A kwargs dictionary that if specified is passed along to the [`AttnProcessor`].
+ encoder_hidden_states_1 (`torch.Tensor`, *optional*):
+ A second set of encoder hidden states with shape `(batch, sequence_length_2, feature_dim_2)`. Can be
+ used to condition the model on a different set of embeddings to `encoder_hidden_states`.
+ encoder_attention_mask_1 (`torch.Tensor`, *optional*):
+ A cross-attention mask of shape `(batch, sequence_length_2)` is applied to `encoder_hidden_states_1`.
+ If `True` the mask is kept, otherwise if `False` it is discarded. Mask will be converted into a bias,
+ which adds large negative values to the attention scores corresponding to "discard" tokens.
+
+ Returns:
+ [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] or `tuple`:
+ If `return_dict` is True, an [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] is returned,
+ otherwise a `tuple` is returned where the first element is the sample tensor.
+ """
+ # By default samples have to be AT least a multiple of the overall upsampling factor.
+ # The overall upsampling factor is equal to 2 ** (# num of upsampling layers).
+ # However, the upsampling interpolation output size can be forced to fit any upsampling size
+ # on the fly if necessary.
+ default_overall_up_factor = 2**self.num_upsamplers
+
+ # upsample size should be forwarded when sample is not a multiple of `default_overall_up_factor`
+ forward_upsample_size = False
+ upsample_size = None
+
+ if any(s % default_overall_up_factor != 0 for s in sample.shape[-2:]):
+ logger.info("Forward upsample size to force interpolation output size.")
+ forward_upsample_size = True
+
+ # ensure attention_mask is a bias, and give it a singleton query_tokens dimension
+ # expects mask of shape:
+ # [batch, key_tokens]
+ # adds singleton query_tokens dimension:
+ # [batch, 1, key_tokens]
+ # this helps to broadcast it as a bias over attention scores, which will be in one of the following shapes:
+ # [batch, heads, query_tokens, key_tokens] (e.g. torch sdp attn)
+ # [batch * heads, query_tokens, key_tokens] (e.g. xformers or classic attn)
+ if attention_mask is not None:
+ # assume that mask is expressed as:
+ # (1 = keep, 0 = discard)
+ # convert mask into a bias that can be added to attention scores:
+ # (keep = +0, discard = -10000.0)
+ attention_mask = (1 - attention_mask.to(sample.dtype)) * -10000.0
+ attention_mask = attention_mask.unsqueeze(1)
+
+ # convert encoder_attention_mask to a bias the same way we do for attention_mask
+ if encoder_attention_mask is not None:
+ encoder_attention_mask = (1 - encoder_attention_mask.to(sample.dtype)) * -10000.0
+ encoder_attention_mask = encoder_attention_mask.unsqueeze(1)
+
+ if encoder_attention_mask_1 is not None:
+ encoder_attention_mask_1 = (1 - encoder_attention_mask_1.to(sample.dtype)) * -10000.0
+ encoder_attention_mask_1 = encoder_attention_mask_1.unsqueeze(1)
+
+ # 1. time
+ timesteps = timestep
+ if not torch.is_tensor(timesteps):
+ # TODO: this requires sync between CPU and GPU. So try to pass timesteps as tensors if you can
+ # This would be a good case for the `match` statement (Python 3.10+)
+ is_mps = sample.device.type == "mps"
+ is_npu = sample.device.type == "npu"
+ if isinstance(timestep, float):
+ dtype = torch.float32 if (is_mps or is_npu) else torch.float64
+ else:
+ dtype = torch.int32 if (is_mps or is_npu) else torch.int64
+ timesteps = torch.tensor([timesteps], dtype=dtype, device=sample.device)
+ elif len(timesteps.shape) == 0:
+ timesteps = timesteps[None].to(sample.device)
+
+ # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
+ timesteps = timesteps.expand(sample.shape[0])
+
+ t_emb = self.time_proj(timesteps)
+
+ # `Timesteps` does not contain any weights and will always return f32 tensors
+ # but time_embedding might actually be running in fp16. so we need to cast here.
+ # there might be better ways to encapsulate this.
+ t_emb = t_emb.to(dtype=sample.dtype)
+
+ emb = self.time_embedding(t_emb, timestep_cond)
+ aug_emb = None
+
+ if self.class_embedding is not None:
+ if class_labels is None:
+ raise ValueError("class_labels should be provided when num_class_embeds > 0")
+
+ if self.config.class_embed_type == "timestep":
+ class_labels = self.time_proj(class_labels)
+
+ # `Timesteps` does not contain any weights and will always return f32 tensors
+ # there might be better ways to encapsulate this.
+ class_labels = class_labels.to(dtype=sample.dtype)
+
+ class_emb = self.class_embedding(class_labels).to(dtype=sample.dtype)
+
+ if self.config.class_embeddings_concat:
+ emb = torch.cat([emb, class_emb], dim=-1)
+ else:
+ emb = emb + class_emb
+
+ emb = emb + aug_emb if aug_emb is not None else emb
+
+ if self.time_embed_act is not None:
+ emb = self.time_embed_act(emb)
+
+ # 2. pre-process
+ sample = self.conv_in(sample)
+
+ # 3. down
+ down_block_res_samples = (sample,)
+ for downsample_block in self.down_blocks:
+ if hasattr(downsample_block, "has_cross_attention") and downsample_block.has_cross_attention:
+ sample, res_samples = downsample_block(
+ hidden_states=sample,
+ temb=emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ cross_attention_kwargs=cross_attention_kwargs,
+ encoder_attention_mask=encoder_attention_mask,
+ encoder_hidden_states_1=encoder_hidden_states_1,
+ encoder_attention_mask_1=encoder_attention_mask_1,
+ )
+ else:
+ sample, res_samples = downsample_block(hidden_states=sample, temb=emb)
+
+ down_block_res_samples += res_samples
+
+ # 4. mid
+ if self.mid_block is not None:
+ sample = self.mid_block(
+ sample,
+ emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ cross_attention_kwargs=cross_attention_kwargs,
+ encoder_attention_mask=encoder_attention_mask,
+ encoder_hidden_states_1=encoder_hidden_states_1,
+ encoder_attention_mask_1=encoder_attention_mask_1,
+ )
+
+ # 5. up
+ for i, upsample_block in enumerate(self.up_blocks):
+ is_final_block = i == len(self.up_blocks) - 1
+
+ res_samples = down_block_res_samples[-len(upsample_block.resnets) :]
+ down_block_res_samples = down_block_res_samples[: -len(upsample_block.resnets)]
+
+ # if we have not reached the final block and need to forward the
+ # upsample size, we do it here
+ if not is_final_block and forward_upsample_size:
+ upsample_size = down_block_res_samples[-1].shape[2:]
+
+ if hasattr(upsample_block, "has_cross_attention") and upsample_block.has_cross_attention:
+ sample = upsample_block(
+ hidden_states=sample,
+ temb=emb,
+ res_hidden_states_tuple=res_samples,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ upsample_size=upsample_size,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ encoder_hidden_states_1=encoder_hidden_states_1,
+ encoder_attention_mask_1=encoder_attention_mask_1,
+ )
+ else:
+ sample = upsample_block(
+ hidden_states=sample, temb=emb, res_hidden_states_tuple=res_samples, upsample_size=upsample_size
+ )
+
+ # 6. post-process
+ if self.conv_norm_out:
+ sample = self.conv_norm_out(sample)
+ sample = self.conv_act(sample)
+ sample = self.conv_out(sample)
+
+ if not return_dict:
+ return (sample,)
+
+ return UNet2DConditionOutput(sample=sample)
+
+
+def get_down_block(
+ down_block_type,
+ num_layers,
+ in_channels,
+ out_channels,
+ temb_channels,
+ add_downsample,
+ resnet_eps,
+ resnet_act_fn,
+ transformer_layers_per_block=1,
+ num_attention_heads=None,
+ resnet_groups=None,
+ cross_attention_dim=None,
+ downsample_padding=None,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ resnet_time_scale_shift="default",
+):
+ down_block_type = down_block_type[7:] if down_block_type.startswith("UNetRes") else down_block_type
+ if down_block_type == "DownBlock2D":
+ return DownBlock2D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ elif down_block_type == "CrossAttnDownBlock2D":
+ if cross_attention_dim is None:
+ raise ValueError("cross_attention_dim must be specified for CrossAttnDownBlock2D")
+ return CrossAttnDownBlock2D(
+ num_layers=num_layers,
+ transformer_layers_per_block=transformer_layers_per_block,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ cross_attention_dim=cross_attention_dim,
+ num_attention_heads=num_attention_heads,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ raise ValueError(f"{down_block_type} does not exist.")
+
+
+def get_up_block(
+ up_block_type,
+ num_layers,
+ in_channels,
+ out_channels,
+ prev_output_channel,
+ temb_channels,
+ add_upsample,
+ resnet_eps,
+ resnet_act_fn,
+ transformer_layers_per_block=1,
+ num_attention_heads=None,
+ resnet_groups=None,
+ cross_attention_dim=None,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ resnet_time_scale_shift="default",
+):
+ up_block_type = up_block_type[7:] if up_block_type.startswith("UNetRes") else up_block_type
+ if up_block_type == "UpBlock2D":
+ return UpBlock2D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ elif up_block_type == "CrossAttnUpBlock2D":
+ if cross_attention_dim is None:
+ raise ValueError("cross_attention_dim must be specified for CrossAttnUpBlock2D")
+ return CrossAttnUpBlock2D(
+ num_layers=num_layers,
+ transformer_layers_per_block=transformer_layers_per_block,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ cross_attention_dim=cross_attention_dim,
+ num_attention_heads=num_attention_heads,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ raise ValueError(f"{up_block_type} does not exist.")
+
+
+class CrossAttnDownBlock2D(nn.Module):
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads=1,
+ cross_attention_dim=1280,
+ output_scale_factor=1.0,
+ downsample_padding=1,
+ add_downsample=True,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+
+ if isinstance(cross_attention_dim, int):
+ cross_attention_dim = (cross_attention_dim,)
+ if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
+ raise ValueError(
+ "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
+ f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
+ )
+ self.cross_attention_dim = cross_attention_dim
+
+ for i in range(num_layers):
+ in_channels = in_channels if i == 0 else out_channels
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+ for j in range(len(cross_attention_dim)):
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=transformer_layers_per_block,
+ cross_attention_dim=cross_attention_dim[j],
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ double_self_attention=True if cross_attention_dim[j] is None else False,
+ )
+ )
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ Downsample2D(
+ out_channels, use_conv=True, out_channels=out_channels, padding=downsample_padding, name="op"
+ )
+ ]
+ )
+ else:
+ self.downsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ temb: torch.Tensor | None = None,
+ encoder_hidden_states: torch.Tensor | None = None,
+ attention_mask: torch.Tensor | None = None,
+ cross_attention_kwargs: dict[str, Any] | None = None,
+ encoder_attention_mask: torch.Tensor | None = None,
+ encoder_hidden_states_1: torch.Tensor | None = None,
+ encoder_attention_mask_1: torch.Tensor | None = None,
+ ) -> tuple[torch.Tensor, tuple[torch.Tensor, ...]]:
+ output_states = ()
+ num_layers = len(self.resnets)
+ num_attention_per_layer = len(self.attentions) // num_layers
+
+ encoder_hidden_states_1 = (
+ encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
+ )
+ encoder_attention_mask_1 = (
+ encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
+ )
+
+ for i in range(num_layers):
+ if torch.is_grad_enabled() and self.gradient_checkpointing:
+ hidden_states = self._gradient_checkpointing_func(self.resnets[i], hidden_states, temb)
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self._gradient_checkpointing_func(
+ self.attentions[i * num_attention_per_layer + idx],
+ hidden_states,
+ forward_encoder_hidden_states,
+ None, # timestep
+ None, # class_labels
+ cross_attention_kwargs,
+ attention_mask,
+ forward_encoder_attention_mask,
+ )[0]
+ else:
+ hidden_states = self.resnets[i](hidden_states, temb)
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self.attentions[i * num_attention_per_layer + idx](
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=forward_encoder_hidden_states,
+ encoder_attention_mask=forward_encoder_attention_mask,
+ return_dict=False,
+ )[0]
+
+ output_states = output_states + (hidden_states,)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states)
+
+ output_states = output_states + (hidden_states,)
+
+ return hidden_states, output_states
+
+
+class UNetMidBlock2DCrossAttn(nn.Module):
+ def __init__(
+ self,
+ in_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads=1,
+ output_scale_factor=1.0,
+ cross_attention_dim=1280,
+ use_linear_projection=False,
+ upcast_attention=False,
+ ):
+ super().__init__()
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+ resnet_groups = resnet_groups if resnet_groups is not None else min(in_channels // 4, 32)
+
+ if isinstance(cross_attention_dim, int):
+ cross_attention_dim = (cross_attention_dim,)
+ if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
+ raise ValueError(
+ "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
+ f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
+ )
+ self.cross_attention_dim = cross_attention_dim
+
+ # there is always at least one resnet
+ resnets = [
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ ]
+ attentions = []
+
+ for i in range(num_layers):
+ for j in range(len(cross_attention_dim)):
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ in_channels // num_attention_heads,
+ in_channels=in_channels,
+ num_layers=transformer_layers_per_block,
+ cross_attention_dim=cross_attention_dim[j],
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ double_self_attention=True if cross_attention_dim[j] is None else False,
+ )
+ )
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ temb: torch.Tensor | None = None,
+ encoder_hidden_states: torch.Tensor | None = None,
+ attention_mask: torch.Tensor | None = None,
+ cross_attention_kwargs: dict[str, Any] | None = None,
+ encoder_attention_mask: torch.Tensor | None = None,
+ encoder_hidden_states_1: torch.Tensor | None = None,
+ encoder_attention_mask_1: torch.Tensor | None = None,
+ ) -> torch.Tensor:
+ hidden_states = self.resnets[0](hidden_states, temb)
+ num_attention_per_layer = len(self.attentions) // (len(self.resnets) - 1)
+
+ encoder_hidden_states_1 = (
+ encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
+ )
+ encoder_attention_mask_1 = (
+ encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
+ )
+
+ for i in range(len(self.resnets[1:])):
+ if torch.is_grad_enabled() and self.gradient_checkpointing:
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self._gradient_checkpointing_func(
+ self.attentions[i * num_attention_per_layer + idx],
+ hidden_states,
+ forward_encoder_hidden_states,
+ None, # timestep
+ None, # class_labels
+ cross_attention_kwargs,
+ attention_mask,
+ forward_encoder_attention_mask,
+ )[0]
+ hidden_states = self._gradient_checkpointing_func(self.resnets[i + 1], hidden_states, temb)
+ else:
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self.attentions[i * num_attention_per_layer + idx](
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=forward_encoder_hidden_states,
+ encoder_attention_mask=forward_encoder_attention_mask,
+ return_dict=False,
+ )[0]
+
+ hidden_states = self.resnets[i + 1](hidden_states, temb)
+
+ return hidden_states
+
+
+class CrossAttnUpBlock2D(nn.Module):
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ prev_output_channel: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads=1,
+ cross_attention_dim=1280,
+ output_scale_factor=1.0,
+ add_upsample=True,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+
+ if isinstance(cross_attention_dim, int):
+ cross_attention_dim = (cross_attention_dim,)
+ if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
+ raise ValueError(
+ "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
+ f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
+ )
+ self.cross_attention_dim = cross_attention_dim
+
+ for i in range(num_layers):
+ res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
+ resnet_in_channels = prev_output_channel if i == 0 else out_channels
+
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=resnet_in_channels + res_skip_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+ for j in range(len(cross_attention_dim)):
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=transformer_layers_per_block,
+ cross_attention_dim=cross_attention_dim[j],
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ double_self_attention=True if cross_attention_dim[j] is None else False,
+ )
+ )
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList([Upsample2D(out_channels, use_conv=True, out_channels=out_channels)])
+ else:
+ self.upsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ res_hidden_states_tuple: tuple[torch.Tensor, ...],
+ temb: torch.Tensor | None = None,
+ encoder_hidden_states: torch.Tensor | None = None,
+ cross_attention_kwargs: dict[str, Any] | None = None,
+ upsample_size: int | None = None,
+ attention_mask: torch.Tensor | None = None,
+ encoder_attention_mask: torch.Tensor | None = None,
+ encoder_hidden_states_1: torch.Tensor | None = None,
+ encoder_attention_mask_1: torch.Tensor | None = None,
+ ) -> torch.Tensor:
+ num_layers = len(self.resnets)
+ num_attention_per_layer = len(self.attentions) // num_layers
+
+ encoder_hidden_states_1 = (
+ encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
+ )
+ encoder_attention_mask_1 = (
+ encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
+ )
+
+ for i in range(num_layers):
+ # pop res hidden states
+ res_hidden_states = res_hidden_states_tuple[-1]
+ res_hidden_states_tuple = res_hidden_states_tuple[:-1]
+ hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
+
+ if torch.is_grad_enabled() and self.gradient_checkpointing:
+ hidden_states = self._gradient_checkpointing_func(self.resnets[i], hidden_states, temb)
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self._gradient_checkpointing_func(
+ self.attentions[i * num_attention_per_layer + idx],
+ hidden_states,
+ forward_encoder_hidden_states,
+ None, # timestep
+ None, # class_labels
+ cross_attention_kwargs,
+ attention_mask,
+ forward_encoder_attention_mask,
+ )[0]
+ else:
+ hidden_states = self.resnets[i](hidden_states, temb)
+ for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
+ if cross_attention_dim is not None and idx <= 1:
+ forward_encoder_hidden_states = encoder_hidden_states
+ forward_encoder_attention_mask = encoder_attention_mask
+ elif cross_attention_dim is not None and idx > 1:
+ forward_encoder_hidden_states = encoder_hidden_states_1
+ forward_encoder_attention_mask = encoder_attention_mask_1
+ else:
+ forward_encoder_hidden_states = None
+ forward_encoder_attention_mask = None
+ hidden_states = self.attentions[i * num_attention_per_layer + idx](
+ hidden_states,
+ attention_mask=attention_mask,
+ encoder_hidden_states=forward_encoder_hidden_states,
+ encoder_attention_mask=forward_encoder_attention_mask,
+ return_dict=False,
+ )[0]
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(hidden_states, upsample_size)
+
+ return hidden_states
diff --git a/src/diffusers/modular_pipelines/echo/decoders.py b/src/diffusers/modular_pipelines/echo/decoders.py
index 846f1ec559d5..0bc695a658d8 100644
--- a/src/diffusers/modular_pipelines/echo/decoders.py
+++ b/src/diffusers/modular_pipelines/echo/decoders.py
@@ -18,7 +18,7 @@
from ...configuration_utils import FrozenDict
from ...models import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
-from ...pipelines.ltx2.vocoder import LTX2Vocoder
+from ...models.autoencoders import LTX2Vocoder
from ...utils.torch_utils import randn_tensor
from ...video_processor import VideoProcessor
from ..modular_pipeline import ModularPipelineBlocks, PipelineState
diff --git a/src/diffusers/modular_pipelines/ltx2/decoders.py b/src/diffusers/modular_pipelines/ltx2/decoders.py
index 34a2e9b6a74f..6cf31e9a1939 100644
--- a/src/diffusers/modular_pipelines/ltx2/decoders.py
+++ b/src/diffusers/modular_pipelines/ltx2/decoders.py
@@ -18,13 +18,7 @@
from ...configuration_utils import FrozenDict
from ...models import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2VideoDiffusionDecoderModel
-
-# NOTE (modular.md gotcha #1): `LTX2Vocoder` / `LTX2VocoderWithBWE` currently live under
-# `diffusers.pipelines.ltx2.vocoder`, and modular blocks must not import from `diffusers.pipelines.*`.
-# They are already `ModelMixin` / `ConfigMixin` model classes, so the clean fix is to relocate them to
-# `src/diffusers/models/` and re-export from `diffusers.models` before this lands. Imported from the
-# pipelines path here only so the draft is runnable; switch to the models path once moved.
-from ...pipelines.ltx2.vocoder import LTX2Vocoder
+from ...models.autoencoders import LTX2Vocoder
from ...utils import logging
from ...utils.torch_utils import randn_tensor
from ...video_processor import VideoProcessor
diff --git a/src/diffusers/pipelines/__init__.py b/src/diffusers/pipelines/__init__.py
index 7f0db0230b1d..33e8f812e721 100644
--- a/src/diffusers/pipelines/__init__.py
+++ b/src/diffusers/pipelines/__init__.py
@@ -113,6 +113,9 @@
"PIAPipeline",
"PaintByExamplePipeline",
"SemanticStableDiffusionPipeline",
+ "ShapEImg2ImgPipeline",
+ "ShapEPipeline",
+ "shap_e",
"StableDiffusionAttendAndExcitePipeline",
"StableDiffusionControlNetXSPipeline",
"StableDiffusionDiffEditPipeline",
@@ -394,7 +397,6 @@
"SanaWMLTX2Refiner",
"SanaWMPipelineOutput",
]
- _import_structure["shap_e"] = ["ShapEImg2ImgPipeline", "ShapEPipeline"]
_import_structure["stable_audio"] = [
"StableAudioProjectionModel",
"StableAudioPipeline",
@@ -658,6 +660,8 @@
PaintByExamplePipeline,
PIAPipeline,
SemanticStableDiffusionPipeline,
+ ShapEImg2ImgPipeline,
+ ShapEPipeline,
StableDiffusionAttendAndExcitePipeline,
StableDiffusionControlNetXSPipeline,
StableDiffusionDiffEditPipeline,
@@ -689,6 +693,7 @@
WuerstchenCombinedPipeline,
WuerstchenDecoderPipeline,
WuerstchenPriorPipeline,
+ shap_e,
)
from .diffusion_gemma import DiffusionGemmaPipeline, DiffusionGemmaPipelineOutput
from .dreamlite import (
@@ -872,7 +877,6 @@
SanaWMPipeline,
SanaWMPipelineOutput,
)
- from .shap_e import ShapEImg2ImgPipeline, ShapEPipeline
from .stable_audio import StableAudioPipeline, StableAudioProjectionModel
from .stable_audio_3 import (
StableAudio3AudioToAudioPipeline,
diff --git a/src/diffusers/pipelines/ace_step/modeling_ace_step.py b/src/diffusers/pipelines/ace_step/modeling_ace_step.py
index 199e97fc9169..6bafac420ea0 100644
--- a/src/diffusers/pipelines/ace_step/modeling_ace_step.py
+++ b/src/diffusers/pipelines/ace_step/modeling_ace_step.py
@@ -12,411 +12,16 @@
# See the License for the specific language governing permissions and
# limitations under the License.
-"""Pipeline-specific models for ACE-Step 1.5.
-
-Holds the audio tokenizer / detokenizer used by cover conditioning. The condition encoder now lives in
-``diffusers/models/condition_embedders/condition_embedder_ace_step.py``; the names below are kept as deprecated aliases
-for backward compatibility.
-"""
-
-from typing import Optional, Tuple
-
-import torch
-import torch.nn as nn
-import torch.nn.functional as F
-
-from ...configuration_utils import ConfigMixin, register_to_config
+from ...models.autoencoders.audio_tokenizer_ace_step import (
+ AceStepAudioTokenDetokenizer as _AceStepAudioTokenDetokenizer,
+)
+from ...models.autoencoders.audio_tokenizer_ace_step import AceStepAudioTokenizer as _AceStepAudioTokenizer
from ...models.condition_embedders.condition_embedder_ace_step import (
AceStepConditionEncoder as _AceStepConditionEncoder,
)
-from ...models.condition_embedders.condition_embedder_ace_step import AceStepEncoderLayer
from ...models.condition_embedders.condition_embedder_ace_step import AceStepLyricEncoder as _AceStepLyricEncoder
from ...models.condition_embedders.condition_embedder_ace_step import AceStepTimbreEncoder as _AceStepTimbreEncoder
-from ...models.modeling_utils import ModelMixin
-from ...models.normalization import RMSNorm
-from ...models.transformers.ace_step_transformer import (
- _ace_step_rotary_freqs,
- _create_4d_mask,
- _is_flash_attention_backend,
-)
-from ...utils import deprecate, logging
-
-
-logger = logging.get_logger(__name__) # pylint: disable=invalid-name
-
-
-# --------------------------------------------------------------------------- #
-# audio tokenizer / detokenizer #
-# --------------------------------------------------------------------------- #
-
-
-class _AceStepResidualFSQ(nn.Module):
- """Minimal ResidualFSQ compatible with ACE-Step's saved tokenizer weights."""
-
- def __init__(
- self,
- dim: int = 2048,
- levels: Optional[list] = None,
- num_quantizers: int = 1,
- ):
- super().__init__()
-
- if levels is None:
- levels = [8, 8, 8, 5, 5, 5]
-
- self.levels = levels
- self.num_quantizers = num_quantizers
- self.codebook_dim = len(levels)
-
- self.project_in = nn.Linear(dim, self.codebook_dim)
- self.project_out = nn.Linear(self.codebook_dim, dim)
-
- levels_tensor = torch.tensor(levels, dtype=torch.long)
- basis = torch.cumprod(torch.tensor([1] + levels[:-1], dtype=torch.long), dim=0)
- scales = torch.stack([levels_tensor.float() ** -i for i in range(num_quantizers)])
- self.register_buffer("_levels", levels_tensor, persistent=False)
- self.register_buffer("_basis", basis, persistent=False)
- self.register_buffer("scales", scales, persistent=False)
-
- @property
- def codebook_size(self) -> int:
- return int(torch.prod(self._levels).item())
-
- def _indices_to_codes(self, indices: torch.Tensor) -> torch.Tensor:
- levels = self._levels.to(device=indices.device)
- basis = self._basis.to(device=indices.device)
- level_indices = (indices.long().unsqueeze(-1) // basis) % levels
- scale = 2.0 / (levels.to(dtype=torch.float32) - 1.0)
- return level_indices.to(dtype=torch.float32) * scale - 1.0
-
- def _codes_to_indices(self, codes: torch.Tensor) -> torch.Tensor:
- levels = self._levels.to(device=codes.device, dtype=codes.dtype)
- basis = self._basis.to(device=codes.device, dtype=codes.dtype)
- level_indices = (codes + 1.0) / (2.0 / (levels - 1.0))
- return (level_indices * basis).sum(dim=-1).round().to(torch.long)
-
- def _quantize(self, x: torch.Tensor) -> torch.Tensor:
- levels = self._levels.to(device=x.device, dtype=x.dtype)
- levels_minus_one = levels - 1.0
- step = 2.0 / levels_minus_one
- bracket = levels_minus_one * (x.clamp(-1.0, 1.0) + 1.0) / 2.0 + 0.5
- return step * torch.floor(bracket) - 1.0
-
- def get_codes_from_indices(self, indices: torch.Tensor) -> torch.Tensor:
- if indices.ndim == 2:
- indices = indices.unsqueeze(-1)
- if indices.shape[-1] != self.num_quantizers:
- raise ValueError(
- f"Expected audio code indices with last dimension {self.num_quantizers}, got {indices.shape[-1]}."
- )
-
- codes = []
- for quantizer_idx in range(self.num_quantizers):
- code = self._indices_to_codes(indices[..., quantizer_idx])
- scale = self.scales[quantizer_idx].to(device=code.device, dtype=code.dtype)
- codes.append(code * scale)
- return torch.stack(codes, dim=0)
-
- def get_output_from_indices(self, indices: torch.Tensor) -> torch.Tensor:
- codes = self.get_codes_from_indices(indices).sum(dim=0)
- weight = self.project_out.weight.float()
- bias = self.project_out.bias.float() if self.project_out.bias is not None else None
- output = F.linear(codes.float(), weight, bias)
- return output.to(dtype=self.project_out.weight.dtype)
-
- def forward(self, hidden_states: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor]:
- input_dtype = hidden_states.dtype
- weight = self.project_in.weight.float()
- bias = self.project_in.bias.float() if self.project_in.bias is not None else None
- hidden_states = F.linear(hidden_states.float(), weight, bias)
-
- levels = self._levels.to(device=hidden_states.device, dtype=hidden_states.dtype)
- soft_clamp = 1.0 + (1.0 / (levels - 1.0))
- hidden_states = (hidden_states / soft_clamp).tanh() * soft_clamp
-
- quantized_out = torch.zeros_like(hidden_states)
- residual = hidden_states
- all_indices = []
- for scale in self.scales.to(device=hidden_states.device, dtype=hidden_states.dtype):
- quantized = self._quantize(residual / scale) * scale
- residual = residual - quantized.detach()
- quantized_out = quantized_out + quantized
- all_indices.append(self._codes_to_indices(quantized / scale))
-
- weight = self.project_out.weight.float()
- bias = self.project_out.bias.float() if self.project_out.bias is not None else None
- quantized_out = F.linear(quantized_out.float(), weight, bias).to(dtype=input_dtype)
- all_indices = torch.stack(all_indices, dim=-1)
- return quantized_out, all_indices
-
-
-class AceStepAttentionPooler(nn.Module):
- """Attention pooler used by the ACE-Step audio tokenizer."""
-
- def __init__(
- self,
- hidden_size: int = 2048,
- intermediate_size: int = 6144,
- num_attention_pooler_hidden_layers: int = 2,
- num_attention_heads: int = 16,
- num_key_value_heads: int = 8,
- head_dim: int = 128,
- rope_theta: float = 1000000.0,
- attention_bias: bool = False,
- attention_dropout: float = 0.0,
- rms_norm_eps: float = 1e-6,
- sliding_window: int = 128,
- layer_types: list = None,
- ):
- super().__init__()
-
- if layer_types is None:
- layer_types = [
- "sliding_attention" if bool((i + 1) % 2) else "full_attention"
- for i in range(num_attention_pooler_hidden_layers)
- ]
-
- self.embed_tokens = nn.Linear(hidden_size, hidden_size)
- self.norm = RMSNorm(hidden_size, eps=rms_norm_eps)
- self.special_token = nn.Parameter(torch.randn(1, 1, hidden_size) * 0.02)
- self.head_dim = head_dim
- self.rope_theta = rope_theta
- self.sliding_window = sliding_window
- self.layers = nn.ModuleList(
- [
- AceStepEncoderLayer(
- hidden_size=hidden_size,
- num_attention_heads=num_attention_heads,
- num_key_value_heads=num_key_value_heads,
- head_dim=head_dim,
- intermediate_size=intermediate_size,
- attention_bias=attention_bias,
- attention_dropout=attention_dropout,
- rms_norm_eps=rms_norm_eps,
- sliding_window=sliding_window if layer_types[i] == "sliding_attention" else None,
- )
- for i in range(num_attention_pooler_hidden_layers)
- ]
- )
- self._layer_types = layer_types
-
- def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
- batch_size, num_patches, patch_size, _ = hidden_states.shape
- hidden_states = self.embed_tokens(hidden_states)
- special_token = self.special_token.to(device=hidden_states.device, dtype=hidden_states.dtype)
- special_token = special_token.expand(batch_size, num_patches, -1, -1)
- hidden_states = torch.cat([special_token, hidden_states], dim=2)
- hidden_states = hidden_states.reshape(batch_size * num_patches, patch_size + 1, -1)
-
- seq_len = hidden_states.shape[1]
- dtype = hidden_states.dtype
- device = hidden_states.device
- position_embeddings = _ace_step_rotary_freqs(seq_len, self.head_dim, self.rope_theta, device, dtype)
- sliding_attn_mask = None
- if not _is_flash_attention_backend(self.layers[0].self_attn.processor):
- sliding_attn_mask = _create_4d_mask(
- seq_len=seq_len,
- dtype=dtype,
- device=device,
- attention_mask=None,
- sliding_window=self.sliding_window,
- is_sliding_window=True,
- is_causal=False,
- )
-
- for i, layer_module in enumerate(self.layers):
- mask = sliding_attn_mask if self._layer_types[i] == "sliding_attention" else None
- hidden_states = layer_module(
- hidden_states=hidden_states,
- position_embeddings=position_embeddings,
- attention_mask=mask,
- )
-
- hidden_states = self.norm(hidden_states)
- hidden_states = hidden_states[:, 0, :]
- return hidden_states.reshape(batch_size, num_patches, -1)
-
-
-class AceStepAudioTokenDetokenizer(ModelMixin, ConfigMixin):
- """Expands ACE-Step 5 Hz audio tokens back to 25 Hz acoustic conditioning."""
-
- _supports_gradient_checkpointing = True
-
- @register_to_config
- def __init__(
- self,
- hidden_size: int = 2048,
- intermediate_size: int = 6144,
- audio_acoustic_hidden_dim: int = 64,
- pool_window_size: int = 5,
- num_attention_pooler_hidden_layers: int = 2,
- num_attention_heads: int = 16,
- num_key_value_heads: int = 8,
- head_dim: int = 128,
- rope_theta: float = 1000000.0,
- attention_bias: bool = False,
- attention_dropout: float = 0.0,
- rms_norm_eps: float = 1e-6,
- sliding_window: int = 128,
- layer_types: list = None,
- ):
- super().__init__()
-
- if layer_types is None:
- layer_types = [
- "sliding_attention" if bool((i + 1) % 2) else "full_attention"
- for i in range(num_attention_pooler_hidden_layers)
- ]
-
- self.embed_tokens = nn.Linear(hidden_size, hidden_size)
- self.norm = RMSNorm(hidden_size, eps=rms_norm_eps)
- self.special_tokens = nn.Parameter(torch.randn(1, pool_window_size, hidden_size) * 0.02)
- self.proj_out = nn.Linear(hidden_size, audio_acoustic_hidden_dim)
- self.head_dim = head_dim
- self.rope_theta = rope_theta
- self.sliding_window = sliding_window
- self.pool_window_size = pool_window_size
- self.layers = nn.ModuleList(
- [
- AceStepEncoderLayer(
- hidden_size=hidden_size,
- num_attention_heads=num_attention_heads,
- num_key_value_heads=num_key_value_heads,
- head_dim=head_dim,
- intermediate_size=intermediate_size,
- attention_bias=attention_bias,
- attention_dropout=attention_dropout,
- rms_norm_eps=rms_norm_eps,
- sliding_window=sliding_window if layer_types[i] == "sliding_attention" else None,
- )
- for i in range(num_attention_pooler_hidden_layers)
- ]
- )
- self._layer_types = layer_types
- self.gradient_checkpointing = False
-
- def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
- batch_size, num_tokens, _ = hidden_states.shape
- hidden_states = self.embed_tokens(hidden_states)
- hidden_states = hidden_states.unsqueeze(2).expand(-1, -1, self.pool_window_size, -1)
- special_tokens = self.special_tokens.to(device=hidden_states.device, dtype=hidden_states.dtype)
- hidden_states = hidden_states + special_tokens.unsqueeze(0)
- hidden_states = hidden_states.reshape(batch_size * num_tokens, self.pool_window_size, -1)
-
- seq_len = hidden_states.shape[1]
- dtype = hidden_states.dtype
- device = hidden_states.device
- position_embeddings = _ace_step_rotary_freqs(seq_len, self.head_dim, self.rope_theta, device, dtype)
- sliding_attn_mask = None
- if not _is_flash_attention_backend(self.layers[0].self_attn.processor):
- sliding_attn_mask = _create_4d_mask(
- seq_len=seq_len,
- dtype=dtype,
- device=device,
- attention_mask=None,
- sliding_window=self.sliding_window,
- is_sliding_window=True,
- is_causal=False,
- )
-
- for i, layer_module in enumerate(self.layers):
- mask = sliding_attn_mask if self._layer_types[i] == "sliding_attention" else None
- if torch.is_grad_enabled() and self.gradient_checkpointing:
- hidden_states = self._gradient_checkpointing_func(
- layer_module, hidden_states, position_embeddings, mask
- )
- else:
- hidden_states = layer_module(
- hidden_states=hidden_states,
- position_embeddings=position_embeddings,
- attention_mask=mask,
- )
-
- hidden_states = self.norm(hidden_states)
- hidden_states = self.proj_out(hidden_states)
- return hidden_states.reshape(batch_size, num_tokens * self.pool_window_size, -1)
-
-
-class AceStepAudioTokenizer(ModelMixin, ConfigMixin):
- """Converts 25 Hz acoustic latents to ACE-Step 5 Hz audio tokens."""
-
- _supports_gradient_checkpointing = True
-
- @register_to_config
- def __init__(
- self,
- hidden_size: int = 2048,
- intermediate_size: int = 6144,
- audio_acoustic_hidden_dim: int = 64,
- pool_window_size: int = 5,
- fsq_dim: int = 2048,
- fsq_input_levels: list = None,
- fsq_input_num_quantizers: int = 1,
- num_attention_pooler_hidden_layers: int = 2,
- num_attention_heads: int = 16,
- num_key_value_heads: int = 8,
- head_dim: int = 128,
- rope_theta: float = 1000000.0,
- attention_bias: bool = False,
- attention_dropout: float = 0.0,
- rms_norm_eps: float = 1e-6,
- sliding_window: int = 128,
- layer_types: list = None,
- ):
- super().__init__()
-
- if fsq_input_levels is None:
- fsq_input_levels = [8, 8, 8, 5, 5, 5]
-
- self.audio_acoustic_proj = nn.Linear(audio_acoustic_hidden_dim, hidden_size)
- self.attention_pooler = AceStepAttentionPooler(
- hidden_size=hidden_size,
- intermediate_size=intermediate_size,
- num_attention_pooler_hidden_layers=num_attention_pooler_hidden_layers,
- num_attention_heads=num_attention_heads,
- num_key_value_heads=num_key_value_heads,
- head_dim=head_dim,
- rope_theta=rope_theta,
- attention_bias=attention_bias,
- attention_dropout=attention_dropout,
- rms_norm_eps=rms_norm_eps,
- sliding_window=sliding_window,
- layer_types=layer_types,
- )
- self.quantizer = _AceStepResidualFSQ(
- dim=fsq_dim,
- levels=fsq_input_levels,
- num_quantizers=fsq_input_num_quantizers,
- )
- self.pool_window_size = pool_window_size
-
- def forward(self, hidden_states: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor]:
- input_dtype = hidden_states.dtype
- hidden_states = self.audio_acoustic_proj(hidden_states)
- hidden_states = self.attention_pooler(hidden_states)
- quantized, indices = self.quantizer(hidden_states)
- return quantized.to(dtype=input_dtype), indices
-
- def tokenize(
- self,
- hidden_states: torch.Tensor,
- silence_latent: Optional[torch.Tensor] = None,
- ) -> Tuple[torch.Tensor, torch.Tensor]:
- batch_size, latent_length, acoustic_dim = hidden_states.shape
- pad_len = (-latent_length) % self.pool_window_size
- if pad_len:
- if silence_latent is not None and silence_latent.shape[-1] == acoustic_dim:
- pad = silence_latent[:, :pad_len, :].to(device=hidden_states.device, dtype=hidden_states.dtype)
- pad = pad.expand(batch_size, -1, -1)
- else:
- pad = torch.zeros(
- batch_size, pad_len, acoustic_dim, device=hidden_states.device, dtype=hidden_states.dtype
- )
- hidden_states = torch.cat([hidden_states, pad], dim=1)
-
- num_patches = hidden_states.shape[1] // self.pool_window_size
- hidden_states = hidden_states.reshape(batch_size, num_patches, self.pool_window_size, acoustic_dim)
- return self(hidden_states)
+from ...utils import deprecate
# Deprecated aliases kept for backward compatibility. The warning is raised from `__new__` rather than `__init__` so
@@ -452,3 +57,25 @@ def __new__(cls, *args, **kwargs):
"Import it with `from diffusers import AceStepConditionEncoder` instead.",
)
return super().__new__(cls)
+
+
+class AceStepAudioTokenizer(_AceStepAudioTokenizer):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "AceStepAudioTokenizer",
+ "1.0.0",
+ "Importing `AceStepAudioTokenizer` from `diffusers.pipelines.ace_step.modeling_ace_step` is deprecated. "
+ "Import it with `from diffusers import AceStepAudioTokenizer` instead.",
+ )
+ return super().__new__(cls)
+
+
+class AceStepAudioTokenDetokenizer(_AceStepAudioTokenDetokenizer):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "AceStepAudioTokenDetokenizer",
+ "1.0.0",
+ "Importing `AceStepAudioTokenDetokenizer` from `diffusers.pipelines.ace_step.modeling_ace_step` is deprecated. "
+ "Import it with `from diffusers import AceStepAudioTokenDetokenizer` instead.",
+ )
+ return super().__new__(cls)
diff --git a/src/diffusers/pipelines/ace_step/pipeline_ace_step.py b/src/diffusers/pipelines/ace_step/pipeline_ace_step.py
index 2b27db5df98a..29f437e58443 100644
--- a/src/diffusers/pipelines/ace_step/pipeline_ace_step.py
+++ b/src/diffusers/pipelines/ace_step/pipeline_ace_step.py
@@ -22,13 +22,13 @@
from ...guiders.adaptive_projected_guidance import MomentumBuffer, normalized_guidance
from ...loaders import AceStepLoraLoaderMixin
from ...models import AutoencoderOobleck
+from ...models.autoencoders import AceStepAudioTokenDetokenizer, AceStepAudioTokenizer
from ...models.condition_embedders import AceStepConditionEncoder
from ...models.transformers.ace_step_transformer import AceStepTransformer1DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
from ...utils import logging, replace_example_docstring
from ...utils.torch_utils import randn_tensor
from ..pipeline_utils import AudioPipelineOutput, DiffusionPipeline
-from .modeling_ace_step import AceStepAudioTokenDetokenizer, AceStepAudioTokenizer
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
diff --git a/src/diffusers/pipelines/audioldm2/modeling_audioldm2.py b/src/diffusers/pipelines/audioldm2/modeling_audioldm2.py
index 6b918cadf800..a9538c6bd00b 100644
--- a/src/diffusers/pipelines/audioldm2/modeling_audioldm2.py
+++ b/src/diffusers/pipelines/audioldm2/modeling_audioldm2.py
@@ -12,1285 +12,11 @@
# See the License for the specific language governing permissions and
# limitations under the License.
-from typing import Any
-
-import torch
-import torch.nn as nn
-
-from ...configuration_utils import ConfigMixin, register_to_config
-from ...loaders import UNet2DConditionLoadersMixin
-from ...models.activations import get_activation
-from ...models.attention import AttentionMixin
-from ...models.attention_processor import (
- ADDED_KV_ATTENTION_PROCESSORS,
- CROSS_ATTENTION_PROCESSORS,
- AttnAddedKVProcessor,
- AttnProcessor,
-)
from ...models.condition_embedders.condition_embedder_audioldm2 import (
AudioLDM2ProjectionModel as _AudioLDM2ProjectionModel,
)
-from ...models.embeddings import TimestepEmbedding, Timesteps
-from ...models.modeling_utils import ModelMixin
-from ...models.resnet import Downsample2D, ResnetBlock2D, Upsample2D
-from ...models.transformers.transformer_2d import Transformer2DModel
-from ...models.unets.unet_2d_blocks import DownBlock2D, UpBlock2D
-from ...models.unets.unet_2d_condition import UNet2DConditionOutput
-from ...utils import deprecate, logging
-
-
-logger = logging.get_logger(__name__) # pylint: disable=invalid-name
-
-
-class AudioLDM2UNet2DConditionModel(ModelMixin, AttentionMixin, ConfigMixin, UNet2DConditionLoadersMixin):
- r"""
- A conditional 2D UNet model that takes a noisy sample, conditional state, and a timestep and returns a sample
- shaped output. Compared to the vanilla [`UNet2DConditionModel`], this variant optionally includes an additional
- self-attention layer in each Transformer block, as well as multiple cross-attention layers. It also allows for up
- to two cross-attention embeddings, `encoder_hidden_states` and `encoder_hidden_states_1`.
-
- This model inherits from [`ModelMixin`]. Check the superclass documentation for it's generic methods implemented
- for all models (such as downloading or saving).
-
- Parameters:
- sample_size (`int` or `tuple[int, int]`, *optional*, defaults to `None`):
- Height and width of input/output sample.
- in_channels (`int`, *optional*, defaults to 4): Number of channels in the input sample.
- out_channels (`int`, *optional*, defaults to 4): Number of channels in the output.
- flip_sin_to_cos (`bool`, *optional*, defaults to `False`):
- Whether to flip the sin to cos in the time embedding.
- freq_shift (`int`, *optional*, defaults to 0): The frequency shift to apply to the time embedding.
- down_block_types (`tuple[str]`, *optional*, defaults to `("CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "DownBlock2D")`):
- The tuple of downsample blocks to use.
- mid_block_type (`str`, *optional*, defaults to `"UNetMidBlock2DCrossAttn"`):
- Block type for middle of UNet, it can only be `UNetMidBlock2DCrossAttn` for AudioLDM2.
- up_block_types (`tuple[str]`, *optional*, defaults to `("UpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D")`):
- The tuple of upsample blocks to use.
- only_cross_attention (`bool` or `tuple[bool]`, *optional*, default to `False`):
- Whether to include self-attention in the basic transformer blocks, see
- [`~models.attention.BasicTransformerBlock`].
- block_out_channels (`tuple[int]`, *optional*, defaults to `(320, 640, 1280, 1280)`):
- The tuple of output channels for each block.
- layers_per_block (`int`, *optional*, defaults to 2): The number of layers per block.
- downsample_padding (`int`, *optional*, defaults to 1): The padding to use for the downsampling convolution.
- mid_block_scale_factor (`float`, *optional*, defaults to 1.0): The scale factor to use for the mid block.
- act_fn (`str`, *optional*, defaults to `"silu"`): The activation function to use.
- norm_num_groups (`int`, *optional*, defaults to 32): The number of groups to use for the normalization.
- If `None`, normalization and activation layers is skipped in post-processing.
- norm_eps (`float`, *optional*, defaults to 1e-5): The epsilon to use for the normalization.
- cross_attention_dim (`int` or `tuple[int]`, *optional*, defaults to 1280):
- The dimension of the cross attention features.
- transformer_layers_per_block (`int` or `tuple[int]`, *optional*, defaults to 1):
- The number of transformer blocks of type [`~models.attention.BasicTransformerBlock`]. Only relevant for
- [`~models.unet_2d_blocks.CrossAttnDownBlock2D`], [`~models.unet_2d_blocks.CrossAttnUpBlock2D`],
- [`~models.unet_2d_blocks.UNetMidBlock2DCrossAttn`].
- attention_head_dim (`int`, *optional*, defaults to 8): The dimension of the attention heads.
- num_attention_heads (`int`, *optional*):
- The number of attention heads. If not defined, defaults to `attention_head_dim`
- resnet_time_scale_shift (`str`, *optional*, defaults to `"default"`): Time scale shift config
- for ResNet blocks (see [`~models.resnet.ResnetBlock2D`]). Choose from `default` or `scale_shift`.
- class_embed_type (`str`, *optional*, defaults to `None`):
- The type of class embedding to use which is ultimately summed with the time embeddings. Choose from `None`,
- `"timestep"`, `"identity"`, `"projection"`, or `"simple_projection"`.
- num_class_embeds (`int`, *optional*, defaults to `None`):
- Input dimension of the learnable embedding matrix to be projected to `time_embed_dim`, when performing
- class conditioning with `class_embed_type` equal to `None`.
- time_embedding_type (`str`, *optional*, defaults to `positional`):
- The type of position embedding to use for timesteps. Choose from `positional` or `fourier`.
- time_embedding_dim (`int`, *optional*, defaults to `None`):
- An optional override for the dimension of the projected time embedding.
- time_embedding_act_fn (`str`, *optional*, defaults to `None`):
- Optional activation function to use only once on the time embeddings before they are passed to the rest of
- the UNet. Choose from `silu`, `mish`, `gelu`, and `swish`.
- timestep_post_act (`str`, *optional*, defaults to `None`):
- The second activation function to use in timestep embedding. Choose from `silu`, `mish` and `gelu`.
- time_cond_proj_dim (`int`, *optional*, defaults to `None`):
- The dimension of `cond_proj` layer in the timestep embedding.
- conv_in_kernel (`int`, *optional*, default to `3`): The kernel size of `conv_in` layer.
- conv_out_kernel (`int`, *optional*, default to `3`): The kernel size of `conv_out` layer.
- projection_class_embeddings_input_dim (`int`, *optional*): The dimension of the `class_labels` input when
- `class_embed_type="projection"`. Required when `class_embed_type="projection"`.
- class_embeddings_concat (`bool`, *optional*, defaults to `False`): Whether to concatenate the time
- embeddings with the class embeddings.
- """
-
- _supports_gradient_checkpointing = True
-
- @register_to_config
- def __init__(
- self,
- sample_size: int | None = None,
- in_channels: int = 4,
- out_channels: int = 4,
- flip_sin_to_cos: bool = True,
- freq_shift: int = 0,
- down_block_types: tuple[str] = (
- "CrossAttnDownBlock2D",
- "DownBlock2D",
- ),
- mid_block_type: str = "UNetMidBlock2DCrossAttn",
- up_block_types: tuple[str] = ("UpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D"),
- only_cross_attention: bool | tuple[bool] = False,
- block_out_channels: tuple[int] = (320, 640, 1280, 1280),
- layers_per_block: int | tuple[int] = 2,
- downsample_padding: int = 1,
- mid_block_scale_factor: float = 1,
- act_fn: str = "silu",
- norm_num_groups: int | None = 32,
- norm_eps: float = 1e-5,
- cross_attention_dim: int | tuple[int] = 1280,
- transformer_layers_per_block: int | tuple[int] = 1,
- attention_head_dim: int | tuple[int] = 8,
- num_attention_heads: int | tuple[int] | None = None,
- use_linear_projection: bool = False,
- class_embed_type: str | None = None,
- num_class_embeds: int | None = None,
- upcast_attention: bool = False,
- resnet_time_scale_shift: str = "default",
- time_embedding_type: str = "positional",
- time_embedding_dim: int | None = None,
- time_embedding_act_fn: str | None = None,
- timestep_post_act: str | None = None,
- time_cond_proj_dim: int | None = None,
- conv_in_kernel: int = 3,
- conv_out_kernel: int = 3,
- projection_class_embeddings_input_dim: int | None = None,
- class_embeddings_concat: bool = False,
- ):
- super().__init__()
-
- self.sample_size = sample_size
-
- if num_attention_heads is not None:
- raise ValueError(
- "At the moment it is not possible to define the number of attention heads via `num_attention_heads` because of a naming issue as described in https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131. Passing `num_attention_heads` will only be supported in diffusers v0.19."
- )
-
- # If `num_attention_heads` is not defined (which is the case for most models)
- # it will default to `attention_head_dim`. This looks weird upon first reading it and it is.
- # The reason for this behavior is to correct for incorrectly named variables that were introduced
- # when this library was created. The incorrect naming was only discovered much later in https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131
- # Changing `attention_head_dim` to `num_attention_heads` for 40,000+ configurations is too backwards breaking
- # which is why we correct for the naming here.
- num_attention_heads = num_attention_heads or attention_head_dim
-
- # Check inputs
- if len(down_block_types) != len(up_block_types):
- raise ValueError(
- f"Must provide the same number of `down_block_types` as `up_block_types`. `down_block_types`: {down_block_types}. `up_block_types`: {up_block_types}."
- )
-
- if len(block_out_channels) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `block_out_channels` as `down_block_types`. `block_out_channels`: {block_out_channels}. `down_block_types`: {down_block_types}."
- )
-
- if not isinstance(only_cross_attention, bool) and len(only_cross_attention) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `only_cross_attention` as `down_block_types`. `only_cross_attention`: {only_cross_attention}. `down_block_types`: {down_block_types}."
- )
-
- if not isinstance(num_attention_heads, int) and len(num_attention_heads) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `num_attention_heads` as `down_block_types`. `num_attention_heads`: {num_attention_heads}. `down_block_types`: {down_block_types}."
- )
-
- if not isinstance(attention_head_dim, int) and len(attention_head_dim) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `attention_head_dim` as `down_block_types`. `attention_head_dim`: {attention_head_dim}. `down_block_types`: {down_block_types}."
- )
-
- if isinstance(cross_attention_dim, list) and len(cross_attention_dim) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `cross_attention_dim` as `down_block_types`. `cross_attention_dim`: {cross_attention_dim}. `down_block_types`: {down_block_types}."
- )
-
- if not isinstance(layers_per_block, int) and len(layers_per_block) != len(down_block_types):
- raise ValueError(
- f"Must provide the same number of `layers_per_block` as `down_block_types`. `layers_per_block`: {layers_per_block}. `down_block_types`: {down_block_types}."
- )
-
- # input
- conv_in_padding = (conv_in_kernel - 1) // 2
- self.conv_in = nn.Conv2d(
- in_channels, block_out_channels[0], kernel_size=conv_in_kernel, padding=conv_in_padding
- )
-
- # time
- if time_embedding_type == "positional":
- time_embed_dim = time_embedding_dim or block_out_channels[0] * 4
-
- self.time_proj = Timesteps(block_out_channels[0], flip_sin_to_cos, freq_shift)
- timestep_input_dim = block_out_channels[0]
- else:
- raise ValueError(f"{time_embedding_type} does not exist. Please make sure to use `positional`.")
-
- self.time_embedding = TimestepEmbedding(
- timestep_input_dim,
- time_embed_dim,
- act_fn=act_fn,
- post_act_fn=timestep_post_act,
- cond_proj_dim=time_cond_proj_dim,
- )
-
- # class embedding
- if class_embed_type is None and num_class_embeds is not None:
- self.class_embedding = nn.Embedding(num_class_embeds, time_embed_dim)
- elif class_embed_type == "timestep":
- self.class_embedding = TimestepEmbedding(timestep_input_dim, time_embed_dim, act_fn=act_fn)
- elif class_embed_type == "identity":
- self.class_embedding = nn.Identity(time_embed_dim, time_embed_dim)
- elif class_embed_type == "projection":
- if projection_class_embeddings_input_dim is None:
- raise ValueError(
- "`class_embed_type`: 'projection' requires `projection_class_embeddings_input_dim` be set"
- )
- # The projection `class_embed_type` is the same as the timestep `class_embed_type` except
- # 1. the `class_labels` inputs are not first converted to sinusoidal embeddings
- # 2. it projects from an arbitrary input dimension.
- #
- # Note that `TimestepEmbedding` is quite general, being mainly linear layers and activations.
- # When used for embedding actual timesteps, the timesteps are first converted to sinusoidal embeddings.
- # As a result, `TimestepEmbedding` can be passed arbitrary vectors.
- self.class_embedding = TimestepEmbedding(projection_class_embeddings_input_dim, time_embed_dim)
- elif class_embed_type == "simple_projection":
- if projection_class_embeddings_input_dim is None:
- raise ValueError(
- "`class_embed_type`: 'simple_projection' requires `projection_class_embeddings_input_dim` be set"
- )
- self.class_embedding = nn.Linear(projection_class_embeddings_input_dim, time_embed_dim)
- else:
- self.class_embedding = None
-
- if time_embedding_act_fn is None:
- self.time_embed_act = None
- else:
- self.time_embed_act = get_activation(time_embedding_act_fn)
-
- self.down_blocks = nn.ModuleList([])
- self.up_blocks = nn.ModuleList([])
-
- if isinstance(only_cross_attention, bool):
- only_cross_attention = [only_cross_attention] * len(down_block_types)
-
- if isinstance(num_attention_heads, int):
- num_attention_heads = (num_attention_heads,) * len(down_block_types)
-
- if isinstance(cross_attention_dim, int):
- cross_attention_dim = (cross_attention_dim,) * len(down_block_types)
-
- if isinstance(layers_per_block, int):
- layers_per_block = [layers_per_block] * len(down_block_types)
-
- if isinstance(transformer_layers_per_block, int):
- transformer_layers_per_block = [transformer_layers_per_block] * len(down_block_types)
-
- if class_embeddings_concat:
- # The time embeddings are concatenated with the class embeddings. The dimension of the
- # time embeddings passed to the down, middle, and up blocks is twice the dimension of the
- # regular time embeddings
- blocks_time_embed_dim = time_embed_dim * 2
- else:
- blocks_time_embed_dim = time_embed_dim
-
- # down
- output_channel = block_out_channels[0]
- for i, down_block_type in enumerate(down_block_types):
- input_channel = output_channel
- output_channel = block_out_channels[i]
- is_final_block = i == len(block_out_channels) - 1
-
- down_block = get_down_block(
- down_block_type,
- num_layers=layers_per_block[i],
- transformer_layers_per_block=transformer_layers_per_block[i],
- in_channels=input_channel,
- out_channels=output_channel,
- temb_channels=blocks_time_embed_dim,
- add_downsample=not is_final_block,
- resnet_eps=norm_eps,
- resnet_act_fn=act_fn,
- resnet_groups=norm_num_groups,
- cross_attention_dim=cross_attention_dim[i],
- num_attention_heads=num_attention_heads[i],
- downsample_padding=downsample_padding,
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention[i],
- upcast_attention=upcast_attention,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- self.down_blocks.append(down_block)
-
- # mid
- if mid_block_type == "UNetMidBlock2DCrossAttn":
- self.mid_block = UNetMidBlock2DCrossAttn(
- transformer_layers_per_block=transformer_layers_per_block[-1],
- in_channels=block_out_channels[-1],
- temb_channels=blocks_time_embed_dim,
- resnet_eps=norm_eps,
- resnet_act_fn=act_fn,
- output_scale_factor=mid_block_scale_factor,
- resnet_time_scale_shift=resnet_time_scale_shift,
- cross_attention_dim=cross_attention_dim[-1],
- num_attention_heads=num_attention_heads[-1],
- resnet_groups=norm_num_groups,
- use_linear_projection=use_linear_projection,
- upcast_attention=upcast_attention,
- )
- else:
- raise ValueError(
- f"unknown mid_block_type : {mid_block_type}. Should be `UNetMidBlock2DCrossAttn` for AudioLDM2."
- )
-
- # count how many layers upsample the images
- self.num_upsamplers = 0
-
- # up
- reversed_block_out_channels = list(reversed(block_out_channels))
- reversed_num_attention_heads = list(reversed(num_attention_heads))
- reversed_layers_per_block = list(reversed(layers_per_block))
- reversed_cross_attention_dim = list(reversed(cross_attention_dim))
- reversed_transformer_layers_per_block = list(reversed(transformer_layers_per_block))
- only_cross_attention = list(reversed(only_cross_attention))
-
- output_channel = reversed_block_out_channels[0]
- for i, up_block_type in enumerate(up_block_types):
- is_final_block = i == len(block_out_channels) - 1
-
- prev_output_channel = output_channel
- output_channel = reversed_block_out_channels[i]
- input_channel = reversed_block_out_channels[min(i + 1, len(block_out_channels) - 1)]
-
- # add upsample block for all BUT final layer
- if not is_final_block:
- add_upsample = True
- self.num_upsamplers += 1
- else:
- add_upsample = False
-
- up_block = get_up_block(
- up_block_type,
- num_layers=reversed_layers_per_block[i] + 1,
- transformer_layers_per_block=reversed_transformer_layers_per_block[i],
- in_channels=input_channel,
- out_channels=output_channel,
- prev_output_channel=prev_output_channel,
- temb_channels=blocks_time_embed_dim,
- add_upsample=add_upsample,
- resnet_eps=norm_eps,
- resnet_act_fn=act_fn,
- resnet_groups=norm_num_groups,
- cross_attention_dim=reversed_cross_attention_dim[i],
- num_attention_heads=reversed_num_attention_heads[i],
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention[i],
- upcast_attention=upcast_attention,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- self.up_blocks.append(up_block)
- prev_output_channel = output_channel
-
- # out
- if norm_num_groups is not None:
- self.conv_norm_out = nn.GroupNorm(
- num_channels=block_out_channels[0], num_groups=norm_num_groups, eps=norm_eps
- )
-
- self.conv_act = get_activation(act_fn)
-
- else:
- self.conv_norm_out = None
- self.conv_act = None
-
- conv_out_padding = (conv_out_kernel - 1) // 2
- self.conv_out = nn.Conv2d(
- block_out_channels[0], out_channels, kernel_size=conv_out_kernel, padding=conv_out_padding
- )
-
- # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_default_attn_processor
- def set_default_attn_processor(self):
- """
- Disables custom attention processors and sets the default attention implementation.
- """
- if all(proc.__class__ in ADDED_KV_ATTENTION_PROCESSORS for proc in self.attn_processors.values()):
- processor = AttnAddedKVProcessor()
- elif all(proc.__class__ in CROSS_ATTENTION_PROCESSORS for proc in self.attn_processors.values()):
- processor = AttnProcessor()
- else:
- raise ValueError(
- f"Cannot call `set_default_attn_processor` when attention processors are of type {next(iter(self.attn_processors.values()))}"
- )
-
- self.set_attn_processor(processor)
-
- # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_attention_slice
- def set_attention_slice(self, slice_size):
- r"""
- Enable sliced attention computation.
-
- When this option is enabled, the attention module splits the input tensor in slices to compute attention in
- several steps. This is useful for saving some memory in exchange for a small decrease in speed.
-
- Args:
- slice_size (`str` or `int` or `list(int)`, *optional*, defaults to `"auto"`):
- When `"auto"`, input to the attention heads is halved, so attention is computed in two steps. If
- `"max"`, maximum amount of memory is saved by running only one slice at a time. If a number is
- provided, uses as many slices as `attention_head_dim // slice_size`. In this case, `attention_head_dim`
- must be a multiple of `slice_size`.
- """
- sliceable_head_dims = []
-
- def fn_recursive_retrieve_sliceable_dims(module: torch.nn.Module):
- if hasattr(module, "set_attention_slice"):
- sliceable_head_dims.append(module.sliceable_head_dim)
-
- for child in module.children():
- fn_recursive_retrieve_sliceable_dims(child)
-
- # retrieve number of attention layers
- for module in self.children():
- fn_recursive_retrieve_sliceable_dims(module)
-
- num_sliceable_layers = len(sliceable_head_dims)
-
- if slice_size == "auto":
- # half the attention head size is usually a good trade-off between
- # speed and memory
- slice_size = [dim // 2 for dim in sliceable_head_dims]
- elif slice_size == "max":
- # make smallest slice possible
- slice_size = num_sliceable_layers * [1]
-
- slice_size = num_sliceable_layers * [slice_size] if not isinstance(slice_size, list) else slice_size
-
- if len(slice_size) != len(sliceable_head_dims):
- raise ValueError(
- f"You have provided {len(slice_size)}, but {self.config} has {len(sliceable_head_dims)} different"
- f" attention layers. Make sure to match `len(slice_size)` to be {len(sliceable_head_dims)}."
- )
-
- for i in range(len(slice_size)):
- size = slice_size[i]
- dim = sliceable_head_dims[i]
- if size is not None and size > dim:
- raise ValueError(f"size {size} has to be smaller or equal to {dim}.")
-
- # Recursively walk through all the children.
- # Any children which exposes the set_attention_slice method
- # gets the message
- def fn_recursive_set_attention_slice(module: torch.nn.Module, slice_size: list[int]):
- if hasattr(module, "set_attention_slice"):
- module.set_attention_slice(slice_size.pop())
-
- for child in module.children():
- fn_recursive_set_attention_slice(child, slice_size)
-
- reversed_slice_size = list(reversed(slice_size))
- for module in self.children():
- fn_recursive_set_attention_slice(module, reversed_slice_size)
-
- def forward(
- self,
- sample: torch.Tensor,
- timestep: torch.Tensor | float | int,
- encoder_hidden_states: torch.Tensor,
- class_labels: torch.Tensor | None = None,
- timestep_cond: torch.Tensor | None = None,
- attention_mask: torch.Tensor | None = None,
- cross_attention_kwargs: dict[str, Any] | None = None,
- encoder_attention_mask: torch.Tensor | None = None,
- return_dict: bool = True,
- encoder_hidden_states_1: torch.Tensor | None = None,
- encoder_attention_mask_1: torch.Tensor | None = None,
- ) -> UNet2DConditionOutput | tuple:
- r"""
- The [`AudioLDM2UNet2DConditionModel`] forward method.
-
- Args:
- sample (`torch.Tensor`):
- The noisy input tensor with the following shape `(batch, channel, height, width)`.
- timestep (`torch.Tensor` or `float` or `int`): The number of timesteps to denoise an input.
- encoder_hidden_states (`torch.Tensor`):
- The encoder hidden states with shape `(batch, sequence_length, feature_dim)`.
- encoder_attention_mask (`torch.Tensor`):
- A cross-attention mask of shape `(batch, sequence_length)` is applied to `encoder_hidden_states`. If
- `True` the mask is kept, otherwise if `False` it is discarded. Mask will be converted into a bias,
- which adds large negative values to the attention scores corresponding to "discard" tokens.
- return_dict (`bool`, *optional*, defaults to `True`):
- Whether or not to return a [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] instead of a plain
- tuple.
- cross_attention_kwargs (`dict`, *optional*):
- A kwargs dictionary that if specified is passed along to the [`AttnProcessor`].
- encoder_hidden_states_1 (`torch.Tensor`, *optional*):
- A second set of encoder hidden states with shape `(batch, sequence_length_2, feature_dim_2)`. Can be
- used to condition the model on a different set of embeddings to `encoder_hidden_states`.
- encoder_attention_mask_1 (`torch.Tensor`, *optional*):
- A cross-attention mask of shape `(batch, sequence_length_2)` is applied to `encoder_hidden_states_1`.
- If `True` the mask is kept, otherwise if `False` it is discarded. Mask will be converted into a bias,
- which adds large negative values to the attention scores corresponding to "discard" tokens.
-
- Returns:
- [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] or `tuple`:
- If `return_dict` is True, an [`~models.unets.unet_2d_condition.UNet2DConditionOutput`] is returned,
- otherwise a `tuple` is returned where the first element is the sample tensor.
- """
- # By default samples have to be AT least a multiple of the overall upsampling factor.
- # The overall upsampling factor is equal to 2 ** (# num of upsampling layers).
- # However, the upsampling interpolation output size can be forced to fit any upsampling size
- # on the fly if necessary.
- default_overall_up_factor = 2**self.num_upsamplers
-
- # upsample size should be forwarded when sample is not a multiple of `default_overall_up_factor`
- forward_upsample_size = False
- upsample_size = None
-
- if any(s % default_overall_up_factor != 0 for s in sample.shape[-2:]):
- logger.info("Forward upsample size to force interpolation output size.")
- forward_upsample_size = True
-
- # ensure attention_mask is a bias, and give it a singleton query_tokens dimension
- # expects mask of shape:
- # [batch, key_tokens]
- # adds singleton query_tokens dimension:
- # [batch, 1, key_tokens]
- # this helps to broadcast it as a bias over attention scores, which will be in one of the following shapes:
- # [batch, heads, query_tokens, key_tokens] (e.g. torch sdp attn)
- # [batch * heads, query_tokens, key_tokens] (e.g. xformers or classic attn)
- if attention_mask is not None:
- # assume that mask is expressed as:
- # (1 = keep, 0 = discard)
- # convert mask into a bias that can be added to attention scores:
- # (keep = +0, discard = -10000.0)
- attention_mask = (1 - attention_mask.to(sample.dtype)) * -10000.0
- attention_mask = attention_mask.unsqueeze(1)
-
- # convert encoder_attention_mask to a bias the same way we do for attention_mask
- if encoder_attention_mask is not None:
- encoder_attention_mask = (1 - encoder_attention_mask.to(sample.dtype)) * -10000.0
- encoder_attention_mask = encoder_attention_mask.unsqueeze(1)
-
- if encoder_attention_mask_1 is not None:
- encoder_attention_mask_1 = (1 - encoder_attention_mask_1.to(sample.dtype)) * -10000.0
- encoder_attention_mask_1 = encoder_attention_mask_1.unsqueeze(1)
-
- # 1. time
- timesteps = timestep
- if not torch.is_tensor(timesteps):
- # TODO: this requires sync between CPU and GPU. So try to pass timesteps as tensors if you can
- # This would be a good case for the `match` statement (Python 3.10+)
- is_mps = sample.device.type == "mps"
- is_npu = sample.device.type == "npu"
- if isinstance(timestep, float):
- dtype = torch.float32 if (is_mps or is_npu) else torch.float64
- else:
- dtype = torch.int32 if (is_mps or is_npu) else torch.int64
- timesteps = torch.tensor([timesteps], dtype=dtype, device=sample.device)
- elif len(timesteps.shape) == 0:
- timesteps = timesteps[None].to(sample.device)
-
- # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
- timesteps = timesteps.expand(sample.shape[0])
-
- t_emb = self.time_proj(timesteps)
-
- # `Timesteps` does not contain any weights and will always return f32 tensors
- # but time_embedding might actually be running in fp16. so we need to cast here.
- # there might be better ways to encapsulate this.
- t_emb = t_emb.to(dtype=sample.dtype)
-
- emb = self.time_embedding(t_emb, timestep_cond)
- aug_emb = None
-
- if self.class_embedding is not None:
- if class_labels is None:
- raise ValueError("class_labels should be provided when num_class_embeds > 0")
-
- if self.config.class_embed_type == "timestep":
- class_labels = self.time_proj(class_labels)
-
- # `Timesteps` does not contain any weights and will always return f32 tensors
- # there might be better ways to encapsulate this.
- class_labels = class_labels.to(dtype=sample.dtype)
-
- class_emb = self.class_embedding(class_labels).to(dtype=sample.dtype)
-
- if self.config.class_embeddings_concat:
- emb = torch.cat([emb, class_emb], dim=-1)
- else:
- emb = emb + class_emb
-
- emb = emb + aug_emb if aug_emb is not None else emb
-
- if self.time_embed_act is not None:
- emb = self.time_embed_act(emb)
-
- # 2. pre-process
- sample = self.conv_in(sample)
-
- # 3. down
- down_block_res_samples = (sample,)
- for downsample_block in self.down_blocks:
- if hasattr(downsample_block, "has_cross_attention") and downsample_block.has_cross_attention:
- sample, res_samples = downsample_block(
- hidden_states=sample,
- temb=emb,
- encoder_hidden_states=encoder_hidden_states,
- attention_mask=attention_mask,
- cross_attention_kwargs=cross_attention_kwargs,
- encoder_attention_mask=encoder_attention_mask,
- encoder_hidden_states_1=encoder_hidden_states_1,
- encoder_attention_mask_1=encoder_attention_mask_1,
- )
- else:
- sample, res_samples = downsample_block(hidden_states=sample, temb=emb)
-
- down_block_res_samples += res_samples
-
- # 4. mid
- if self.mid_block is not None:
- sample = self.mid_block(
- sample,
- emb,
- encoder_hidden_states=encoder_hidden_states,
- attention_mask=attention_mask,
- cross_attention_kwargs=cross_attention_kwargs,
- encoder_attention_mask=encoder_attention_mask,
- encoder_hidden_states_1=encoder_hidden_states_1,
- encoder_attention_mask_1=encoder_attention_mask_1,
- )
-
- # 5. up
- for i, upsample_block in enumerate(self.up_blocks):
- is_final_block = i == len(self.up_blocks) - 1
-
- res_samples = down_block_res_samples[-len(upsample_block.resnets) :]
- down_block_res_samples = down_block_res_samples[: -len(upsample_block.resnets)]
-
- # if we have not reached the final block and need to forward the
- # upsample size, we do it here
- if not is_final_block and forward_upsample_size:
- upsample_size = down_block_res_samples[-1].shape[2:]
-
- if hasattr(upsample_block, "has_cross_attention") and upsample_block.has_cross_attention:
- sample = upsample_block(
- hidden_states=sample,
- temb=emb,
- res_hidden_states_tuple=res_samples,
- encoder_hidden_states=encoder_hidden_states,
- cross_attention_kwargs=cross_attention_kwargs,
- upsample_size=upsample_size,
- attention_mask=attention_mask,
- encoder_attention_mask=encoder_attention_mask,
- encoder_hidden_states_1=encoder_hidden_states_1,
- encoder_attention_mask_1=encoder_attention_mask_1,
- )
- else:
- sample = upsample_block(
- hidden_states=sample, temb=emb, res_hidden_states_tuple=res_samples, upsample_size=upsample_size
- )
-
- # 6. post-process
- if self.conv_norm_out:
- sample = self.conv_norm_out(sample)
- sample = self.conv_act(sample)
- sample = self.conv_out(sample)
-
- if not return_dict:
- return (sample,)
-
- return UNet2DConditionOutput(sample=sample)
-
-
-def get_down_block(
- down_block_type,
- num_layers,
- in_channels,
- out_channels,
- temb_channels,
- add_downsample,
- resnet_eps,
- resnet_act_fn,
- transformer_layers_per_block=1,
- num_attention_heads=None,
- resnet_groups=None,
- cross_attention_dim=None,
- downsample_padding=None,
- use_linear_projection=False,
- only_cross_attention=False,
- upcast_attention=False,
- resnet_time_scale_shift="default",
-):
- down_block_type = down_block_type[7:] if down_block_type.startswith("UNetRes") else down_block_type
- if down_block_type == "DownBlock2D":
- return DownBlock2D(
- num_layers=num_layers,
- in_channels=in_channels,
- out_channels=out_channels,
- temb_channels=temb_channels,
- add_downsample=add_downsample,
- resnet_eps=resnet_eps,
- resnet_act_fn=resnet_act_fn,
- resnet_groups=resnet_groups,
- downsample_padding=downsample_padding,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- elif down_block_type == "CrossAttnDownBlock2D":
- if cross_attention_dim is None:
- raise ValueError("cross_attention_dim must be specified for CrossAttnDownBlock2D")
- return CrossAttnDownBlock2D(
- num_layers=num_layers,
- transformer_layers_per_block=transformer_layers_per_block,
- in_channels=in_channels,
- out_channels=out_channels,
- temb_channels=temb_channels,
- add_downsample=add_downsample,
- resnet_eps=resnet_eps,
- resnet_act_fn=resnet_act_fn,
- resnet_groups=resnet_groups,
- downsample_padding=downsample_padding,
- cross_attention_dim=cross_attention_dim,
- num_attention_heads=num_attention_heads,
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention,
- upcast_attention=upcast_attention,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- raise ValueError(f"{down_block_type} does not exist.")
-
-
-def get_up_block(
- up_block_type,
- num_layers,
- in_channels,
- out_channels,
- prev_output_channel,
- temb_channels,
- add_upsample,
- resnet_eps,
- resnet_act_fn,
- transformer_layers_per_block=1,
- num_attention_heads=None,
- resnet_groups=None,
- cross_attention_dim=None,
- use_linear_projection=False,
- only_cross_attention=False,
- upcast_attention=False,
- resnet_time_scale_shift="default",
-):
- up_block_type = up_block_type[7:] if up_block_type.startswith("UNetRes") else up_block_type
- if up_block_type == "UpBlock2D":
- return UpBlock2D(
- num_layers=num_layers,
- in_channels=in_channels,
- out_channels=out_channels,
- prev_output_channel=prev_output_channel,
- temb_channels=temb_channels,
- add_upsample=add_upsample,
- resnet_eps=resnet_eps,
- resnet_act_fn=resnet_act_fn,
- resnet_groups=resnet_groups,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- elif up_block_type == "CrossAttnUpBlock2D":
- if cross_attention_dim is None:
- raise ValueError("cross_attention_dim must be specified for CrossAttnUpBlock2D")
- return CrossAttnUpBlock2D(
- num_layers=num_layers,
- transformer_layers_per_block=transformer_layers_per_block,
- in_channels=in_channels,
- out_channels=out_channels,
- prev_output_channel=prev_output_channel,
- temb_channels=temb_channels,
- add_upsample=add_upsample,
- resnet_eps=resnet_eps,
- resnet_act_fn=resnet_act_fn,
- resnet_groups=resnet_groups,
- cross_attention_dim=cross_attention_dim,
- num_attention_heads=num_attention_heads,
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention,
- upcast_attention=upcast_attention,
- resnet_time_scale_shift=resnet_time_scale_shift,
- )
- raise ValueError(f"{up_block_type} does not exist.")
-
-
-class CrossAttnDownBlock2D(nn.Module):
- def __init__(
- self,
- in_channels: int,
- out_channels: int,
- temb_channels: int,
- dropout: float = 0.0,
- num_layers: int = 1,
- transformer_layers_per_block: int = 1,
- resnet_eps: float = 1e-6,
- resnet_time_scale_shift: str = "default",
- resnet_act_fn: str = "swish",
- resnet_groups: int = 32,
- resnet_pre_norm: bool = True,
- num_attention_heads=1,
- cross_attention_dim=1280,
- output_scale_factor=1.0,
- downsample_padding=1,
- add_downsample=True,
- use_linear_projection=False,
- only_cross_attention=False,
- upcast_attention=False,
- ):
- super().__init__()
- resnets = []
- attentions = []
-
- self.has_cross_attention = True
- self.num_attention_heads = num_attention_heads
-
- if isinstance(cross_attention_dim, int):
- cross_attention_dim = (cross_attention_dim,)
- if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
- raise ValueError(
- "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
- f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
- )
- self.cross_attention_dim = cross_attention_dim
-
- for i in range(num_layers):
- in_channels = in_channels if i == 0 else out_channels
- resnets.append(
- ResnetBlock2D(
- in_channels=in_channels,
- out_channels=out_channels,
- temb_channels=temb_channels,
- eps=resnet_eps,
- groups=resnet_groups,
- dropout=dropout,
- time_embedding_norm=resnet_time_scale_shift,
- non_linearity=resnet_act_fn,
- output_scale_factor=output_scale_factor,
- pre_norm=resnet_pre_norm,
- )
- )
- for j in range(len(cross_attention_dim)):
- attentions.append(
- Transformer2DModel(
- num_attention_heads,
- out_channels // num_attention_heads,
- in_channels=out_channels,
- num_layers=transformer_layers_per_block,
- cross_attention_dim=cross_attention_dim[j],
- norm_num_groups=resnet_groups,
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention,
- upcast_attention=upcast_attention,
- double_self_attention=True if cross_attention_dim[j] is None else False,
- )
- )
- self.attentions = nn.ModuleList(attentions)
- self.resnets = nn.ModuleList(resnets)
-
- if add_downsample:
- self.downsamplers = nn.ModuleList(
- [
- Downsample2D(
- out_channels, use_conv=True, out_channels=out_channels, padding=downsample_padding, name="op"
- )
- ]
- )
- else:
- self.downsamplers = None
-
- self.gradient_checkpointing = False
-
- def forward(
- self,
- hidden_states: torch.Tensor,
- temb: torch.Tensor | None = None,
- encoder_hidden_states: torch.Tensor | None = None,
- attention_mask: torch.Tensor | None = None,
- cross_attention_kwargs: dict[str, Any] | None = None,
- encoder_attention_mask: torch.Tensor | None = None,
- encoder_hidden_states_1: torch.Tensor | None = None,
- encoder_attention_mask_1: torch.Tensor | None = None,
- ):
- output_states = ()
- num_layers = len(self.resnets)
- num_attention_per_layer = len(self.attentions) // num_layers
-
- encoder_hidden_states_1 = (
- encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
- )
- encoder_attention_mask_1 = (
- encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
- )
-
- for i in range(num_layers):
- if torch.is_grad_enabled() and self.gradient_checkpointing:
- hidden_states = self._gradient_checkpointing_func(self.resnets[i], hidden_states, temb)
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self._gradient_checkpointing_func(
- self.attentions[i * num_attention_per_layer + idx],
- hidden_states,
- forward_encoder_hidden_states,
- None, # timestep
- None, # class_labels
- cross_attention_kwargs,
- attention_mask,
- forward_encoder_attention_mask,
- )[0]
- else:
- hidden_states = self.resnets[i](hidden_states, temb)
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self.attentions[i * num_attention_per_layer + idx](
- hidden_states,
- attention_mask=attention_mask,
- encoder_hidden_states=forward_encoder_hidden_states,
- encoder_attention_mask=forward_encoder_attention_mask,
- return_dict=False,
- )[0]
-
- output_states = output_states + (hidden_states,)
-
- if self.downsamplers is not None:
- for downsampler in self.downsamplers:
- hidden_states = downsampler(hidden_states)
-
- output_states = output_states + (hidden_states,)
-
- return hidden_states, output_states
-
-
-class UNetMidBlock2DCrossAttn(nn.Module):
- def __init__(
- self,
- in_channels: int,
- temb_channels: int,
- dropout: float = 0.0,
- num_layers: int = 1,
- transformer_layers_per_block: int = 1,
- resnet_eps: float = 1e-6,
- resnet_time_scale_shift: str = "default",
- resnet_act_fn: str = "swish",
- resnet_groups: int = 32,
- resnet_pre_norm: bool = True,
- num_attention_heads=1,
- output_scale_factor=1.0,
- cross_attention_dim=1280,
- use_linear_projection=False,
- upcast_attention=False,
- ):
- super().__init__()
-
- self.has_cross_attention = True
- self.num_attention_heads = num_attention_heads
- resnet_groups = resnet_groups if resnet_groups is not None else min(in_channels // 4, 32)
-
- if isinstance(cross_attention_dim, int):
- cross_attention_dim = (cross_attention_dim,)
- if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
- raise ValueError(
- "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
- f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
- )
- self.cross_attention_dim = cross_attention_dim
-
- # there is always at least one resnet
- resnets = [
- ResnetBlock2D(
- in_channels=in_channels,
- out_channels=in_channels,
- temb_channels=temb_channels,
- eps=resnet_eps,
- groups=resnet_groups,
- dropout=dropout,
- time_embedding_norm=resnet_time_scale_shift,
- non_linearity=resnet_act_fn,
- output_scale_factor=output_scale_factor,
- pre_norm=resnet_pre_norm,
- )
- ]
- attentions = []
-
- for i in range(num_layers):
- for j in range(len(cross_attention_dim)):
- attentions.append(
- Transformer2DModel(
- num_attention_heads,
- in_channels // num_attention_heads,
- in_channels=in_channels,
- num_layers=transformer_layers_per_block,
- cross_attention_dim=cross_attention_dim[j],
- norm_num_groups=resnet_groups,
- use_linear_projection=use_linear_projection,
- upcast_attention=upcast_attention,
- double_self_attention=True if cross_attention_dim[j] is None else False,
- )
- )
- resnets.append(
- ResnetBlock2D(
- in_channels=in_channels,
- out_channels=in_channels,
- temb_channels=temb_channels,
- eps=resnet_eps,
- groups=resnet_groups,
- dropout=dropout,
- time_embedding_norm=resnet_time_scale_shift,
- non_linearity=resnet_act_fn,
- output_scale_factor=output_scale_factor,
- pre_norm=resnet_pre_norm,
- )
- )
-
- self.attentions = nn.ModuleList(attentions)
- self.resnets = nn.ModuleList(resnets)
-
- self.gradient_checkpointing = False
-
- def forward(
- self,
- hidden_states: torch.Tensor,
- temb: torch.Tensor | None = None,
- encoder_hidden_states: torch.Tensor | None = None,
- attention_mask: torch.Tensor | None = None,
- cross_attention_kwargs: dict[str, Any] | None = None,
- encoder_attention_mask: torch.Tensor | None = None,
- encoder_hidden_states_1: torch.Tensor | None = None,
- encoder_attention_mask_1: torch.Tensor | None = None,
- ) -> torch.Tensor:
- hidden_states = self.resnets[0](hidden_states, temb)
- num_attention_per_layer = len(self.attentions) // (len(self.resnets) - 1)
-
- encoder_hidden_states_1 = (
- encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
- )
- encoder_attention_mask_1 = (
- encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
- )
-
- for i in range(len(self.resnets[1:])):
- if torch.is_grad_enabled() and self.gradient_checkpointing:
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self._gradient_checkpointing_func(
- self.attentions[i * num_attention_per_layer + idx],
- hidden_states,
- forward_encoder_hidden_states,
- None, # timestep
- None, # class_labels
- cross_attention_kwargs,
- attention_mask,
- forward_encoder_attention_mask,
- )[0]
- hidden_states = self._gradient_checkpointing_func(self.resnets[i + 1], hidden_states, temb)
- else:
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self.attentions[i * num_attention_per_layer + idx](
- hidden_states,
- attention_mask=attention_mask,
- encoder_hidden_states=forward_encoder_hidden_states,
- encoder_attention_mask=forward_encoder_attention_mask,
- return_dict=False,
- )[0]
-
- hidden_states = self.resnets[i + 1](hidden_states, temb)
-
- return hidden_states
-
-
-class CrossAttnUpBlock2D(nn.Module):
- def __init__(
- self,
- in_channels: int,
- out_channels: int,
- prev_output_channel: int,
- temb_channels: int,
- dropout: float = 0.0,
- num_layers: int = 1,
- transformer_layers_per_block: int = 1,
- resnet_eps: float = 1e-6,
- resnet_time_scale_shift: str = "default",
- resnet_act_fn: str = "swish",
- resnet_groups: int = 32,
- resnet_pre_norm: bool = True,
- num_attention_heads=1,
- cross_attention_dim=1280,
- output_scale_factor=1.0,
- add_upsample=True,
- use_linear_projection=False,
- only_cross_attention=False,
- upcast_attention=False,
- ):
- super().__init__()
- resnets = []
- attentions = []
-
- self.has_cross_attention = True
- self.num_attention_heads = num_attention_heads
-
- if isinstance(cross_attention_dim, int):
- cross_attention_dim = (cross_attention_dim,)
- if isinstance(cross_attention_dim, (list, tuple)) and len(cross_attention_dim) > 4:
- raise ValueError(
- "Only up to 4 cross-attention layers are supported. Ensure that the length of cross-attention "
- f"dims is less than or equal to 4. Got cross-attention dims {cross_attention_dim} of length {len(cross_attention_dim)}"
- )
- self.cross_attention_dim = cross_attention_dim
-
- for i in range(num_layers):
- res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
- resnet_in_channels = prev_output_channel if i == 0 else out_channels
-
- resnets.append(
- ResnetBlock2D(
- in_channels=resnet_in_channels + res_skip_channels,
- out_channels=out_channels,
- temb_channels=temb_channels,
- eps=resnet_eps,
- groups=resnet_groups,
- dropout=dropout,
- time_embedding_norm=resnet_time_scale_shift,
- non_linearity=resnet_act_fn,
- output_scale_factor=output_scale_factor,
- pre_norm=resnet_pre_norm,
- )
- )
- for j in range(len(cross_attention_dim)):
- attentions.append(
- Transformer2DModel(
- num_attention_heads,
- out_channels // num_attention_heads,
- in_channels=out_channels,
- num_layers=transformer_layers_per_block,
- cross_attention_dim=cross_attention_dim[j],
- norm_num_groups=resnet_groups,
- use_linear_projection=use_linear_projection,
- only_cross_attention=only_cross_attention,
- upcast_attention=upcast_attention,
- double_self_attention=True if cross_attention_dim[j] is None else False,
- )
- )
- self.attentions = nn.ModuleList(attentions)
- self.resnets = nn.ModuleList(resnets)
-
- if add_upsample:
- self.upsamplers = nn.ModuleList([Upsample2D(out_channels, use_conv=True, out_channels=out_channels)])
- else:
- self.upsamplers = None
-
- self.gradient_checkpointing = False
-
- def forward(
- self,
- hidden_states: torch.Tensor,
- res_hidden_states_tuple: tuple[torch.Tensor, ...],
- temb: torch.Tensor | None = None,
- encoder_hidden_states: torch.Tensor | None = None,
- cross_attention_kwargs: dict[str, Any] | None = None,
- upsample_size: int | None = None,
- attention_mask: torch.Tensor | None = None,
- encoder_attention_mask: torch.Tensor | None = None,
- encoder_hidden_states_1: torch.Tensor | None = None,
- encoder_attention_mask_1: torch.Tensor | None = None,
- ):
- num_layers = len(self.resnets)
- num_attention_per_layer = len(self.attentions) // num_layers
-
- encoder_hidden_states_1 = (
- encoder_hidden_states_1 if encoder_hidden_states_1 is not None else encoder_hidden_states
- )
- encoder_attention_mask_1 = (
- encoder_attention_mask_1 if encoder_hidden_states_1 is not None else encoder_attention_mask
- )
-
- for i in range(num_layers):
- # pop res hidden states
- res_hidden_states = res_hidden_states_tuple[-1]
- res_hidden_states_tuple = res_hidden_states_tuple[:-1]
- hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
-
- if torch.is_grad_enabled() and self.gradient_checkpointing:
- hidden_states = self._gradient_checkpointing_func(self.resnets[i], hidden_states, temb)
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self._gradient_checkpointing_func(
- self.attentions[i * num_attention_per_layer + idx],
- hidden_states,
- forward_encoder_hidden_states,
- None, # timestep
- None, # class_labels
- cross_attention_kwargs,
- attention_mask,
- forward_encoder_attention_mask,
- )[0]
- else:
- hidden_states = self.resnets[i](hidden_states, temb)
- for idx, cross_attention_dim in enumerate(self.cross_attention_dim):
- if cross_attention_dim is not None and idx <= 1:
- forward_encoder_hidden_states = encoder_hidden_states
- forward_encoder_attention_mask = encoder_attention_mask
- elif cross_attention_dim is not None and idx > 1:
- forward_encoder_hidden_states = encoder_hidden_states_1
- forward_encoder_attention_mask = encoder_attention_mask_1
- else:
- forward_encoder_hidden_states = None
- forward_encoder_attention_mask = None
- hidden_states = self.attentions[i * num_attention_per_layer + idx](
- hidden_states,
- attention_mask=attention_mask,
- encoder_hidden_states=forward_encoder_hidden_states,
- encoder_attention_mask=forward_encoder_attention_mask,
- return_dict=False,
- )[0]
-
- if self.upsamplers is not None:
- for upsampler in self.upsamplers:
- hidden_states = upsampler(hidden_states, upsample_size)
-
- return hidden_states
+from ...models.unets.unet_2d_condition_audioldm2 import AudioLDM2UNet2DConditionModel as _AudioLDM2UNet2DConditionModel
+from ...utils import deprecate
# Deprecated alias kept for backward compatibility. The warning is raised from `__new__` rather than `__init__` so
@@ -1304,3 +30,14 @@ def __new__(cls, *args, **kwargs):
"Import it with `from diffusers import AudioLDM2ProjectionModel` instead.",
)
return super().__new__(cls)
+
+
+class AudioLDM2UNet2DConditionModel(_AudioLDM2UNet2DConditionModel):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "AudioLDM2UNet2DConditionModel",
+ "1.0.0",
+ "Importing `AudioLDM2UNet2DConditionModel` from `diffusers.pipelines.audioldm2.modeling_audioldm2` is deprecated. "
+ "Import it with `from diffusers import AudioLDM2UNet2DConditionModel` instead.",
+ )
+ return super().__new__(cls)
diff --git a/src/diffusers/pipelines/audioldm2/pipeline_audioldm2.py b/src/diffusers/pipelines/audioldm2/pipeline_audioldm2.py
index 9a5d69c0df09..049acd133cd0 100644
--- a/src/diffusers/pipelines/audioldm2/pipeline_audioldm2.py
+++ b/src/diffusers/pipelines/audioldm2/pipeline_audioldm2.py
@@ -34,6 +34,7 @@
from ...dependency_versions_table import deps
from ...models import AutoencoderKL
from ...models.condition_embedders import AudioLDM2ProjectionModel
+from ...models.unets import AudioLDM2UNet2DConditionModel
from ...schedulers import KarrasDiffusionSchedulers
from ...utils import (
is_accelerate_available,
@@ -44,7 +45,6 @@
from ...utils.import_utils import is_transformers_version
from ...utils.torch_utils import empty_device_cache, randn_tensor
from ..pipeline_utils import AudioPipelineOutput, DiffusionPipeline
-from .modeling_audioldm2 import AudioLDM2UNet2DConditionModel
if is_librosa_available():
diff --git a/src/diffusers/pipelines/deprecated/__init__.py b/src/diffusers/pipelines/deprecated/__init__.py
index 3eec8e849592..e433928b62a4 100644
--- a/src/diffusers/pipelines/deprecated/__init__.py
+++ b/src/diffusers/pipelines/deprecated/__init__.py
@@ -61,6 +61,7 @@
_import_structure["musicldm"] = ["MusicLDMPipeline"]
_import_structure["paint_by_example"] = ["PaintByExamplePipeline"]
_import_structure["pia"] = ["PIAPipeline"]
+ _import_structure["shap_e"] = ["ShapEImg2ImgPipeline", "ShapEPipeline"]
_import_structure["semantic_stable_diffusion"] = ["SemanticStableDiffusionPipeline"]
_import_structure["stable_diffusion_attend_and_excite"] = ["StableDiffusionAttendAndExcitePipeline"]
_import_structure["stable_diffusion_diffedit"] = ["StableDiffusionDiffEditPipeline"]
@@ -154,6 +155,7 @@
from .paint_by_example import PaintByExamplePipeline
from .pia import PIAPipeline
from .semantic_stable_diffusion import SemanticStableDiffusionPipeline
+ from .shap_e import ShapEImg2ImgPipeline, ShapEPipeline
from .spectrogram_diffusion import SpectrogramDiffusionPipeline
from .stable_diffusion_attend_and_excite import StableDiffusionAttendAndExcitePipeline
from .stable_diffusion_diffedit import StableDiffusionDiffEditPipeline
diff --git a/src/diffusers/pipelines/shap_e/__init__.py b/src/diffusers/pipelines/deprecated/shap_e/__init__.py
similarity index 91%
rename from src/diffusers/pipelines/shap_e/__init__.py
rename to src/diffusers/pipelines/deprecated/shap_e/__init__.py
index 4ed563c4a51f..c80732bf4de2 100644
--- a/src/diffusers/pipelines/shap_e/__init__.py
+++ b/src/diffusers/pipelines/deprecated/shap_e/__init__.py
@@ -1,6 +1,6 @@
from typing import TYPE_CHECKING
-from ...utils import (
+from ....utils import (
DIFFUSERS_SLOW_IMPORT,
OptionalDependencyNotAvailable,
_LazyModule,
@@ -17,7 +17,7 @@
if not (is_transformers_available() and is_torch_available()):
raise OptionalDependencyNotAvailable()
except OptionalDependencyNotAvailable:
- from ...utils import dummy_torch_and_transformers_objects # noqa F403
+ from ....utils import dummy_torch_and_transformers_objects # noqa F403
_dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_objects))
else:
@@ -41,7 +41,7 @@
raise OptionalDependencyNotAvailable()
except OptionalDependencyNotAvailable:
- from ...utils.dummy_torch_and_transformers_objects import *
+ from ....utils.dummy_torch_and_transformers_objects import *
else:
from .camera import create_pan_cameras
from .pipeline_shap_e import ShapEPipeline
diff --git a/src/diffusers/pipelines/shap_e/camera.py b/src/diffusers/pipelines/deprecated/shap_e/camera.py
similarity index 100%
rename from src/diffusers/pipelines/shap_e/camera.py
rename to src/diffusers/pipelines/deprecated/shap_e/camera.py
diff --git a/src/diffusers/pipelines/shap_e/pipeline_shap_e.py b/src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e.py
similarity index 93%
rename from src/diffusers/pipelines/shap_e/pipeline_shap_e.py
rename to src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e.py
index 56e8f57dab35..5fdc85c2a724 100644
--- a/src/diffusers/pipelines/shap_e/pipeline_shap_e.py
+++ b/src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e.py
@@ -20,16 +20,16 @@
import torch
from transformers import CLIPTextModelWithProjection, CLIPTokenizer
-from ...models import PriorTransformer
-from ...schedulers import HeunDiscreteScheduler
-from ...utils import (
+from ....models import PriorTransformer
+from ....schedulers import HeunDiscreteScheduler
+from ....utils import (
BaseOutput,
is_torch_xla_available,
logging,
replace_example_docstring,
)
-from ...utils.torch_utils import randn_tensor
-from ..pipeline_utils import DiffusionPipeline
+from ....utils.torch_utils import randn_tensor
+from ...pipeline_utils import DeprecatedPipelineMixin, DiffusionPipeline
from .renderer import ShapERenderer
@@ -40,6 +40,7 @@
else:
XLA_AVAILABLE = False
+
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
@@ -84,7 +85,7 @@ class ShapEPipelineOutput(BaseOutput):
images: list[list[PIL.Image.Image]] | list[list[np.ndarray]]
-class ShapEPipeline(DiffusionPipeline):
+class ShapEPipeline(DeprecatedPipelineMixin, DiffusionPipeline):
"""
Pipeline for generating latent representation of a 3D asset and rendering with the NeRF method.
@@ -105,6 +106,8 @@ class ShapEPipeline(DiffusionPipeline):
rendering method.
"""
+ _last_supported_version = "0.43.0"
+
model_cpu_offload_seq = "text_encoder->prior"
_exclude_from_cpu_offload = ["shap_e_renderer"]
@@ -228,15 +231,15 @@ def __call__(
The output format of the generated image. Choose between `"pil"` (`PIL.Image.Image`), `"np"`
(`np.array`), `"latent"` (`torch.Tensor`), or mesh ([`MeshDecoderOutput`]).
return_dict (`bool`, *optional*, defaults to `True`):
- Whether or not to return a [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] instead of a plain
- tuple.
+ Whether or not to return a [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] instead
+ of a plain tuple.
Examples:
Returns:
- [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] or `tuple`:
- If `return_dict` is `True`, [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] is returned,
- otherwise a `tuple` is returned where the first element is a list with the generated images.
+ [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] or `tuple`:
+ If `return_dict` is `True`, [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] is
+ returned, otherwise a `tuple` is returned where the first element is a list with the generated images.
"""
if isinstance(prompt, str):
diff --git a/src/diffusers/pipelines/shap_e/pipeline_shap_e_img2img.py b/src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e_img2img.py
similarity index 93%
rename from src/diffusers/pipelines/shap_e/pipeline_shap_e_img2img.py
rename to src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e_img2img.py
index 403d5fa8a743..7d95d2ddfbee 100644
--- a/src/diffusers/pipelines/shap_e/pipeline_shap_e_img2img.py
+++ b/src/diffusers/pipelines/deprecated/shap_e/pipeline_shap_e_img2img.py
@@ -19,16 +19,16 @@
import torch
from transformers import CLIPImageProcessor, CLIPVisionModel
-from ...models import PriorTransformer
-from ...schedulers import HeunDiscreteScheduler
-from ...utils import (
+from ....models import PriorTransformer
+from ....schedulers import HeunDiscreteScheduler
+from ....utils import (
BaseOutput,
is_torch_xla_available,
logging,
replace_example_docstring,
)
-from ...utils.torch_utils import randn_tensor
-from ..pipeline_utils import DiffusionPipeline
+from ....utils.torch_utils import randn_tensor
+from ...pipeline_utils import DeprecatedPipelineMixin, DiffusionPipeline
from .renderer import ShapERenderer
@@ -39,6 +39,7 @@
else:
XLA_AVAILABLE = False
+
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
@@ -85,7 +86,7 @@ class ShapEPipelineOutput(BaseOutput):
images: PIL.Image.Image | np.ndarray
-class ShapEImg2ImgPipeline(DiffusionPipeline):
+class ShapEImg2ImgPipeline(DeprecatedPipelineMixin, DiffusionPipeline):
"""
Pipeline for generating latent representation of a 3D asset and rendering with the NeRF method from an image.
@@ -106,6 +107,8 @@ class ShapEImg2ImgPipeline(DiffusionPipeline):
rendering method.
"""
+ _last_supported_version = "0.43.0"
+
model_cpu_offload_seq = "image_encoder->prior"
_exclude_from_cpu_offload = ["shap_e_renderer"]
@@ -211,15 +214,15 @@ def __call__(
The output format of the generated image. Choose between `"pil"` (`PIL.Image.Image`), `"np"`
(`np.array`), `"latent"` (`torch.Tensor`), or mesh ([`MeshDecoderOutput`]).
return_dict (`bool`, *optional*, defaults to `True`):
- Whether or not to return a [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] instead of a plain
- tuple.
+ Whether or not to return a [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] instead
+ of a plain tuple.
Examples:
Returns:
- [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] or `tuple`:
- If `return_dict` is `True`, [`~pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput`] is returned,
- otherwise a `tuple` is returned where the first element is a list with the generated images.
+ [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] or `tuple`:
+ If `return_dict` is `True`, [`~pipelines.deprecated.shap_e.pipeline_shap_e.ShapEPipelineOutput`] is
+ returned, otherwise a `tuple` is returned where the first element is a list with the generated images.
"""
if isinstance(image, PIL.Image.Image):
diff --git a/src/diffusers/pipelines/shap_e/renderer.py b/src/diffusers/pipelines/deprecated/shap_e/renderer.py
similarity index 99%
rename from src/diffusers/pipelines/shap_e/renderer.py
rename to src/diffusers/pipelines/deprecated/shap_e/renderer.py
index 0c2058c887fc..73e913ed4380 100644
--- a/src/diffusers/pipelines/shap_e/renderer.py
+++ b/src/diffusers/pipelines/deprecated/shap_e/renderer.py
@@ -20,9 +20,9 @@
import torch.nn.functional as F
from torch import nn
-from ...configuration_utils import ConfigMixin, register_to_config
-from ...models import ModelMixin
-from ...utils import BaseOutput
+from ....configuration_utils import ConfigMixin, register_to_config
+from ....models import ModelMixin
+from ....utils import BaseOutput
from .camera import create_pan_cameras
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2.py
index 0d5341d4f41e..e7462aa5dfdf 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2.py
@@ -31,7 +31,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...image_processor import PipelineImageInput
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
@@ -55,7 +55,6 @@
from .utils import (
conditioning_frame_rate as get_conditioning_frame_rate,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_condition.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_condition.py
index d876dec5b399..9f28ff5ee9b6 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_condition.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_condition.py
@@ -33,7 +33,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...image_processor import PipelineImageInput
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
@@ -59,7 +59,6 @@
from .utils import (
conditioning_frame_rate as get_conditioning_frame_rate,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr.py
index f9c6729f2e02..ea232a3a331e 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr.py
@@ -31,7 +31,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...image_processor import PipelineImageInput
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler, LTXEulerAncestralRFScheduler
@@ -61,7 +61,6 @@
resolve_default_image_crf,
trim_canvas,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr_temporal_refine.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr_temporal_refine.py
index df71dda6d644..7a46047760c9 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr_temporal_refine.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_dfr_temporal_refine.py
@@ -28,7 +28,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.latent_upscaler import LTX2LatentUpsamplerModel
from ...models.transformers import LTX2VideoTransformer3DModel
@@ -49,7 +49,6 @@
apply_image_conditioning_crf,
resolve_default_image_crf,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_hdr_lora.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_hdr_lora.py
index 261521fdef18..018dd5dbeeec 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_hdr_lora.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_hdr_lora.py
@@ -29,7 +29,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
@@ -38,7 +38,6 @@
from ..pipeline_utils import DiffusionPipeline
from .image_processor import LTX2VideoHDRProcessor
from .pipeline_output import LTX2PipelineOutput
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_ic_lora.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_ic_lora.py
index 0e01c9610388..5f6253589525 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_ic_lora.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_ic_lora.py
@@ -33,7 +33,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...image_processor import PipelineImageInput
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
@@ -59,7 +59,6 @@
from .utils import (
conditioning_frame_rate as get_conditioning_frame_rate,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/pipeline_ltx2_image2video.py b/src/diffusers/pipelines/ltx2/pipeline_ltx2_image2video.py
index 0bc45b0c1895..82a5ddb31d5c 100644
--- a/src/diffusers/pipelines/ltx2/pipeline_ltx2_image2video.py
+++ b/src/diffusers/pipelines/ltx2/pipeline_ltx2_image2video.py
@@ -31,7 +31,7 @@
from ...callbacks import MultiPipelineCallbacks, PipelineCallback
from ...image_processor import PipelineImageInput
from ...loaders import FromSingleFileMixin, LTX2LoraLoaderMixin
-from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video
+from ...models.autoencoders import AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video, LTX2Vocoder, LTX2VocoderWithBWE
from ...models.condition_embedders import LTX2TextConnectors
from ...models.transformers import LTX2VideoTransformer3DModel
from ...schedulers import FlowMatchEulerDiscreteScheduler
@@ -56,7 +56,6 @@
from .utils import (
conditioning_frame_rate as get_conditioning_frame_rate,
)
-from .vocoder import LTX2Vocoder, LTX2VocoderWithBWE
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/ltx2/vocoder.py b/src/diffusers/pipelines/ltx2/vocoder.py
index f0004f2ec02d..bb5f14357e4c 100644
--- a/src/diffusers/pipelines/ltx2/vocoder.py
+++ b/src/diffusers/pipelines/ltx2/vocoder.py
@@ -1,597 +1,41 @@
-import math
-
-import torch
-import torch.nn as nn
-import torch.nn.functional as F
-
-from ...configuration_utils import ConfigMixin, register_to_config
-from ...models.modeling_utils import ModelMixin
-
-
-def kaiser_sinc_filter1d(cutoff: float, half_width: float, kernel_size: int) -> torch.Tensor:
- """
- Creates a Kaiser sinc kernel for low-pass filtering.
-
- Args:
- cutoff (`float`):
- Normalized frequency cutoff (relative to the sampling rate). Must be between 0 and 0.5 (the Nyquist
- frequency).
- half_width (`float`):
- Used to determine the Kaiser window's beta parameter.
- kernel_size:
- Size of the Kaiser window (and ultimately the Kaiser sinc kernel).
-
- Returns:
- `torch.Tensor` of shape `(kernel_size,)`:
- The Kaiser sinc kernel.
- """
- delta_f = 4 * half_width
- half_size = kernel_size // 2
- amplitude = 2.285 * (half_size - 1) * math.pi * delta_f + 7.95
- if amplitude > 50.0:
- beta = 0.1102 * (amplitude - 8.7)
- elif amplitude >= 21.0:
- beta = 0.5842 * (amplitude - 21) ** 0.4 + 0.07886 * (amplitude - 21.0)
- else:
- beta = 0.0
-
- window = torch.kaiser_window(kernel_size, beta=beta, periodic=False)
-
- even = kernel_size % 2 == 0
- time = torch.arange(-half_size, half_size) + 0.5 if even else torch.arange(kernel_size) - half_size
-
- if cutoff == 0.0:
- filter = torch.zeros_like(time)
- else:
- time = 2 * cutoff * time
- sinc = torch.where(
- time == 0,
- torch.ones_like(time),
- torch.sin(math.pi * time) / math.pi / time,
- )
- filter = 2 * cutoff * window * sinc
- filter = filter / filter.sum()
- return filter
-
-
-class DownSample1d(nn.Module):
- """1D low-pass filter for antialias downsampling."""
-
- def __init__(
- self,
- ratio: int = 2,
- kernel_size: int | None = None,
- use_padding: bool = True,
- padding_mode: str = "replicate",
- persistent: bool = True,
- ):
- super().__init__()
- self.ratio = ratio
- self.kernel_size = kernel_size or int(6 * ratio // 2) * 2
- self.pad_left = self.kernel_size // 2 + (self.kernel_size % 2) - 1
- self.pad_right = self.kernel_size // 2
- self.use_padding = use_padding
- self.padding_mode = padding_mode
-
- cutoff = 0.5 / ratio
- half_width = 0.6 / ratio
- low_pass_filter = kaiser_sinc_filter1d(cutoff, half_width, self.kernel_size)
- self.register_buffer("filter", low_pass_filter.view(1, 1, self.kernel_size), persistent=persistent)
-
- def forward(self, x: torch.Tensor) -> torch.Tensor:
- # x expected shape: [batch_size, num_channels, hidden_dim]
- num_channels = x.shape[1]
- if self.use_padding:
- x = F.pad(x, (self.pad_left, self.pad_right), mode=self.padding_mode)
- x_filtered = F.conv1d(x, self.filter.expand(num_channels, -1, -1), stride=self.ratio, groups=num_channels)
- return x_filtered
-
-
-class UpSample1d(nn.Module):
- def __init__(
- self,
- ratio: int = 2,
- kernel_size: int | None = None,
- window_type: str = "kaiser",
- padding_mode: str = "replicate",
- persistent: bool = True,
- ):
- super().__init__()
- self.ratio = ratio
- self.padding_mode = padding_mode
-
- if window_type == "hann":
- rolloff = 0.99
- lowpass_filter_width = 6
- width = math.ceil(lowpass_filter_width / rolloff)
- self.kernel_size = 2 * width * ratio + 1
- self.pad = width
- self.pad_left = 2 * width * ratio
- self.pad_right = self.kernel_size - ratio
-
- time_axis = (torch.arange(self.kernel_size) / ratio - width) * rolloff
- time_clamped = time_axis.clamp(-lowpass_filter_width, lowpass_filter_width)
- window = torch.cos(time_clamped * math.pi / lowpass_filter_width / 2) ** 2
- sinc_filter = (torch.sinc(time_axis) * window * rolloff / ratio).view(1, 1, -1)
- else:
- # Kaiser sinc filter is BigVGAN default
- self.kernel_size = int(6 * ratio // 2) * 2 if kernel_size is None else kernel_size
- self.pad = self.kernel_size // ratio - 1
- self.pad_left = self.pad * self.ratio + (self.kernel_size - self.ratio) // 2
- self.pad_right = self.pad * self.ratio + (self.kernel_size - self.ratio + 1) // 2
-
- sinc_filter = kaiser_sinc_filter1d(
- cutoff=0.5 / ratio,
- half_width=0.6 / ratio,
- kernel_size=self.kernel_size,
- )
-
- self.register_buffer("filter", sinc_filter.view(1, 1, self.kernel_size), persistent=persistent)
-
- def forward(self, x: torch.Tensor) -> torch.Tensor:
- # x expected shape: [batch_size, num_channels, hidden_dim]
- num_channels = x.shape[1]
- x = F.pad(x, (self.pad, self.pad), mode=self.padding_mode)
- low_pass_filter = self.filter.to(dtype=x.dtype, device=x.device).expand(num_channels, -1, -1)
- x = self.ratio * F.conv_transpose1d(x, low_pass_filter, stride=self.ratio, groups=num_channels)
- return x[..., self.pad_left : -self.pad_right]
-
-
-class AntiAliasAct1d(nn.Module):
- """
- Antialiasing activation for a 1D signal: upsamples, applies an activation (usually snakebeta), and then downsamples
- to avoid aliasing.
- """
-
- def __init__(
- self,
- act_fn: str | nn.Module,
- ratio: int = 2,
- kernel_size: int = 12,
- **kwargs,
- ):
- super().__init__()
- self.upsample = UpSample1d(ratio=ratio, kernel_size=kernel_size)
- if isinstance(act_fn, str):
- if act_fn == "snakebeta":
- act_fn = SnakeBeta(**kwargs)
- elif act_fn == "snake":
- act_fn = SnakeBeta(**kwargs)
- else:
- act_fn = nn.LeakyReLU(**kwargs)
- self.act = act_fn
- self.downsample = DownSample1d(ratio=ratio, kernel_size=kernel_size)
-
- def forward(self, x: torch.Tensor) -> torch.Tensor:
- x = self.upsample(x)
- x = self.act(x)
- x = self.downsample(x)
- return x
-
-
-class SnakeBeta(nn.Module):
- """
- Implements the Snake and SnakeBeta activations, which help with learning periodic patterns.
- """
-
- def __init__(
- self,
- channels: int,
- alpha: float = 1.0,
- eps: float = 1e-9,
- trainable_params: bool = True,
- logscale: bool = True,
- use_beta: bool = True,
- ):
- super().__init__()
- self.eps = eps
- self.logscale = logscale
- self.use_beta = use_beta
-
- self.alpha = nn.Parameter(torch.zeros(channels) if self.logscale else torch.ones(channels) * alpha)
- self.alpha.requires_grad = trainable_params
- if use_beta:
- self.beta = nn.Parameter(torch.zeros(channels) if self.logscale else torch.ones(channels) * alpha)
- self.beta.requires_grad = trainable_params
-
- def forward(self, hidden_states: torch.Tensor, channel_dim: int = 1) -> torch.Tensor:
- broadcast_shape = [1] * hidden_states.ndim
- broadcast_shape[channel_dim] = -1
- alpha = self.alpha.view(broadcast_shape)
- if self.use_beta:
- beta = self.beta.view(broadcast_shape)
-
- if self.logscale:
- alpha = torch.exp(alpha)
- if self.use_beta:
- beta = torch.exp(beta)
-
- amplitude = beta if self.use_beta else alpha
- hidden_states = hidden_states + (1.0 / (amplitude + self.eps)) * torch.sin(hidden_states * alpha).pow(2)
- return hidden_states
-
-
-class ResBlock(nn.Module):
- def __init__(
- self,
- channels: int,
- kernel_size: int = 3,
- stride: int = 1,
- dilations: tuple[int, ...] = (1, 3, 5),
- act_fn: str = "leaky_relu",
- leaky_relu_negative_slope: float = 0.1,
- antialias: bool = False,
- antialias_ratio: int = 2,
- antialias_kernel_size: int = 12,
- padding_mode: str = "same",
- ):
- super().__init__()
- self.dilations = dilations
-
- self.convs1 = nn.ModuleList(
- [
- nn.Conv1d(channels, channels, kernel_size, stride=stride, dilation=dilation, padding=padding_mode)
- for dilation in dilations
- ]
- )
- self.acts1 = nn.ModuleList()
- for _ in range(len(self.convs1)):
- if act_fn == "snakebeta":
- act = SnakeBeta(channels, use_beta=True)
- elif act_fn == "snake":
- act = SnakeBeta(channels, use_beta=False)
- else:
- act = nn.LeakyReLU(negative_slope=leaky_relu_negative_slope)
-
- if antialias:
- act = AntiAliasAct1d(act, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
- self.acts1.append(act)
-
- self.convs2 = nn.ModuleList(
- [
- nn.Conv1d(channels, channels, kernel_size, stride=stride, dilation=1, padding=padding_mode)
- for _ in range(len(dilations))
- ]
- )
- self.acts2 = nn.ModuleList()
- for _ in range(len(self.convs2)):
- if act_fn == "snakebeta":
- act = SnakeBeta(channels, use_beta=True)
- elif act_fn == "snake":
- act = SnakeBeta(channels, use_beta=False)
- else:
- act_fn = nn.LeakyReLU(negative_slope=leaky_relu_negative_slope)
-
- if antialias:
- act = AntiAliasAct1d(act, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
- self.acts2.append(act)
-
- def forward(self, x: torch.Tensor) -> torch.Tensor:
- for act1, conv1, act2, conv2 in zip(self.acts1, self.convs1, self.acts2, self.convs2):
- xt = act1(x)
- xt = conv1(xt)
- xt = act2(xt)
- xt = conv2(xt)
- x = x + xt
- return x
-
-
-class LTX2Vocoder(ModelMixin, ConfigMixin):
- r"""
- LTX 2.0 vocoder for converting generated mel spectrograms back to audio waveforms.
- """
-
- @register_to_config
- def __init__(
- self,
- in_channels: int = 128,
- hidden_channels: int = 1024,
- out_channels: int = 2,
- upsample_kernel_sizes: list[int] = [16, 15, 8, 4, 4],
- upsample_factors: list[int] = [6, 5, 2, 2, 2],
- resnet_kernel_sizes: list[int] = [3, 7, 11],
- resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
- act_fn: str = "leaky_relu",
- leaky_relu_negative_slope: float = 0.1,
- antialias: bool = False,
- antialias_ratio: int = 2,
- antialias_kernel_size: int = 12,
- final_act_fn: str | None = "tanh", # tanh, clamp, None
- final_bias: bool = True,
- output_sampling_rate: int = 24000,
- ):
- super().__init__()
- self.num_upsample_layers = len(upsample_kernel_sizes)
- self.resnets_per_upsample = len(resnet_kernel_sizes)
- self.out_channels = out_channels
- self.total_upsample_factor = math.prod(upsample_factors)
- self.act_fn = act_fn
- self.negative_slope = leaky_relu_negative_slope
- self.final_act_fn = final_act_fn
-
- if self.num_upsample_layers != len(upsample_factors):
- raise ValueError(
- f"`upsample_kernel_sizes` and `upsample_factors` should be lists of the same length but are length"
- f" {self.num_upsample_layers} and {len(upsample_factors)}, respectively."
- )
-
- if self.resnets_per_upsample != len(resnet_dilations):
- raise ValueError(
- f"`resnet_kernel_sizes` and `resnet_dilations` should be lists of the same length but are length"
- f" {len(self.resnets_per_upsample)} and {len(resnet_dilations)}, respectively."
- )
-
- supported_act_fns = ["snakebeta", "snake", "leaky_relu"]
- if self.act_fn not in supported_act_fns:
- raise ValueError(
- f"Unsupported activation function: {self.act_fn}. Currently supported values of `act_fn` are "
- f"{supported_act_fns}."
- )
-
- self.conv_in = nn.Conv1d(in_channels, hidden_channels, kernel_size=7, stride=1, padding=3)
-
- self.upsamplers = nn.ModuleList()
- self.resnets = nn.ModuleList()
- input_channels = hidden_channels
- for i, (stride, kernel_size) in enumerate(zip(upsample_factors, upsample_kernel_sizes)):
- output_channels = input_channels // 2
- self.upsamplers.append(
- nn.ConvTranspose1d(
- input_channels, # hidden_channels // (2 ** i)
- output_channels, # hidden_channels // (2 ** (i + 1))
- kernel_size,
- stride=stride,
- padding=(kernel_size - stride) // 2,
- )
- )
-
- for kernel_size, dilations in zip(resnet_kernel_sizes, resnet_dilations):
- self.resnets.append(
- ResBlock(
- channels=output_channels,
- kernel_size=kernel_size,
- dilations=dilations,
- act_fn=act_fn,
- leaky_relu_negative_slope=leaky_relu_negative_slope,
- antialias=antialias,
- antialias_ratio=antialias_ratio,
- antialias_kernel_size=antialias_kernel_size,
- )
- )
- input_channels = output_channels
-
- if act_fn == "snakebeta" or act_fn == "snake":
- # Always use antialiasing
- act_out = SnakeBeta(channels=output_channels, use_beta=True)
- self.act_out = AntiAliasAct1d(act_out, ratio=antialias_ratio, kernel_size=antialias_kernel_size)
- elif act_fn == "leaky_relu":
- # NOTE: does NOT use self.negative_slope, following the original code
- self.act_out = nn.LeakyReLU()
-
- self.conv_out = nn.Conv1d(output_channels, out_channels, 7, stride=1, padding=3, bias=final_bias)
-
- def forward(self, hidden_states: torch.Tensor, time_last: bool = False) -> torch.Tensor:
- r"""
- Forward pass of the vocoder.
-
- Args:
- hidden_states (`torch.Tensor`):
- Input Mel spectrogram tensor of shape `(batch_size, num_channels, time, num_mel_bins)` if `time_last`
- is `False` (the default) or shape `(batch_size, num_channels, num_mel_bins, time)` if `time_last` is
- `True`.
- time_last (`bool`, *optional*, defaults to `False`):
- Whether the last dimension of the input is the time/frame dimension or the Mel bins dimension.
-
- Returns:
- `torch.Tensor`:
- Audio waveform tensor of shape (batch_size, out_channels, audio_length)
- """
-
- # Ensure that the time/frame dimension is last
- if not time_last:
- hidden_states = hidden_states.transpose(2, 3)
- # Combine channels and frequency (mel bins) dimensions
- hidden_states = hidden_states.flatten(1, 2)
-
- hidden_states = self.conv_in(hidden_states)
-
- for i in range(self.num_upsample_layers):
- if self.act_fn == "leaky_relu":
- # Other activations are inside each upsampling block
- hidden_states = F.leaky_relu(hidden_states, negative_slope=self.negative_slope)
- hidden_states = self.upsamplers[i](hidden_states)
-
- # Run all resnets in parallel on hidden_states
- start = i * self.resnets_per_upsample
- end = (i + 1) * self.resnets_per_upsample
- resnet_outputs = torch.stack([self.resnets[j](hidden_states) for j in range(start, end)], dim=0)
-
- hidden_states = torch.mean(resnet_outputs, dim=0)
-
- hidden_states = self.act_out(hidden_states)
- hidden_states = self.conv_out(hidden_states)
- if self.final_act_fn == "tanh":
- hidden_states = torch.tanh(hidden_states)
- elif self.final_act_fn == "clamp":
- hidden_states = torch.clamp(hidden_states, -1, 1)
-
- return hidden_states
-
-
-class CausalSTFT(nn.Module):
- """
- Performs a causal short-time Fourier transform (STFT) using causal Hann windows on a waveform. The DFT bases
- multiplied by the Hann windows are pre-calculated and stored as buffers. For exact parity with training, the exact
- buffers should be loaded from the checkpoint in bfloat16.
- """
-
- def __init__(self, filter_length: int = 512, hop_length: int = 80, window_length: int = 512):
- super().__init__()
- self.hop_length = hop_length
- self.window_length = window_length
- n_freqs = filter_length // 2 + 1
-
- self.register_buffer("forward_basis", torch.zeros(n_freqs * 2, 1, filter_length), persistent=True)
- self.register_buffer("inverse_basis", torch.zeros(n_freqs * 2, 1, filter_length), persistent=True)
-
- def forward(self, waveform: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
- if waveform.ndim == 2:
- waveform = waveform.unsqueeze(1) # [B, num_channels, num_samples]
-
- left_pad = max(0, self.window_length - self.hop_length) # causal: left-only
- waveform = F.pad(waveform, (left_pad, 0))
-
- spec = F.conv1d(waveform, self.forward_basis, stride=self.hop_length, padding=0)
- n_freqs = spec.shape[1] // 2
- real, imag = spec[:, :n_freqs], spec[:, n_freqs:]
- magnitude = torch.sqrt(real**2 + imag**2)
- phase = torch.atan2(imag.float(), real.float()).to(dtype=real.dtype)
- return magnitude, phase
-
-
-class MelSTFT(nn.Module):
- """
- Calculates a causal log-mel spectrogram from a waveform. Uses a pre-calculated mel filterbank, which should be
- loaded from the checkpoint in bfloat16.
- """
-
- def __init__(
- self,
- filter_length: int = 512,
- hop_length: int = 80,
- window_length: int = 512,
- num_mel_channels: int = 64,
- ):
- super().__init__()
- self.stft_fn = CausalSTFT(filter_length, hop_length, window_length)
-
- num_freqs = filter_length // 2 + 1
- self.register_buffer("mel_basis", torch.zeros(num_mel_channels, num_freqs), persistent=True)
-
- def forward(self, waveform: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor, torch.Tensor]:
- magnitude, phase = self.stft_fn(waveform)
- energy = torch.norm(magnitude, dim=1)
- mel = torch.matmul(self.mel_basis.to(magnitude.dtype), magnitude)
- log_mel = torch.log(torch.clamp(mel, min=1e-5))
- return log_mel, magnitude, phase, energy
-
-
-class LTX2VocoderWithBWE(ModelMixin, ConfigMixin):
- """
- LTX-2.X vocoder with bandwidth extension (BWE) upsampling. The vocoder and the BWE module run in sequence, with the
- BWE module upsampling the vocoder output waveform to a higher sampling rate. The BWE module itself has the same
- architecture as the original vocoder.
- """
-
- @register_to_config
- def __init__(
- self,
- in_channels: int = 128,
- hidden_channels: int = 1536,
- out_channels: int = 2,
- upsample_kernel_sizes: list[int] = [11, 4, 4, 4, 4, 4],
- upsample_factors: list[int] = [5, 2, 2, 2, 2, 2],
- resnet_kernel_sizes: list[int] = [3, 7, 11],
- resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
- act_fn: str = "snakebeta",
- leaky_relu_negative_slope: float = 0.1,
- antialias: bool = True,
- antialias_ratio: int = 2,
- antialias_kernel_size: int = 12,
- final_act_fn: str | None = None,
- final_bias: bool = False,
- bwe_in_channels: int = 128,
- bwe_hidden_channels: int = 512,
- bwe_out_channels: int = 2,
- bwe_upsample_kernel_sizes: list[int] = [12, 11, 4, 4, 4],
- bwe_upsample_factors: list[int] = [6, 5, 2, 2, 2],
- bwe_resnet_kernel_sizes: list[int] = [3, 7, 11],
- bwe_resnet_dilations: list[list[int]] = [[1, 3, 5], [1, 3, 5], [1, 3, 5]],
- bwe_act_fn: str = "snakebeta",
- bwe_leaky_relu_negative_slope: float = 0.1,
- bwe_antialias: bool = True,
- bwe_antialias_ratio: int = 2,
- bwe_antialias_kernel_size: int = 12,
- bwe_final_act_fn: str | None = None,
- bwe_final_bias: bool = False,
- filter_length: int = 512,
- hop_length: int = 80,
- window_length: int = 512,
- num_mel_channels: int = 64,
- input_sampling_rate: int = 16000,
- output_sampling_rate: int = 48000,
- ):
- super().__init__()
-
- self.vocoder = LTX2Vocoder(
- in_channels=in_channels,
- hidden_channels=hidden_channels,
- out_channels=out_channels,
- upsample_kernel_sizes=upsample_kernel_sizes,
- upsample_factors=upsample_factors,
- resnet_kernel_sizes=resnet_kernel_sizes,
- resnet_dilations=resnet_dilations,
- act_fn=act_fn,
- leaky_relu_negative_slope=leaky_relu_negative_slope,
- antialias=antialias,
- antialias_ratio=antialias_ratio,
- antialias_kernel_size=antialias_kernel_size,
- final_act_fn=final_act_fn,
- final_bias=final_bias,
- output_sampling_rate=input_sampling_rate,
- )
- self.bwe_generator = LTX2Vocoder(
- in_channels=bwe_in_channels,
- hidden_channels=bwe_hidden_channels,
- out_channels=bwe_out_channels,
- upsample_kernel_sizes=bwe_upsample_kernel_sizes,
- upsample_factors=bwe_upsample_factors,
- resnet_kernel_sizes=bwe_resnet_kernel_sizes,
- resnet_dilations=bwe_resnet_dilations,
- act_fn=bwe_act_fn,
- leaky_relu_negative_slope=bwe_leaky_relu_negative_slope,
- antialias=bwe_antialias,
- antialias_ratio=bwe_antialias_ratio,
- antialias_kernel_size=bwe_antialias_kernel_size,
- final_act_fn=bwe_final_act_fn,
- final_bias=bwe_final_bias,
- output_sampling_rate=output_sampling_rate,
+# Copyright 2026 Lightricks and The HuggingFace Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from ...models.autoencoders.vocoder_ltx2 import LTX2Vocoder as _LTX2Vocoder
+from ...models.autoencoders.vocoder_ltx2 import LTX2VocoderWithBWE as _LTX2VocoderWithBWE
+from ...utils import deprecate
+
+
+# Deprecated aliases kept for backward compatibility. The warning is raised from `__new__` rather than `__init__` so
+# that the parent's `__init__` signature, which `ConfigMixin` inspects when loading a config, stays intact.
+class LTX2Vocoder(_LTX2Vocoder):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "LTX2Vocoder",
+ "1.0.0",
+ "Importing `LTX2Vocoder` from `diffusers.pipelines.ltx2.vocoder` is deprecated. "
+ "Import it with `from diffusers import LTX2Vocoder` instead.",
)
+ return super().__new__(cls)
- self.mel_stft = MelSTFT(
- filter_length=filter_length,
- hop_length=hop_length,
- window_length=window_length,
- num_mel_channels=num_mel_channels,
- )
- self.resampler = UpSample1d(
- ratio=output_sampling_rate // input_sampling_rate,
- window_type="hann",
- persistent=False,
+class LTX2VocoderWithBWE(_LTX2VocoderWithBWE):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "LTX2VocoderWithBWE",
+ "1.0.0",
+ "Importing `LTX2VocoderWithBWE` from `diffusers.pipelines.ltx2.vocoder` is deprecated. "
+ "Import it with `from diffusers import LTX2VocoderWithBWE` instead.",
)
-
- def forward(self, mel_spec: torch.Tensor) -> torch.Tensor:
- # 1. Run stage 1 vocoder to get low sampling rate waveform
- x = self.vocoder(mel_spec)
- batch_size, num_channels, num_samples = x.shape
-
- # Pad to exact multiple of hop_length for exact mel frame count
- remainder = num_samples % self.config.hop_length
- if remainder != 0:
- x = F.pad(x, (0, self.hop_length - remainder))
-
- # 2. Compute mel spectrogram on vocoder output
- mel, _, _, _ = self.mel_stft(x.flatten(0, 1))
- mel = mel.unflatten(0, (-1, num_channels))
-
- # 3. Run bandwidth extender (BWE) on new mel spectrogram
- mel_for_bwe = mel.transpose(2, 3) # [B, C, num_mel_bins, num_frames] --> [B, C, num_frames, num_mel_bins]
- residual = self.bwe_generator(mel_for_bwe)
-
- # 4. Residual connection with resampler
- skip = self.resampler(x)
- waveform = torch.clamp(residual + skip, -1, 1)
- output_samples = num_samples * self.config.output_sampling_rate // self.config.input_sampling_rate
- waveform = waveform[..., :output_samples]
- return waveform
+ return super().__new__(cls)
diff --git a/src/diffusers/pipelines/stable_diffusion/convert_from_ckpt.py b/src/diffusers/pipelines/stable_diffusion/convert_from_ckpt.py
index 0c8fd842fcba..820ffe4e121f 100644
--- a/src/diffusers/pipelines/stable_diffusion/convert_from_ckpt.py
+++ b/src/diffusers/pipelines/stable_diffusion/convert_from_ckpt.py
@@ -39,6 +39,7 @@
PriorTransformer,
UNet2DConditionModel,
)
+from ...models.condition_embedders import StableUnCLIPImageNormalizer
from ...schedulers import (
DDIMScheduler,
DDPMScheduler,
@@ -57,7 +58,6 @@
from ..latent_diffusion.pipeline_latent_diffusion import LDMBertConfig, LDMBertModel
from ..pipeline_utils import DiffusionPipeline
from .safety_checker import StableDiffusionSafetyChecker
-from .stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
if is_accelerate_available():
diff --git a/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip.py b/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip.py
index 1d6feec05846..a88c83a088d6 100644
--- a/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip.py
+++ b/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip.py
@@ -22,6 +22,7 @@
from ...image_processor import VaeImageProcessor
from ...loaders import StableDiffusionLoraLoaderMixin, TextualInversionLoaderMixin
from ...models import AutoencoderKL, PriorTransformer, UNet2DConditionModel
+from ...models.condition_embedders import StableUnCLIPImageNormalizer
from ...models.embeddings import get_timestep_embedding
from ...models.lora import adjust_lora_scale_text_encoder
from ...schedulers import KarrasDiffusionSchedulers
@@ -36,7 +37,6 @@
)
from ...utils.torch_utils import randn_tensor
from ..pipeline_utils import DiffusionPipeline, ImagePipelineOutput, StableDiffusionMixin
-from .stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip_img2img.py b/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip_img2img.py
index c560b411620e..4cccbcc29172 100644
--- a/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip_img2img.py
+++ b/src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip_img2img.py
@@ -22,6 +22,7 @@
from ...image_processor import VaeImageProcessor
from ...loaders import StableDiffusionLoraLoaderMixin, TextualInversionLoaderMixin
from ...models import AutoencoderKL, UNet2DConditionModel
+from ...models.condition_embedders import StableUnCLIPImageNormalizer
from ...models.embeddings import get_timestep_embedding
from ...models.lora import adjust_lora_scale_text_encoder
from ...schedulers import KarrasDiffusionSchedulers
@@ -36,7 +37,6 @@
)
from ...utils.torch_utils import randn_tensor
from ..pipeline_utils import DiffusionPipeline, ImagePipelineOutput, StableDiffusionMixin
-from .stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
if is_torch_xla_available():
diff --git a/src/diffusers/pipelines/stable_diffusion/stable_unclip_image_normalizer.py b/src/diffusers/pipelines/stable_diffusion/stable_unclip_image_normalizer.py
index 1a29bc9bb63b..646d4cf8bbb3 100644
--- a/src/diffusers/pipelines/stable_diffusion/stable_unclip_image_normalizer.py
+++ b/src/diffusers/pipelines/stable_diffusion/stable_unclip_image_normalizer.py
@@ -12,44 +12,20 @@
# See the License for the specific language governing permissions and
# limitations under the License.
-import torch
-from torch import nn
-
-from ...configuration_utils import ConfigMixin, register_to_config
-from ...models.modeling_utils import ModelMixin
-
-
-class StableUnCLIPImageNormalizer(ModelMixin, ConfigMixin):
- """
- This class is used to hold the mean and standard deviation of the CLIP embedder used in stable unCLIP.
-
- It is used to normalize the image embeddings before the noise is applied and un-normalize the noised image
- embeddings.
- """
-
- @register_to_config
- def __init__(
- self,
- embedding_dim: int = 768,
- ):
- super().__init__()
-
- self.mean = nn.Parameter(torch.zeros(1, embedding_dim))
- self.std = nn.Parameter(torch.ones(1, embedding_dim))
-
- def to(
- self,
- torch_device: str | torch.device | None = None,
- torch_dtype: torch.dtype | None = None,
- ):
- self.mean = nn.Parameter(self.mean.to(torch_device).to(torch_dtype))
- self.std = nn.Parameter(self.std.to(torch_device).to(torch_dtype))
- return self
-
- def scale(self, embeds):
- embeds = (embeds - self.mean) * 1.0 / self.std
- return embeds
-
- def unscale(self, embeds):
- embeds = (embeds * self.std) + self.mean
- return embeds
+from ...models.condition_embedders.condition_embedder_stable_unclip import (
+ StableUnCLIPImageNormalizer as _StableUnCLIPImageNormalizer,
+)
+from ...utils import deprecate
+
+
+# Deprecated alias kept for backward compatibility. The warning is raised from `__new__` rather than `__init__` so
+# that the parent's `__init__` signature, which `ConfigMixin` inspects when loading a config, stays intact.
+class StableUnCLIPImageNormalizer(_StableUnCLIPImageNormalizer):
+ def __new__(cls, *args, **kwargs):
+ deprecate(
+ "StableUnCLIPImageNormalizer",
+ "1.0.0",
+ "Importing `StableUnCLIPImageNormalizer` from `diffusers.pipelines.stable_diffusion.stable_unclip_image_normalizer` is deprecated. "
+ "Import it with `from diffusers import StableUnCLIPImageNormalizer` instead.",
+ )
+ return super().__new__(cls)
diff --git a/src/diffusers/utils/deprecation_utils.py b/src/diffusers/utils/deprecation_utils.py
index 48b427d9e1ff..a06fafbafccf 100644
--- a/src/diffusers/utils/deprecation_utils.py
+++ b/src/diffusers/utils/deprecation_utils.py
@@ -72,15 +72,21 @@ def _maybe_remap_transformers_class(class_name: str) -> str | None:
# reference them as `[, ]`, so they are resolved to the top-level `diffusers` export
# instead of the deprecated alias left in the pipeline folder.
_RELOCATED_PIPELINE_CLASSES = {
+ ("ace_step", "AceStepAudioTokenDetokenizer"),
+ ("ace_step", "AceStepAudioTokenizer"),
("ace_step", "AceStepConditionEncoder"),
("audioldm2", "AudioLDM2ProjectionModel"),
+ ("audioldm2", "AudioLDM2UNet2DConditionModel"),
("flux", "ReduxImageEncoder"),
("ltx", "LTXLatentUpsamplerModel"),
("ltx2", "LTX2LatentUpsamplerModel"),
("ltx2", "LTX2TextConnectors"),
+ ("ltx2", "LTX2Vocoder"),
+ ("ltx2", "LTX2VocoderWithBWE"),
("stable_audio", "StableAudioProjectionModel"),
("stable_audio_3", "StableAudio3DurationEmbedder"),
("stable_diffusion", "CLIPImageProjection"),
+ ("stable_diffusion", "StableUnCLIPImageNormalizer"),
}
diff --git a/src/diffusers/utils/dummy_pt_objects.py b/src/diffusers/utils/dummy_pt_objects.py
index 5884b302c8ae..e11524497db0 100644
--- a/src/diffusers/utils/dummy_pt_objects.py
+++ b/src/diffusers/utils/dummy_pt_objects.py
@@ -439,6 +439,36 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch"])
+class AceStepAudioTokenDetokenizer(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
+class AceStepAudioTokenizer(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
class AceStepConditionEncoder(metaclass=DummyObject):
_backends = ["torch"]
@@ -574,6 +604,21 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch"])
+class AudioLDM2UNet2DConditionModel(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
class AuraFlowTransformer2DModel(metaclass=DummyObject):
_backends = ["torch"]
@@ -1969,6 +2014,36 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch"])
+class LTX2Vocoder(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
+class LTX2VocoderWithBWE(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
class LTXLatentUpsamplerModel(metaclass=DummyObject):
_backends = ["torch"]
@@ -2689,6 +2764,21 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch"])
+class StableUnCLIPImageNormalizer(metaclass=DummyObject):
+ _backends = ["torch"]
+
+ def __init__(self, *args, **kwargs):
+ requires_backends(self, ["torch"])
+
+ @classmethod
+ def from_config(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+ @classmethod
+ def from_pretrained(cls, *args, **kwargs):
+ requires_backends(cls, ["torch"])
+
+
class T2IAdapter(metaclass=DummyObject):
_backends = ["torch"]
diff --git a/src/diffusers/utils/dummy_torch_and_transformers_objects.py b/src/diffusers/utils/dummy_torch_and_transformers_objects.py
index 2ef88ff59bc2..c5f61f870a6d 100644
--- a/src/diffusers/utils/dummy_torch_and_transformers_objects.py
+++ b/src/diffusers/utils/dummy_torch_and_transformers_objects.py
@@ -1397,36 +1397,6 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch", "transformers"])
-class AceStepAudioTokenDetokenizer(metaclass=DummyObject):
- _backends = ["torch", "transformers"]
-
- def __init__(self, *args, **kwargs):
- requires_backends(self, ["torch", "transformers"])
-
- @classmethod
- def from_config(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
- @classmethod
- def from_pretrained(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
-
-class AceStepAudioTokenizer(metaclass=DummyObject):
- _backends = ["torch", "transformers"]
-
- def __init__(self, *args, **kwargs):
- requires_backends(self, ["torch", "transformers"])
-
- @classmethod
- def from_config(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
- @classmethod
- def from_pretrained(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
-
class AceStepPipeline(metaclass=DummyObject):
_backends = ["torch", "transformers"]
@@ -1682,21 +1652,6 @@ def from_pretrained(cls, *args, **kwargs):
requires_backends(cls, ["torch", "transformers"])
-class AudioLDM2UNet2DConditionModel(metaclass=DummyObject):
- _backends = ["torch", "transformers"]
-
- def __init__(self, *args, **kwargs):
- requires_backends(self, ["torch", "transformers"])
-
- @classmethod
- def from_config(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
- @classmethod
- def from_pretrained(cls, *args, **kwargs):
- requires_backends(cls, ["torch", "transformers"])
-
-
class AudioLDMPipeline(metaclass=DummyObject):
_backends = ["torch", "transformers"]
diff --git a/tests/models/test_relocated_class_loading.py b/tests/models/test_relocated_class_loading.py
index f232ce813f9d..fe77f0434643 100644
--- a/tests/models/test_relocated_class_loading.py
+++ b/tests/models/test_relocated_class_loading.py
@@ -29,6 +29,8 @@
# (pipeline folder, deprecated module path, class name, init kwargs)
RELOCATED_CLASSES = [
+ ("ace_step", "diffusers.pipelines.ace_step.modeling_ace_step", "AceStepAudioTokenDetokenizer", {}),
+ ("ace_step", "diffusers.pipelines.ace_step.modeling_ace_step", "AceStepAudioTokenizer", {}),
("ace_step", "diffusers.pipelines.ace_step.modeling_ace_step", "AceStepConditionEncoder", {}),
(
"audioldm2",
@@ -36,10 +38,26 @@
"AudioLDM2ProjectionModel",
{"text_encoder_dim": 8, "text_encoder_1_dim": 8, "langauge_model_dim": 16},
),
+ (
+ "audioldm2",
+ "diffusers.pipelines.audioldm2.modeling_audioldm2",
+ "AudioLDM2UNet2DConditionModel",
+ {
+ "block_out_channels": (8, 16),
+ "layers_per_block": 1,
+ "norm_num_groups": 8,
+ "down_block_types": ("DownBlock2D", "CrossAttnDownBlock2D"),
+ "up_block_types": ("CrossAttnUpBlock2D", "UpBlock2D"),
+ "cross_attention_dim": ([None, 8], [None, 8]),
+ "attention_head_dim": 2,
+ },
+ ),
("flux", "diffusers.pipelines.flux.modeling_flux", "ReduxImageEncoder", {}),
("ltx", "diffusers.pipelines.ltx.modeling_latent_upsampler", "LTXLatentUpsamplerModel", {}),
("ltx2", "diffusers.pipelines.ltx2.latent_upsampler", "LTX2LatentUpsamplerModel", {}),
("ltx2", "diffusers.pipelines.ltx2.connectors", "LTX2TextConnectors", {}),
+ ("ltx2", "diffusers.pipelines.ltx2.vocoder", "LTX2Vocoder", {}),
+ ("ltx2", "diffusers.pipelines.ltx2.vocoder", "LTX2VocoderWithBWE", {}),
(
"stable_audio",
"diffusers.pipelines.stable_audio.modeling_stable_audio",
@@ -53,9 +71,33 @@
{},
),
("stable_diffusion", "diffusers.pipelines.stable_diffusion.clip_image_project_model", "CLIPImageProjection", {}),
+ (
+ "stable_diffusion",
+ "diffusers.pipelines.stable_diffusion.stable_unclip_image_normalizer",
+ "StableUnCLIPImageNormalizer",
+ {},
+ ),
]
IDS = [name for _, _, name, _ in RELOCATED_CLASSES]
+# Relocated symbols that are not top-level `diffusers` exports and so are not in `_RELOCATED_PIPELINE_CLASSES`:
+# (deprecated module path, new module path, symbol name, call kwargs)
+RELOCATED_HELPERS = [
+ (
+ "diffusers.pipelines.ace_step.modeling_ace_step",
+ "diffusers.models.condition_embedders.condition_embedder_ace_step",
+ "AceStepLyricEncoder",
+ {},
+ ),
+ (
+ "diffusers.pipelines.ace_step.modeling_ace_step",
+ "diffusers.models.condition_embedders.condition_embedder_ace_step",
+ "AceStepTimbreEncoder",
+ {},
+ ),
+]
+HELPER_IDS = [name for _, _, name, _ in RELOCATED_HELPERS]
+
def _future_warnings(fn):
with warnings.catch_warnings(record=True) as caught:
@@ -83,3 +125,16 @@ def test_model_index_entry_resolves_to_new_class(folder, module, name, kwargs):
class_obj, _ = get_class_obj_and_candidates(folder, name, ALL_IMPORTABLE_CLASSES, pipelines, True)
assert class_obj is new_cls
assert simple_get_class_obj(folder, name) is new_cls
+
+
+@pytest.mark.parametrize("module, new_module, name, kwargs", RELOCATED_HELPERS, ids=HELPER_IDS)
+def test_deprecated_helper_path_warns(module, new_module, name, kwargs):
+ new_obj = getattr(importlib.import_module(new_module), name)
+ old_obj = getattr(importlib.import_module(module), name)
+ if isinstance(old_obj, type):
+ assert issubclass(old_obj, new_obj)
+
+ with torch.device("meta"):
+ assert not _future_warnings(lambda: new_obj(**kwargs))
+ messages = _future_warnings(lambda: old_obj(**kwargs))
+ assert any(name in message and "deprecated" in message for message in messages), messages
diff --git a/tests/pipelines/ltx2/testing_utils.py b/tests/pipelines/ltx2/testing_utils.py
index 1e3a2e225ebf..a45ae626e052 100644
--- a/tests/pipelines/ltx2/testing_utils.py
+++ b/tests/pipelines/ltx2/testing_utils.py
@@ -29,12 +29,12 @@
AutoencoderKLLTX2Video,
FlowMatchEulerDiscreteScheduler,
LTX2VideoTransformer3DModel,
+ LTX2Vocoder,
LTXEulerAncestralRFScheduler,
)
from diffusers.models.condition_embedders import LTX2TextConnectors
from diffusers.models.latent_upscaler import LTX2LatentUpsamplerModel
from diffusers.pipelines.ltx2 import LTX2DurationHead
-from diffusers.pipelines.ltx2.vocoder import LTX2Vocoder
from ...testing_utils import torch_device
from ..testing_utils import (
diff --git a/tests/pipelines/shap_e/__init__.py b/tests/pipelines/shap_e/__init__.py
deleted file mode 100644
index e69de29bb2d1..000000000000
diff --git a/tests/pipelines/shap_e/test_shap_e.py b/tests/pipelines/shap_e/test_shap_e.py
deleted file mode 100644
index aa8cc23aa8e3..000000000000
--- a/tests/pipelines/shap_e/test_shap_e.py
+++ /dev/null
@@ -1,260 +0,0 @@
-# Copyright 2026 HuggingFace Inc.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-import gc
-
-import numpy as np
-import pytest
-import torch
-from transformers import CLIPTextConfig, CLIPTextModelWithProjection, CLIPTokenizer
-
-from diffusers import HeunDiscreteScheduler, PriorTransformer, ShapEPipeline
-from diffusers.pipelines.shap_e import ShapERenderer
-
-from ...testing_utils import (
- backend_empty_cache,
- load_numpy,
- nightly,
- require_torch_accelerator,
- torch_device,
-)
-from ..testing_utils import (
- BasePipelineTesterConfig,
- MemoryTesterMixin,
- PipelineTesterMixin,
- assert_mean_pixel_difference,
-)
-
-
-class ShapEPipelineTesterConfig(BasePipelineTesterConfig):
- pipeline_class = ShapEPipeline
- required_input_params_in_call_signature = frozenset(["prompt"])
- batch_input_params = frozenset(["prompt"])
- # Shap-E renders a 3D asset, so `guidance_scale` and `frame_size` join the canonical optional parameters.
- optional_input_params = frozenset(
- [
- "num_inference_steps",
- "num_images_per_prompt",
- "generator",
- "latents",
- "guidance_scale",
- "frame_size",
- "output_type",
- "return_dict",
- ]
- )
- # The dummy inputs request latents, so a sample is the flattened latent grid rather than an image.
- output_shape = (32, 16)
-
- @property
- def text_embedder_hidden_size(self):
- return 16
-
- @property
- def time_input_dim(self):
- return 16
-
- @property
- def time_embed_dim(self):
- return self.time_input_dim * 4
-
- @property
- def renderer_dim(self):
- return 8
-
- @property
- def dummy_tokenizer(self):
- tokenizer = CLIPTokenizer.from_pretrained("hf-internal-testing/tiny-random-clip")
- return tokenizer
-
- @property
- def dummy_text_encoder(self):
- torch.manual_seed(0)
- config = CLIPTextConfig(
- bos_token_id=0,
- eos_token_id=2,
- hidden_size=self.text_embedder_hidden_size,
- projection_dim=self.text_embedder_hidden_size,
- intermediate_size=37,
- layer_norm_eps=1e-05,
- num_attention_heads=4,
- num_hidden_layers=5,
- pad_token_id=1,
- vocab_size=1000,
- )
- return CLIPTextModelWithProjection(config)
-
- @property
- def dummy_prior(self):
- torch.manual_seed(0)
-
- model_kwargs = {
- "num_attention_heads": 2,
- "attention_head_dim": 16,
- "embedding_dim": self.time_input_dim,
- "num_embeddings": 32,
- "embedding_proj_dim": self.text_embedder_hidden_size,
- "time_embed_dim": self.time_embed_dim,
- "num_layers": 1,
- "clip_embed_dim": self.time_input_dim * 2,
- "additional_embeddings": 0,
- "time_embed_act_fn": "gelu",
- "norm_in_type": "layer",
- "encoder_hid_proj_type": None,
- "added_emb_type": None,
- }
-
- model = PriorTransformer(**model_kwargs)
- return model
-
- @property
- def dummy_renderer(self):
- torch.manual_seed(0)
-
- model_kwargs = {
- "param_shapes": (
- (self.renderer_dim, 93),
- (self.renderer_dim, 8),
- ),
- "d_latent": self.time_input_dim,
- "d_hidden": self.renderer_dim,
- "n_output": 12,
- "background": (
- 0.1,
- 0.1,
- 0.1,
- ),
- }
- model = ShapERenderer(**model_kwargs)
- return model
-
- def get_dummy_components(self):
- prior = self.dummy_prior
- text_encoder = self.dummy_text_encoder
- tokenizer = self.dummy_tokenizer
- shap_e_renderer = self.dummy_renderer
-
- scheduler = HeunDiscreteScheduler(
- beta_schedule="exp",
- num_train_timesteps=1024,
- prediction_type="sample",
- use_karras_sigmas=True,
- clip_sample=True,
- clip_sample_range=1.0,
- )
- return {
- "prior": prior,
- "text_encoder": text_encoder,
- "tokenizer": tokenizer,
- "shap_e_renderer": shap_e_renderer,
- "scheduler": scheduler,
- }
-
- def get_dummy_inputs(self):
- return {
- "prompt": "horse",
- "generator": self.get_generator(0),
- "num_inference_steps": 1,
- "frame_size": 32,
- "output_type": "latent",
- }
-
-
-class TestShapEPipeline(ShapEPipelineTesterConfig, PipelineTesterMixin):
- def test_shap_e(self):
- pipe = self.get_pipeline().to(torch_device)
-
- output = pipe(**self.get_dummy_inputs())
- image = output.images[0]
- image = image.cpu().numpy()
- image_slice = image[-3:, -3:]
-
- assert image.shape == self.output_shape
-
- expected_slice = np.array([-1.0000, -0.6097, 1.0000, -0.9113, -0.6667, 0.8234, -0.7639, -0.2809, 0.6456])
- assert np.abs(image_slice.flatten() - expected_slice).max() < 1e-2
-
- def test_inference_batch_consistent(self):
- # NOTE: Larger batch sizes cause this test to timeout, only test on smaller batches
- super().test_inference_batch_consistent(batch_sizes=[1, 2])
-
- def test_inference_batch_single_identical(self):
- super().test_inference_batch_single_identical(batch_size=2, expected_max_diff=6e-3)
-
- def test_num_images_per_prompt(self):
- # The base test sweeps batch size x images-per-prompt; rendering makes that too slow here, so check the
- # single interesting combination.
- pipe = self.get_pipeline().to(torch_device)
-
- batch_size = 1
- num_images_per_prompt = 2
-
- inputs = self.get_dummy_inputs()
- for key in inputs.keys():
- if key in self.batch_input_params:
- inputs[key] = batch_size * [inputs[key]]
-
- images = pipe(**inputs, num_images_per_prompt=num_images_per_prompt)[0]
-
- assert images.shape[0] == batch_size * num_images_per_prompt
-
- def test_save_load_local(self, tmp_path, base_pipe_output):
- super().test_save_load_local(tmp_path, base_pipe_output, expected_max_difference=5e-3)
-
-
-class TestShapEPipelineMemory(ShapEPipelineTesterConfig, MemoryTesterMixin):
- """Memory optimization tests (CPU offload, group offload, layerwise casting) for the Shap-E pipeline."""
-
- @pytest.mark.skip("Key error is raised with accelerate")
- def test_sequential_cpu_offload_forward_pass(self):
- pass
-
-
-@nightly
-@require_torch_accelerator
-class TestShapEPipelineIntegration:
- @pytest.fixture(autouse=True)
- def cleanup(self):
- # clean up the VRAM before and after each test
- gc.collect()
- backend_empty_cache(torch_device)
- yield
- gc.collect()
- backend_empty_cache(torch_device)
-
- def test_shap_e(self):
- expected_image = load_numpy(
- "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main"
- "/shap_e/test_shap_e_np_out.npy"
- )
- pipe = ShapEPipeline.from_pretrained("openai/shap-e")
- pipe = pipe.to(torch_device)
- pipe.set_progress_bar_config(disable=None)
-
- generator = torch.Generator(device=torch_device).manual_seed(0)
-
- images = pipe(
- "a shark",
- generator=generator,
- guidance_scale=15.0,
- num_inference_steps=64,
- frame_size=64,
- output_type="np",
- ).images[0]
-
- assert images.shape == (20, 64, 64, 3)
-
- assert_mean_pixel_difference(images, expected_image)
diff --git a/tests/pipelines/shap_e/test_shap_e_img2img.py b/tests/pipelines/shap_e/test_shap_e_img2img.py
deleted file mode 100644
index bab08826d170..000000000000
--- a/tests/pipelines/shap_e/test_shap_e_img2img.py
+++ /dev/null
@@ -1,276 +0,0 @@
-# Copyright 2026 HuggingFace Inc.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-import gc
-import random
-
-import numpy as np
-import pytest
-import torch
-from transformers import CLIPImageProcessor, CLIPVisionConfig, CLIPVisionModel
-
-from diffusers import HeunDiscreteScheduler, PriorTransformer, ShapEImg2ImgPipeline
-from diffusers.pipelines.shap_e import ShapERenderer
-
-from ...testing_utils import (
- backend_empty_cache,
- floats_tensor,
- load_image,
- load_numpy,
- nightly,
- require_torch_accelerator,
- torch_device,
-)
-from ..testing_utils import (
- BasePipelineTesterConfig,
- MemoryTesterMixin,
- PipelineTesterMixin,
- assert_mean_pixel_difference,
-)
-
-
-class ShapEImg2ImgPipelineTesterConfig(BasePipelineTesterConfig):
- pipeline_class = ShapEImg2ImgPipeline
- required_input_params_in_call_signature = frozenset(["image"])
- batch_input_params = frozenset(["image"])
- # Shap-E renders a 3D asset, so `guidance_scale` and `frame_size` join the canonical optional parameters.
- optional_input_params = frozenset(
- [
- "num_inference_steps",
- "num_images_per_prompt",
- "generator",
- "latents",
- "guidance_scale",
- "frame_size",
- "output_type",
- "return_dict",
- ]
- )
- # The dummy inputs request latents, so a sample is the flattened latent grid rather than an image.
- output_shape = (32, 16)
-
- @property
- def text_embedder_hidden_size(self):
- return 16
-
- @property
- def time_input_dim(self):
- return 16
-
- @property
- def time_embed_dim(self):
- return self.time_input_dim * 4
-
- @property
- def renderer_dim(self):
- return 8
-
- @property
- def dummy_image_encoder(self):
- torch.manual_seed(0)
- config = CLIPVisionConfig(
- hidden_size=self.text_embedder_hidden_size,
- image_size=32,
- projection_dim=self.text_embedder_hidden_size,
- intermediate_size=24,
- num_attention_heads=2,
- num_channels=3,
- num_hidden_layers=5,
- patch_size=1,
- )
-
- model = CLIPVisionModel(config)
- return model
-
- @property
- def dummy_image_processor(self):
- image_processor = CLIPImageProcessor(
- crop_size=224,
- do_center_crop=True,
- do_normalize=True,
- do_resize=True,
- image_mean=[0.48145466, 0.4578275, 0.40821073],
- image_std=[0.26862954, 0.26130258, 0.27577711],
- resample=3,
- size=224,
- )
-
- return image_processor
-
- @property
- def dummy_prior(self):
- torch.manual_seed(0)
-
- model_kwargs = {
- "num_attention_heads": 2,
- "attention_head_dim": 16,
- "embedding_dim": self.time_input_dim,
- "num_embeddings": 32,
- "embedding_proj_dim": self.text_embedder_hidden_size,
- "time_embed_dim": self.time_embed_dim,
- "num_layers": 1,
- "clip_embed_dim": self.time_input_dim * 2,
- "additional_embeddings": 0,
- "time_embed_act_fn": "gelu",
- "norm_in_type": "layer",
- "embedding_proj_norm_type": "layer",
- "encoder_hid_proj_type": None,
- "added_emb_type": None,
- }
-
- model = PriorTransformer(**model_kwargs)
- return model
-
- @property
- def dummy_renderer(self):
- torch.manual_seed(0)
-
- model_kwargs = {
- "param_shapes": (
- (self.renderer_dim, 93),
- (self.renderer_dim, 8),
- ),
- "d_latent": self.time_input_dim,
- "d_hidden": self.renderer_dim,
- "n_output": 12,
- "background": (
- 0.1,
- 0.1,
- 0.1,
- ),
- }
- model = ShapERenderer(**model_kwargs)
- return model
-
- def get_dummy_components(self):
- prior = self.dummy_prior
- image_encoder = self.dummy_image_encoder
- image_processor = self.dummy_image_processor
- shap_e_renderer = self.dummy_renderer
-
- scheduler = HeunDiscreteScheduler(
- beta_schedule="exp",
- num_train_timesteps=1024,
- prediction_type="sample",
- use_karras_sigmas=True,
- clip_sample=True,
- clip_sample_range=1.0,
- )
- return {
- "prior": prior,
- "image_encoder": image_encoder,
- "image_processor": image_processor,
- "shap_e_renderer": shap_e_renderer,
- "scheduler": scheduler,
- }
-
- def get_dummy_inputs(self):
- input_image = floats_tensor((1, 3, 32, 32), rng=random.Random(0)).to(torch_device)
- return {
- "image": input_image,
- "generator": self.get_generator(0),
- "num_inference_steps": 1,
- "frame_size": 32,
- "output_type": "latent",
- }
-
-
-class TestShapEImg2ImgPipeline(ShapEImg2ImgPipelineTesterConfig, PipelineTesterMixin):
- def test_shap_e(self):
- pipe = self.get_pipeline().to(torch_device)
-
- output = pipe(**self.get_dummy_inputs())
- image = output.images[0]
- image_slice = image[-3:, -3:].cpu().numpy()
-
- assert image.shape == self.output_shape
-
- expected_slice = np.array(
- [-1.0, -0.08255208, 1.0, -0.99469435, -0.19953543, 0.99999994, -0.9133135, 0.24063873, 0.8238962]
- )
-
- assert np.abs(image_slice.flatten() - expected_slice).max() < 1e-2
-
- def test_inference_batch_single_identical(self):
- super().test_inference_batch_single_identical(batch_size=2, expected_max_diff=6e-3)
-
- def test_num_images_per_prompt(self):
- # The base test sweeps batch size x images-per-prompt; rendering makes that too slow here, so check the
- # single interesting combination.
- pipe = self.get_pipeline().to(torch_device)
-
- batch_size = 1
- num_images_per_prompt = 2
-
- inputs = self.get_dummy_inputs()
- for key in inputs.keys():
- if key in self.batch_input_params:
- inputs[key] = batch_size * [inputs[key]]
-
- images = pipe(**inputs, num_images_per_prompt=num_images_per_prompt)[0]
-
- assert images.shape[0] == batch_size * num_images_per_prompt
-
- def test_save_load_local(self, tmp_path, base_pipe_output):
- super().test_save_load_local(tmp_path, base_pipe_output, expected_max_difference=5e-3)
-
-
-class TestShapEImg2ImgPipelineMemory(ShapEImg2ImgPipelineTesterConfig, MemoryTesterMixin):
- """Memory optimization tests (CPU offload, group offload, layerwise casting) for the Shap-E img2img pipeline."""
-
- @pytest.mark.skip("Key error is raised with accelerate")
- def test_sequential_cpu_offload_forward_pass(self):
- pass
-
-
-@nightly
-@require_torch_accelerator
-class TestShapEImg2ImgPipelineIntegration:
- @pytest.fixture(autouse=True)
- def cleanup(self):
- # clean up the VRAM before and after each test
- gc.collect()
- backend_empty_cache(torch_device)
- yield
- gc.collect()
- backend_empty_cache(torch_device)
-
- def test_shap_e_img2img(self):
- input_image = load_image(
- "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/shap_e/corgi.png"
- )
- expected_image = load_numpy(
- "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main"
- "/shap_e/test_shap_e_img2img_out.npy"
- )
- pipe = ShapEImg2ImgPipeline.from_pretrained("openai/shap-e-img2img")
- pipe = pipe.to(torch_device)
- pipe.set_progress_bar_config(disable=None)
-
- generator = torch.Generator(device=torch_device).manual_seed(0)
-
- images = pipe(
- input_image,
- generator=generator,
- guidance_scale=3.0,
- num_inference_steps=64,
- frame_size=64,
- output_type="np",
- ).images[0]
-
- assert images.shape == (20, 64, 64, 3)
-
- assert_mean_pixel_difference(images, expected_image)
diff --git a/tests/pipelines/stable_unclip/test_stable_unclip.py b/tests/pipelines/stable_unclip/test_stable_unclip.py
index befd4e2bf192..e78223c7899d 100644
--- a/tests/pipelines/stable_unclip/test_stable_unclip.py
+++ b/tests/pipelines/stable_unclip/test_stable_unclip.py
@@ -9,10 +9,10 @@
DDIMScheduler,
DDPMScheduler,
PriorTransformer,
+ StableUnCLIPImageNormalizer,
StableUnCLIPPipeline,
UNet2DConditionModel,
)
-from diffusers.pipelines.stable_diffusion.stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
from ...testing_utils import (
backend_empty_cache,
diff --git a/tests/pipelines/stable_unclip/test_stable_unclip_img2img.py b/tests/pipelines/stable_unclip/test_stable_unclip_img2img.py
index 5f9ee5a5eaf6..f30f61efcf99 100644
--- a/tests/pipelines/stable_unclip/test_stable_unclip_img2img.py
+++ b/tests/pipelines/stable_unclip/test_stable_unclip_img2img.py
@@ -12,9 +12,15 @@
CLIPVisionModelWithProjection,
)
-from diffusers import AutoencoderKL, DDIMScheduler, DDPMScheduler, StableUnCLIPImg2ImgPipeline, UNet2DConditionModel
+from diffusers import (
+ AutoencoderKL,
+ DDIMScheduler,
+ DDPMScheduler,
+ StableUnCLIPImageNormalizer,
+ StableUnCLIPImg2ImgPipeline,
+ UNet2DConditionModel,
+)
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
-from diffusers.pipelines.stable_diffusion.stable_unclip_image_normalizer import StableUnCLIPImageNormalizer
from ...testing_utils import (
assert_tensors_close,